cd /news/machine-learning/it-s-easy-to-dismiss-jev-as-just-a-c… · home topics machine-learning article
[ARTICLE · art-135188] src=sebastianraschka.com ↗ pub= topic=machine-learning verified=true sentiment=· neutral

It's Easy to Dismiss Jev as Just a Classifier

Sebastian Raschka argued in a blog post that Jev, the system-one model from Typesafe.ai, should not be dismissed as "just a classifier," crediting its generalization across tasks such as classifying emails, playing video games, and trading stocks. Raschka guessed the undisclosed model is a small encoder-style architecture like ModernBERT trained with a method similar to Reinforcement Learning with Calibration Reward from the paper "Beyond Binary Rewards: Training LMs to Reason About Their Uncertainty," and said the secret sauce is probably more in the data than the training algorithm. He compared the moment to Stable Diffusion and the 2022 ChatGPT launch, where improved data made the difference.

read2 min views17 publishedSep 20, 2026
It's Easy to Dismiss Jev as Just a Classifier
Image: Sebastianraschka (auto-discovered)

It’s easy to hype and dunk on Jev. I saw a lot of interesting demos in the last few days. And I also read a lot of dismissals in the last few days. I think the truth lies somewhere between these two extremes.

I.e., it’s easy to dismiss Jev as “just a classifier.”

The exact model and training algorithm are not disclosed. But if I had to make an educated guess, it’s likely:

  1. a small encoder-style model like (Modern)BERT ;
  2. trained with something similar to Reinforcement Learning with Calibration Reward (from the Beyond Binary Rewards: Training LMs to Reason About Their Uncertainty paper).

Many people (me included) have been training encoder-style models for classification for many years. Fact is that they were usually special-purpose and limited in some way.

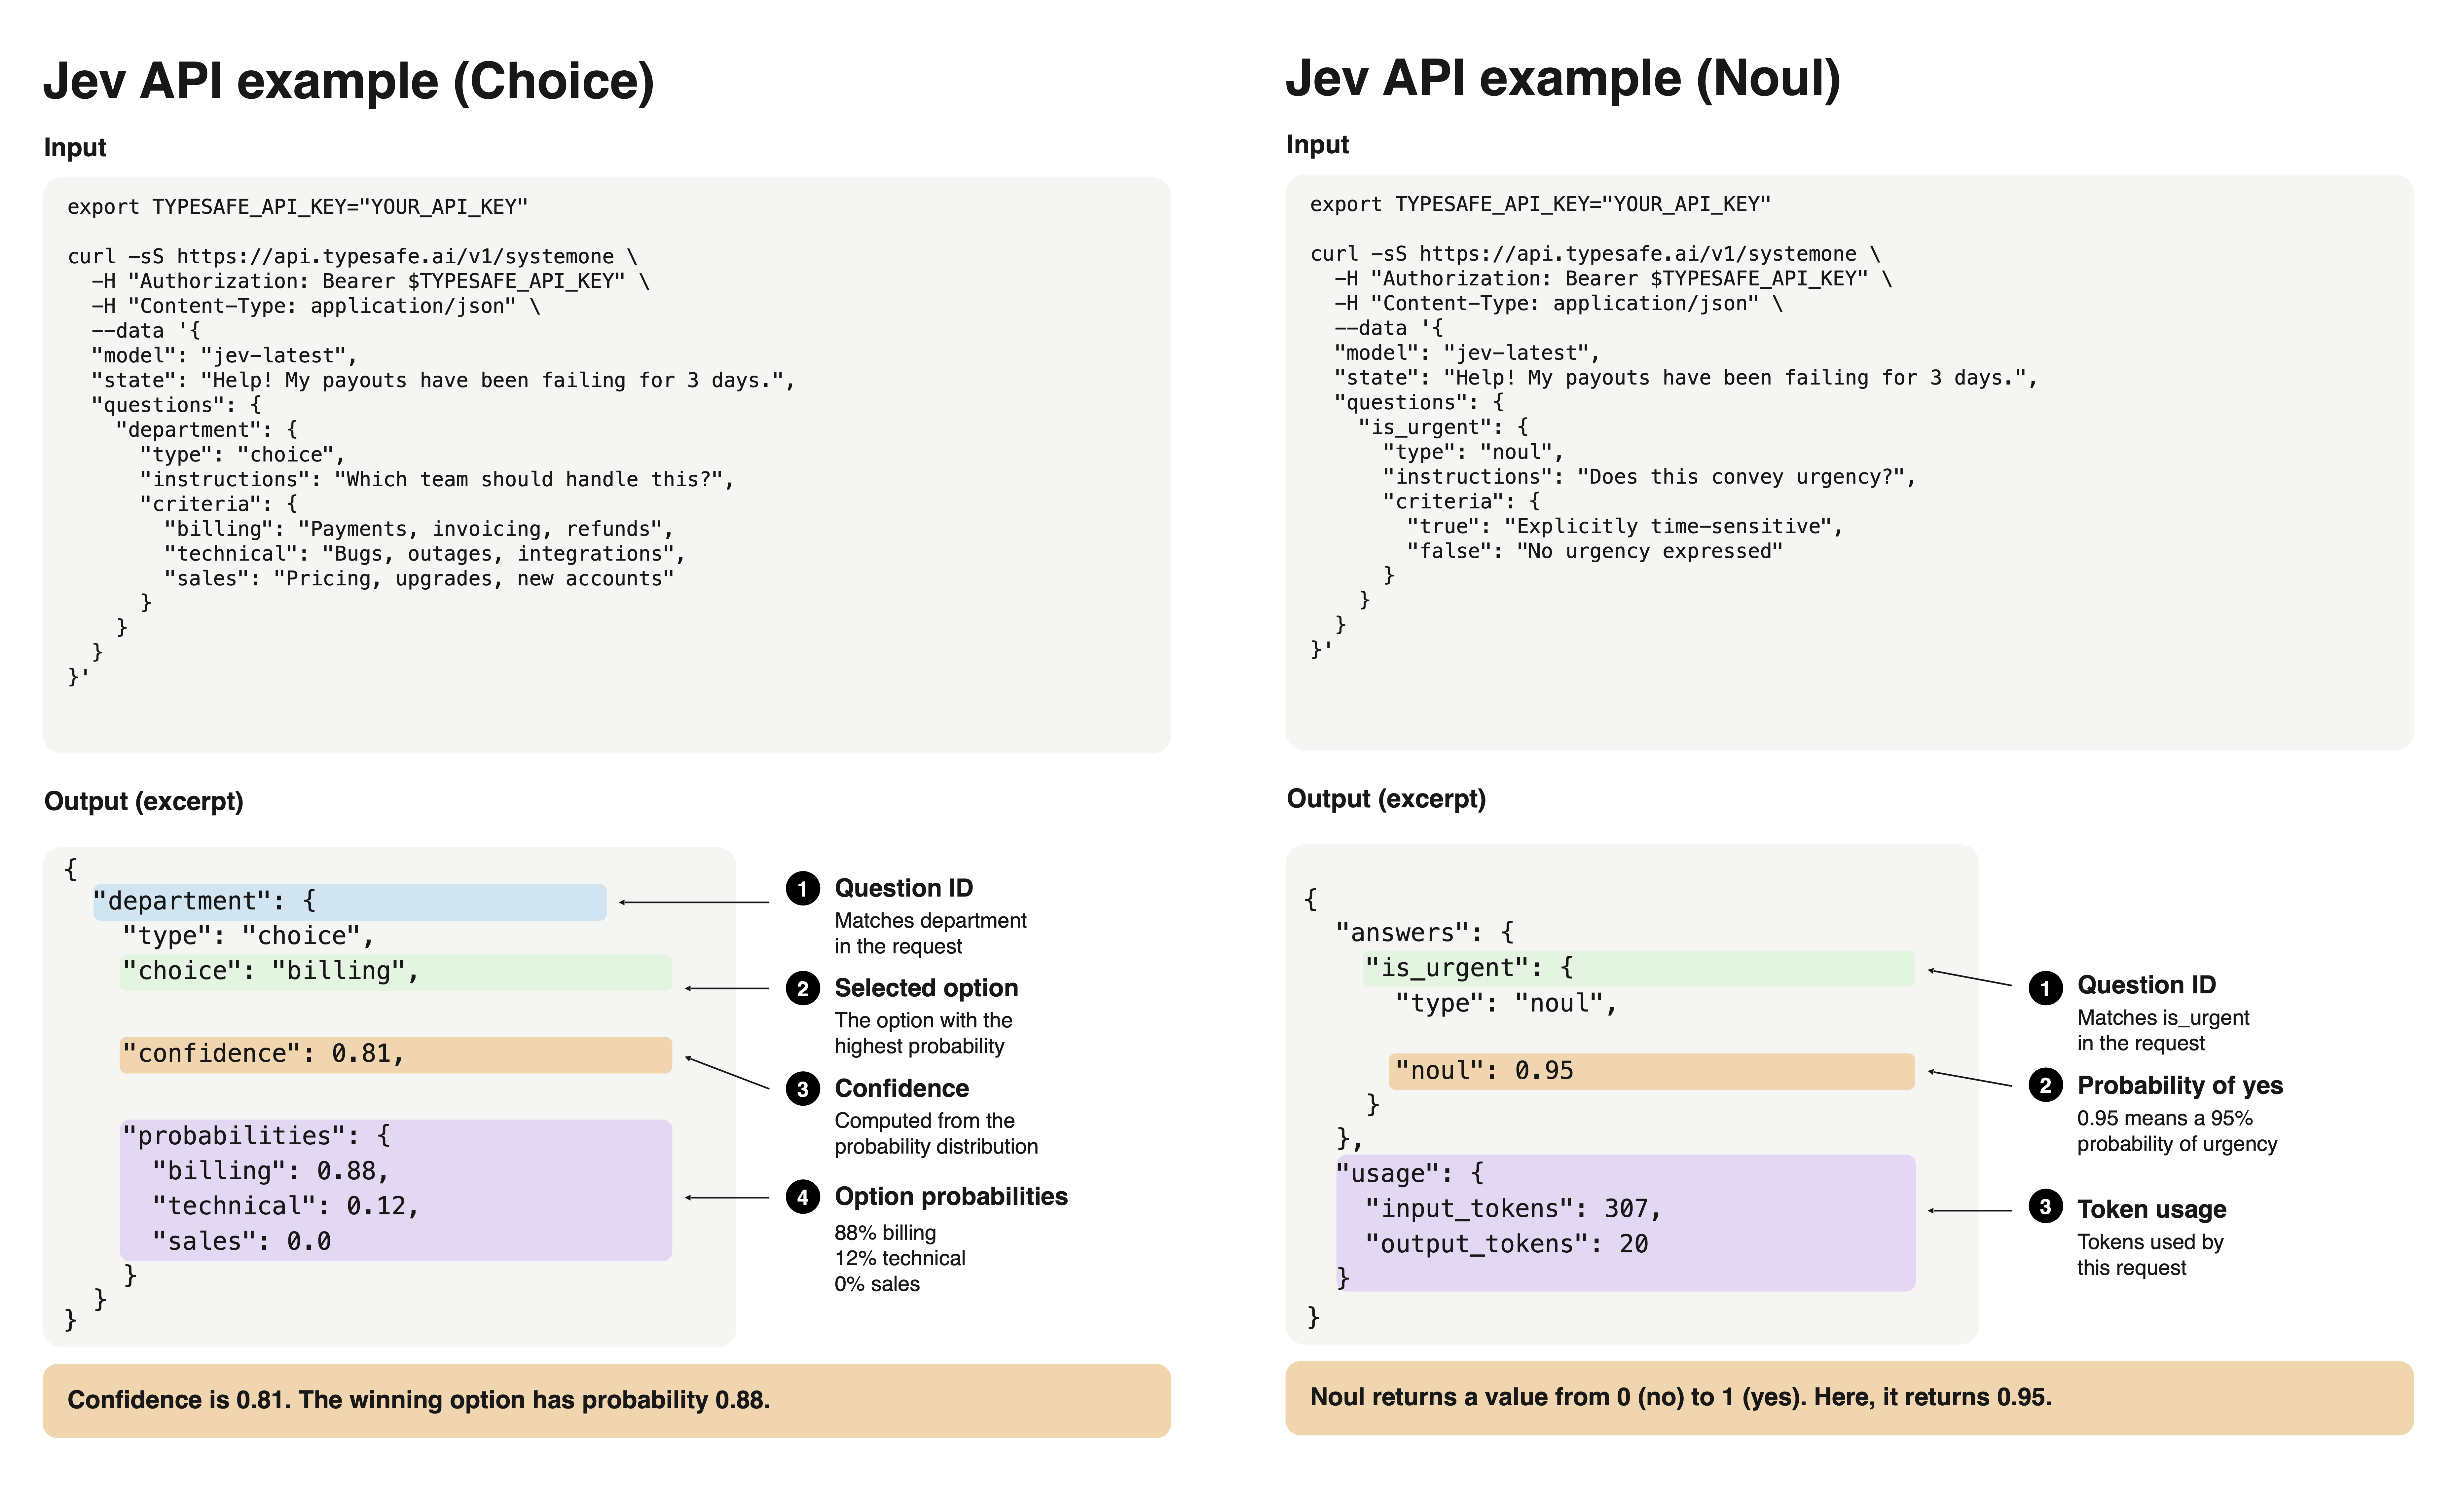
Jev’s impressive breakthrough is that it generalizes so well (you can use it to classify emails, play video games, trade stocks…).

And I’d say the secret sauce is probably more in the data than in the training algorithm. (Plus a nice API design on top of it.)

Yeah, it’s not the first project where someone applied RL to a (likely) non-autoregressive, encoder-style model.

But what’s impressive is that it works and generalizes so well, which can make all the difference. I.e., we saw the same thing with Stable Diffusion (based on an existing research paper) not too long ago, or even with the 2022 ChatGPT launch itself (an improved version of InstructGPT, where the data made all the difference).

Source: website version of my LinkedIn post.

Pacing != Pacing Development My take on AI model pacing as a framework for release checks and the competitive pressure around model releases.

AI Reasoning Models Course on LinkedIn Learning A 90-minute LinkedIn Learning course on how reasoning models relate to conventional LLMs and how they are developed.

OpenAI Astra and Looped Transformers A short note on OpenAI Astra, recurrent depth, looped transformers, Nanbeige 4.2, and the Mixture-of-Recursions paper.

── more in #machine-learning 4 stories · sorted by recency
── more on @jev 3 stories trending now
sponsored brought to you by zahid.host 4,200+ EU-deployed projects
reading about agents? ship yours in a single git push.

Run your AI side-project on zahid.host

EU-based hosting, git-push deploys, automatic HTTPS, no cold starts. Free tier with a custom domain — perfect for shipping the agent you just read about.

$git push zahid main
Live at https://your-agent.zahid.host
Get free account → Pricing
from €0/mo · no card required
LIVE [news/it-s-easy-to-dismiss…] indexed:0 read:2min 2026-09-20 ·