Index
A reference benchmark of how much each AI writes like AI slop.
Measured by machine and by blind human vote.
Have you ever gotten an email that opened with “I hope this finds you well,” offered exactly three tidy bullet points, and closed by inviting you to not hesitate? You knew.
            Everyone knows. Every frontier model can write; the question is whether it writes like a **person** or
            like **AI slop**.
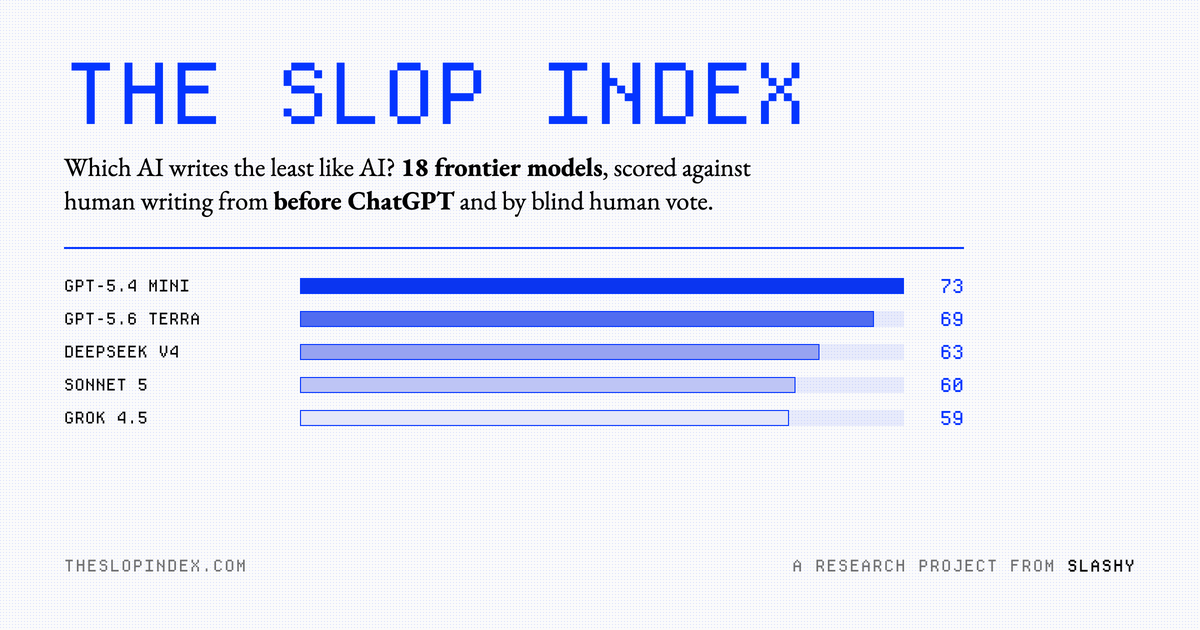
The index at right is the live answer. Thirty-nine frontier models, scored against genuine human writing collected before ChatGPT existed, and by a blind human vote that anyone can join. Higher means the writing reads more like a chatbot, so #1 is the sloppiest model on the board. No LLM judges anything.
a live benchmark
You already know it when you read it #
The underlined phrases are among the tells the index counts, each measured against how often real people actually used it before 2022, not against a model’s guess.
No LLM judges. No vibes. Just measurement. #
Slop is distance from genuine human writing collected before ChatGPT existed, so no model could have
            shaped the yardstick. The corpus: real workplace email from 2000–2002, tweets from before 2022, essays
            and chat logs that predate generative AI entirely. Every number is mechanical, plus one big input:
            **people**.
Think you can spot the slop? #
The board is the machine’s verdict. The arena collects yours: two blind samples from the same task, one sloppier than the other. Every vote moves the live human axis of the score.