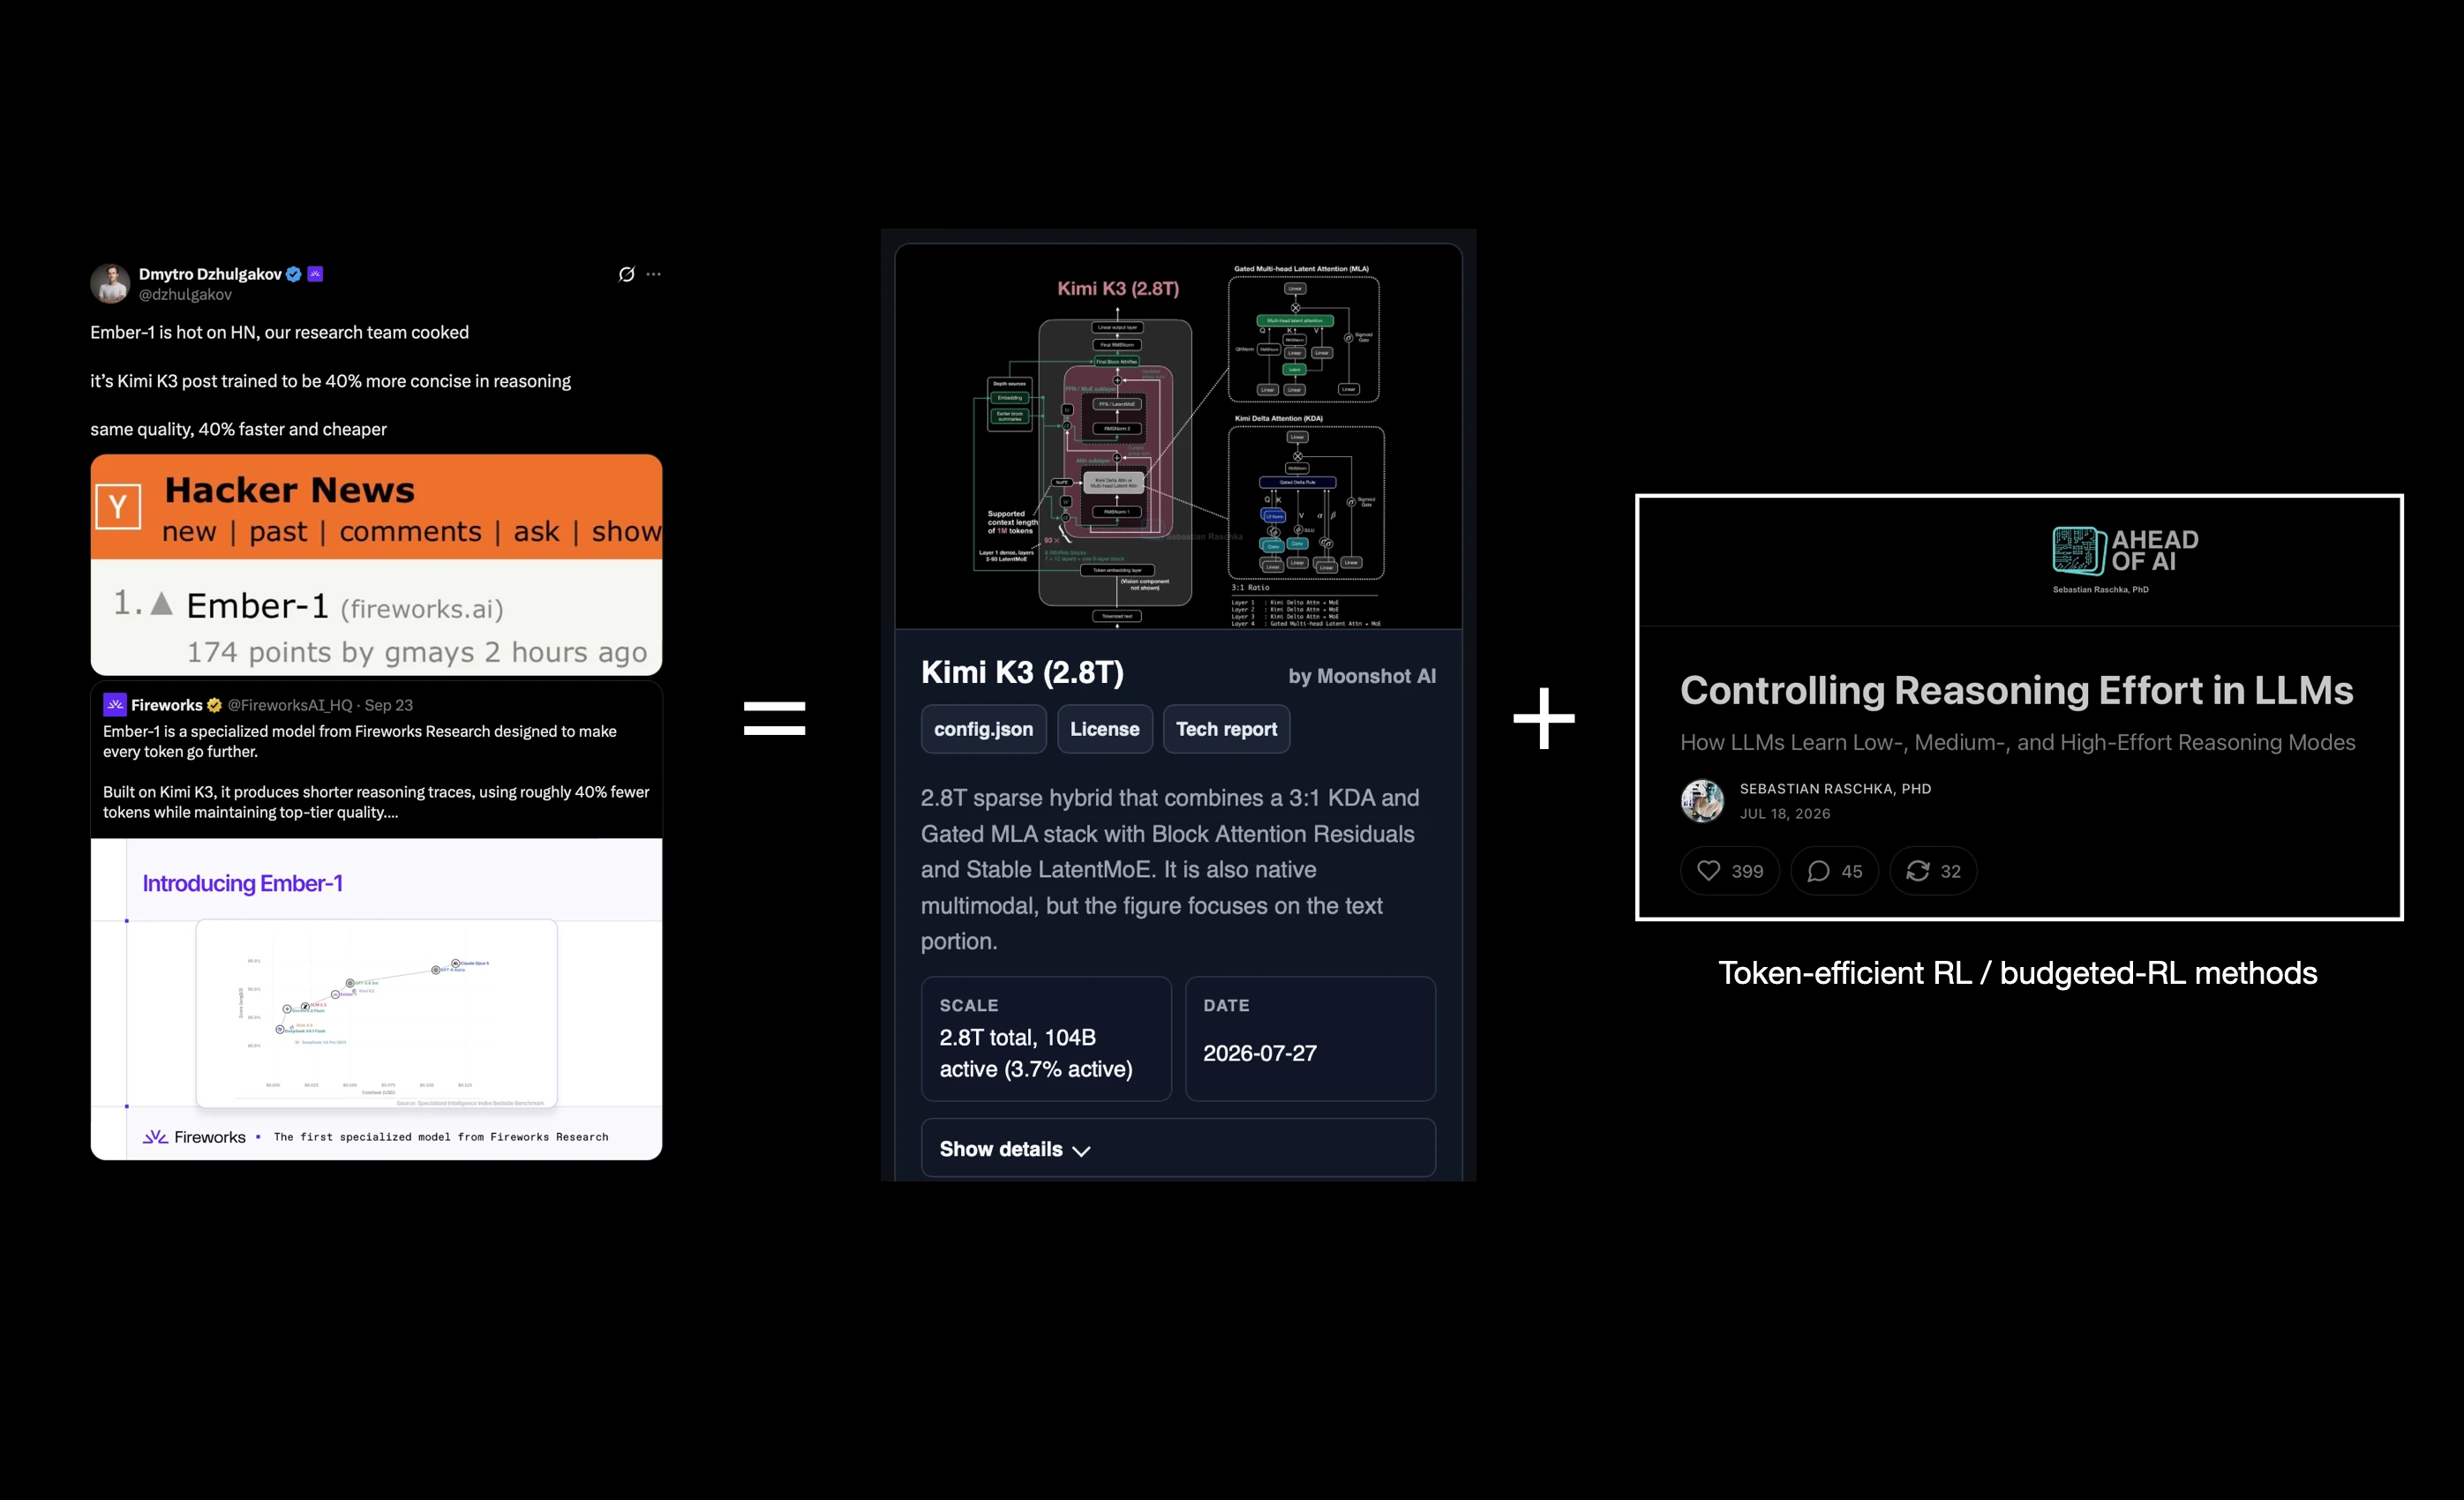
Ember-1 is a nice example of what can be built on top of an existing open-weight LLM. Fireworks started with Kimi K3 and post-trained it to produce shorter reasoning traces. According to the Fireworks announcement, Ember-1 uses roughly 40% fewer tokens while maintaining comparable quality across their evaluations.
I was recently spontaneously asked on a podcast, given an imaginary multi-million dollar budget, how I would approach developing a frontier LLM with a limited budget. My recommendation was to start with an existing model and spend that budget on post-training. (Here’s a link, but sorry, it’s in German; my only German podcast.)
The point is, even millions of dollars is not a lot for training a competitive LLM at the frontier (500B parameters or larger). And given that there is such a strong and good selection of open-weight models out there, there is currently no reason to spend all that money on duplicating pre-training efforts.
Ember-1 is a concrete example of the kind of improvement I had in mind. Sure, here they only focused on efficiency while maintaining existing capabilities, but a 40% reduction in token use is a lot. (Another angle could be maintaining the current efficiency level of an existing model but pushing its capabilities in newer harnesses, for example.)
How did they achieve the 40% reduction in token use? They trained the model to produce shorter reasoning traces. This connects to the token-efficient and budgeted reinforcement learning methods I covered in Controlling Reasoning Effort in LLMs.
The general idea is to make token usage part of the training objective. For example, we can specify a reward that factors in both answer correctness and response length, or encourages correct solutions within a specified token budget. The challenge is to reduce unnecessary reasoning while retaining the ability to work through difficult problems.
That’s the connection I wanted to illustrate in the figure below. (But please note that Fireworks hasn’t disclosed enough of Ember-1’s training recipe to identify the exact algorithm, so the connection to those methods is conceptual.)
PS: I am not affiliated with Fireworks in any way; I just thought that this was an interesting case study.