cd /news/large-language-models/from-full-to-hybrid-attention-in-llm… · home › topics › large-language-models › article
[ARTICLE · art-167101] src=sebastianraschka.com ↗ pub= topic=large-language-models verified=true sentiment=· neutral

From Full to Hybrid Attention in LLMs

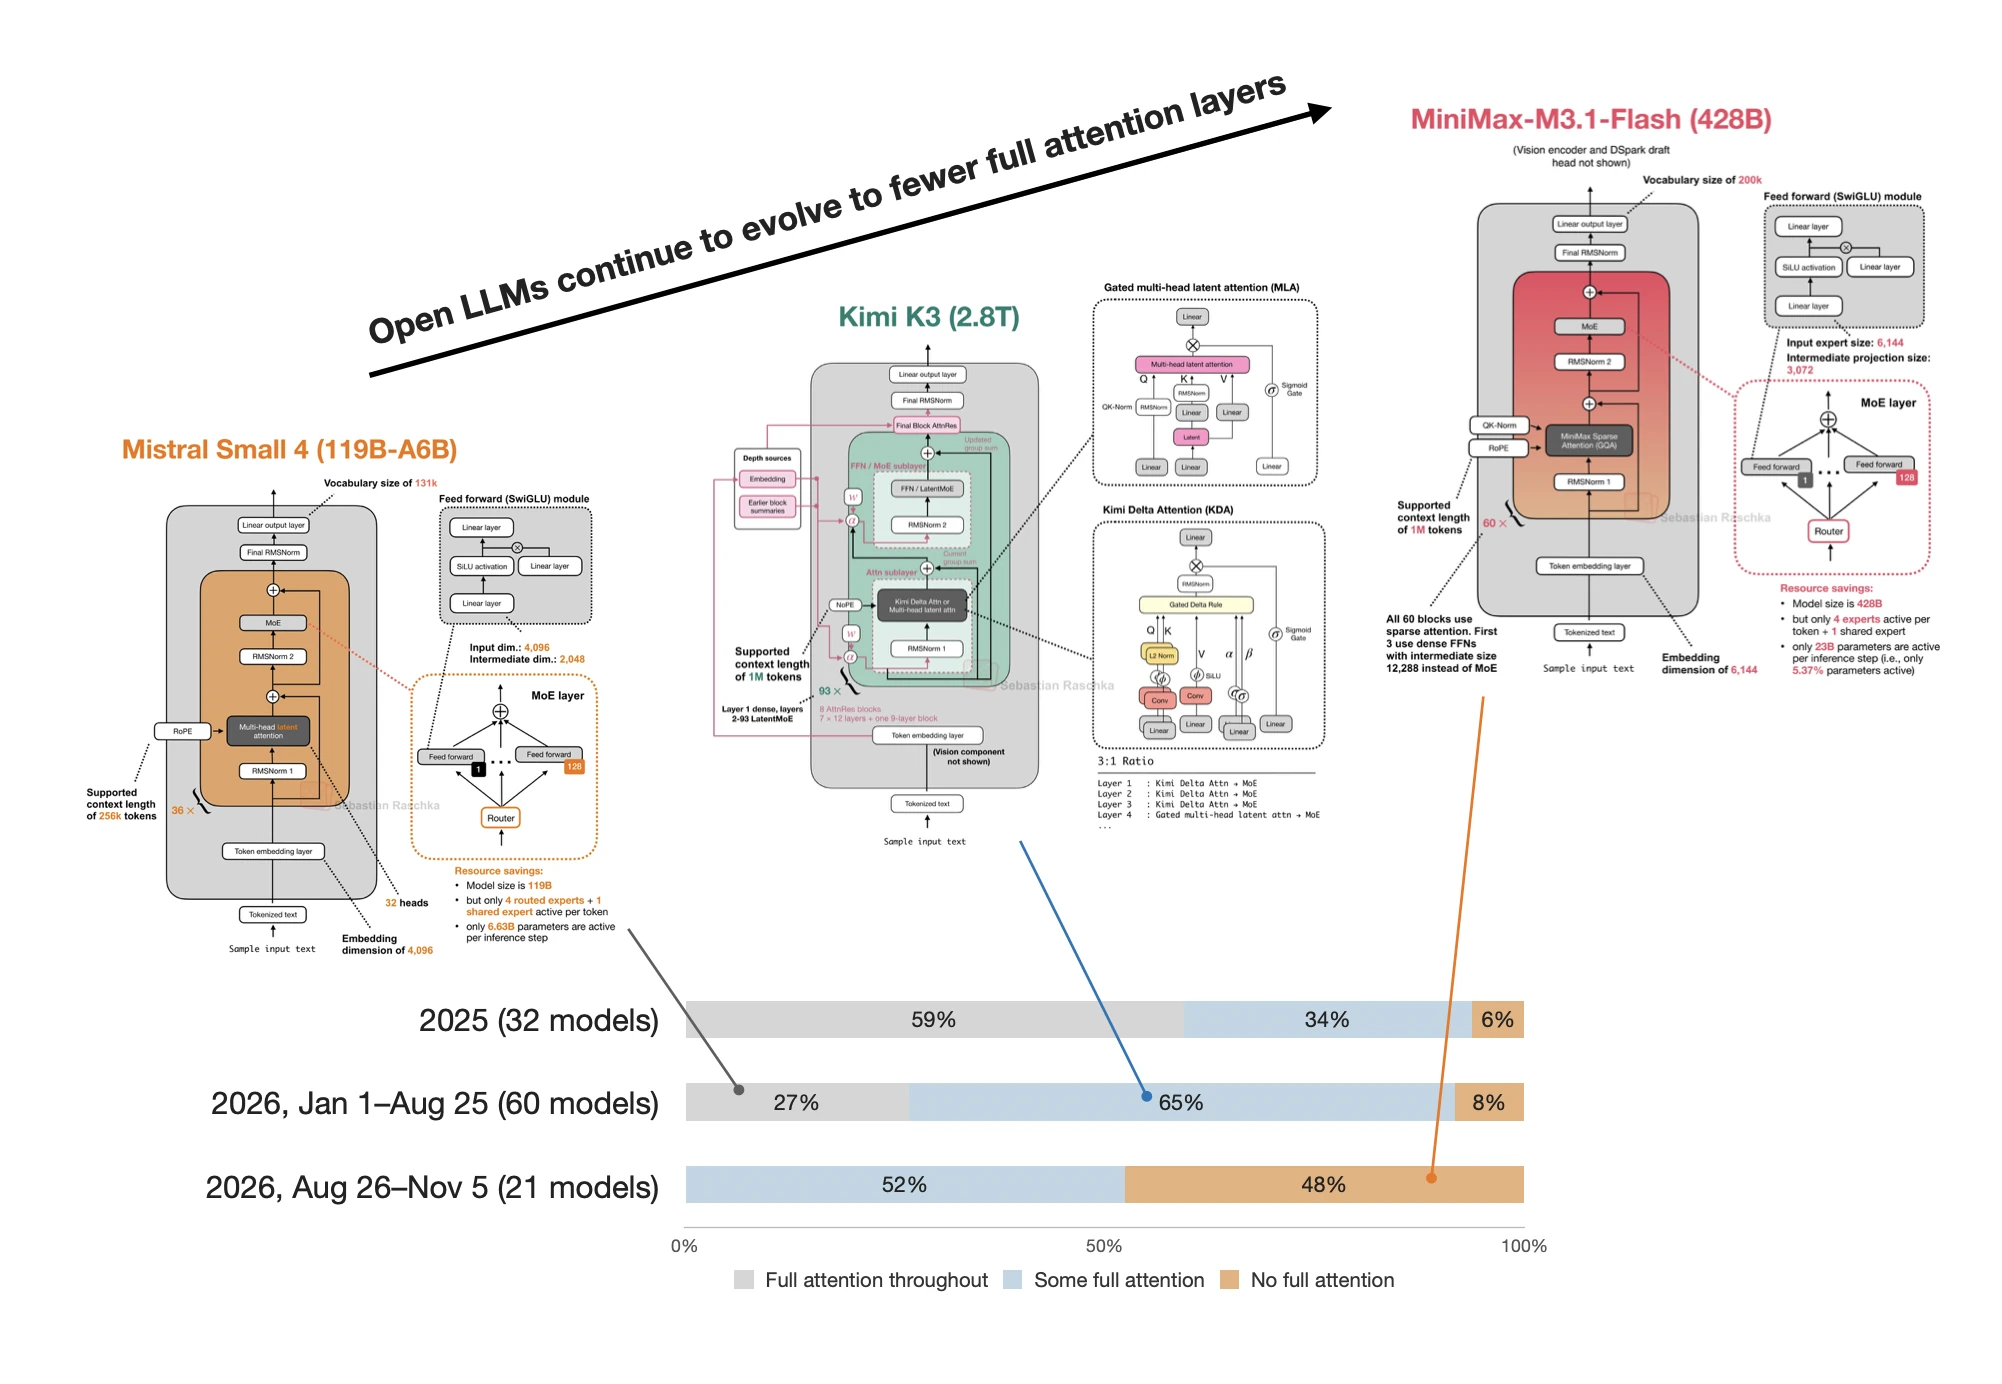
In the second half of 2026, half of new open LLMs use no full attention at all, and the remaining half mix full global attention with sliding-window, Gated DeltaNet, KDA, Mamba-2, Lightning Attention, convolution or sparse layers, according to an analysis by Sebastian Raschka. The shift away from full attention throughout — global MHA, GQA, dense MLA or CCA in every layer — follows 2025's move to "some full attention" hybrids and continued through the first half of 2026, and Raschka attributes it to making long contexts cheaper: sparse attention cuts attention computation by selecting token or block subsets, while recurrent layers such as Gated DeltaNet hold a fixed-size state to save memory at the cost of exact retrieval.

read2 min views3 publishedNov 10, 2026
From Full to Hybrid Attention in LLMs
Image: Sebastianraschka (auto-discovered)

Currently working towards a bigger open LLM roundup. But in the meantime, just one of the interesting trends that stood out. I.e., looks like the transition from full to hybrid attention continues.

In 2025, there were still lots of full attention models, with a shift to “some full attention” hybrids.

In the first half of 2026, the trend towards “some full attention” hybrids continued.

And now, in the second half of 2026, we have a 50/50 split between “some full attention” hybrids and models that don’t use full attention at all anymore. And yes, there are also no full attention models anymore.

The plot legend here means,

Full attention throughout = Global MHA, GQA, dense MLA, CCA in EVERY layer. #

Some full attention = Full global attn mixed with: sliding-window/chunked attention, Gated DeltaNet, KDA, Mamba-2, Lightning Attention, convolutions, sparse attention. #

No full attention = Zero dense global layers.

The main implication is that the trend goes towards making long contexts cheaper to use. This means, it makes the architectures more suitable for long documents and conversations, large code bases, and of course agent use cases that rely on a lot of tool calls.

In particular, there are two distinct efficiency gains here:

Less attention computation, since sparse attention and the like select tokens or blocks from the context and perform the expensive attention operation from only that subset. (Note that it can still retrieve information from distant positions.) 2. Less memory for retaining context in some architectures, meaning that recurrent layers such as Gated DeltaNet maintain a fixed-size state. Of course, this saves memory, but compressing the history creates challenges for exact retrieval, so they are usually intermixed with traditional attention methods (sparse or full).

Source: lightly edited website version of my Substack note.

Open October LLM Architecture Roundup A roundup of ten open-weight LLM architecture releases from October 2026, covering attention mechanisms, hybrid layers, and MoE designs.

Focusing on Post-Training Why I'd invest in post-training existing open-weight LLMs, with Fireworks' Ember-1 as an example of more token-efficient reasoning.

MiMo-V2.6 Pro Architecture and Training Notes Notes on MiMo-V2.6 Pro's GQA and sliding-window attention, agent training tasks, reward signals, and large RL batches.

── more in #large-language-models 4 stories · sorted by recency
── more on @sebastian raschka 3 stories trending now
sponsored brought to you by zahid.host 4,200+ EU-deployed projects
reading about agents? ship yours in a single git push.

Run your AI side-project on zahid.host

EU-based hosting, git-push deploys, automatic HTTPS, no cold starts. Free tier with a custom domain — perfect for shipping the agent you just read about.

$git push zahid main
→ Live at https://your-agent.zahid.host ✓
Get free account → Pricing
from €0/mo · no card required
LIVE [news/from-full-to-hybrid-…] indexed:0 read:2min 2026-11-10 · —