cd /news/ai-infrastructure/show-hn-inference-stack-everything-y… · home › topics › ai-infrastructure › article
[ARTICLE · art-174024] src=inferencestack.io ↗ pub= topic=ai-infrastructure verified=true sentiment=↑ positive

Show HN: Inference Stack – Everything you need to own your inference

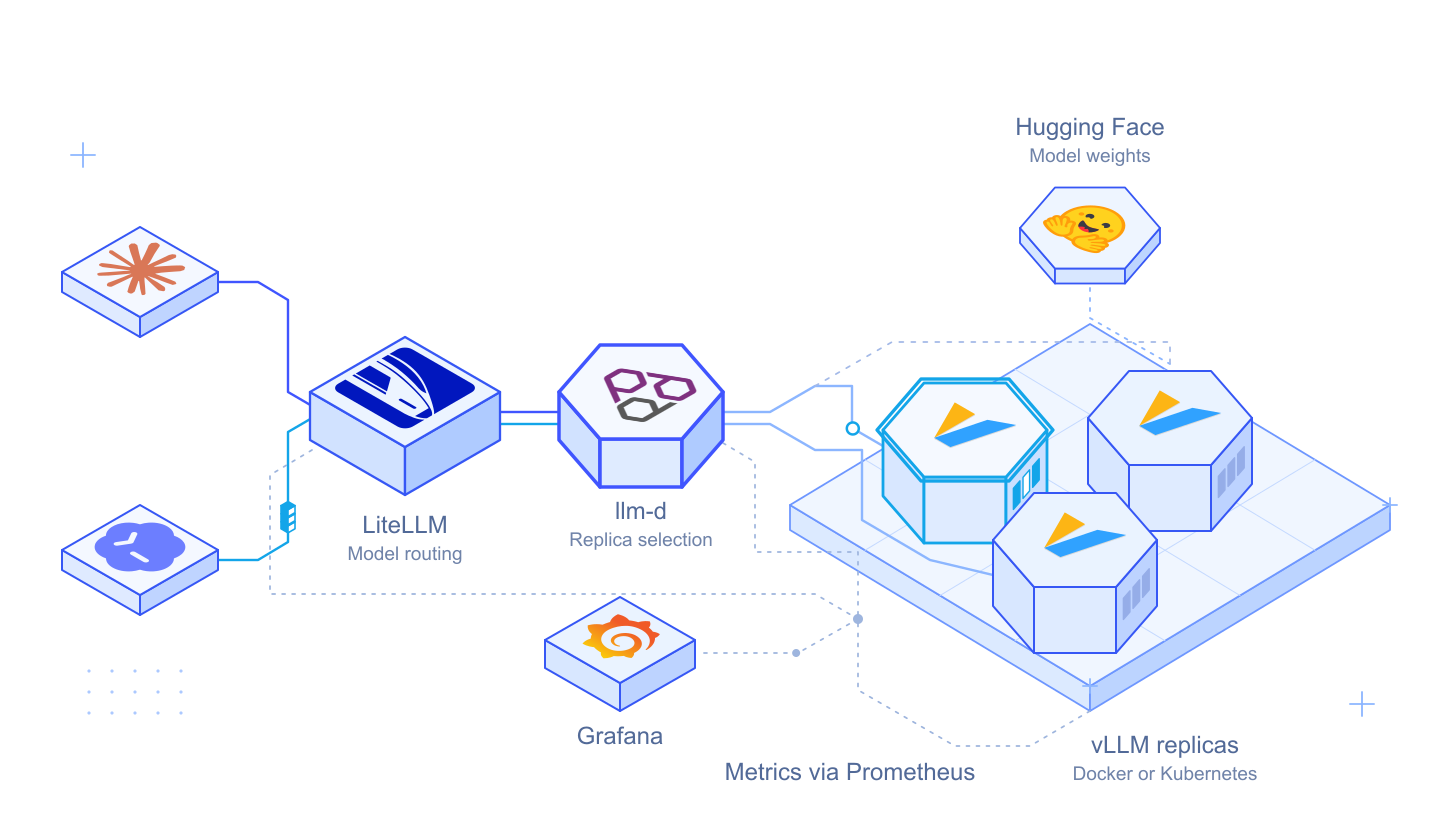
BerriAI released Inference Stack v0.1.2, an open-source package that lets teams run their own model inference by bundling vLLM for GPU serving, LiteLLM for a single API gateway with keys, teams and budgets, and Prometheus-backed dashboards. The stack installs with one curl command on a single machine running Docker Compose, curl and OpenSSL, then serves a launcher at localhost:8080 where an admin signs in with a generated password, picks a model in vLLM, deploys it and sends prompts through the LiteLLM Playground. Real models require NVIDIA GPUs; without one, users can enable simulation in a model's Settings for canned responses, and the LiteLLM router selects a vLLM replica per request using cache and queue data.

key takeaway

Inference Stack v0.1.2 bundles vLLM serving, a LiteLLM gateway with per-request replica routing based on cache and queue data, and Prometheus dashboards into a single Docker Compose install that runs on one machine with NVIDIA GPUs.

read1 min views2 publishedNov 22, 2026
Show HN: Inference Stack – Everything you need to own your inference
Image: source

vLLM

Search Hugging Face, check GPU requirements, and deploy from the launcher. vLLM runs the model on your GPUs.

vLLM docs

Everything you need to own your inference.

Deploy with one command.

For one machine. Requires Docker with Compose, curl, and OpenSSL. Setup details

curl -fsSL https://github.com/BerriAI/inference-stack/releases/download/v0.1.2/install.sh | bash -s -- docker

Open localhost:8080 and sign in as admin with the generated password. Choose a model in vLLM, deploy it, then open LiteLLM → Playground to send a prompt.

Real models need NVIDIA GPUs. No GPU? Enable simulation in the model’s Settings for canned responses.

Send requests through one API. Create keys, manage teams and budgets, or try a model in the Playground.

Selects a vLLM replica for each request using cache and queue data. Routing works by default; adjust the weights when you need to.

See model health, request traffic, and response times in the included dashboards. Metrics come from Prometheus.

── more in #ai-infrastructure 4 stories · sorted by recency
── more on @berriai 3 stories trending now
sponsored brought to you by zahid.host 4,200+ EU-deployed projects
reading about agents? ship yours in a single git push.

Run your AI side-project on zahid.host

EU-based hosting, git-push deploys, automatic HTTPS, no cold starts. Free tier with a custom domain — perfect for shipping the agent you just read about.

$git push zahid main
→ Live at https://your-agent.zahid.host ✓
Get free account → Pricing
from €0/mo · no card required
LIVE [news/show-hn-inference-st…] indexed:0 read:1min 2026-11-22 · —