cd /news/large-language-models/pre-training-is-still-not-plateauing · home › topics › large-language-models › article
[ARTICLE · art-174383] src=sebastianraschka.com ↗ pub= topic=large-language-models verified=true sentiment=↑ positive

Pre-training is (still) not plateauing

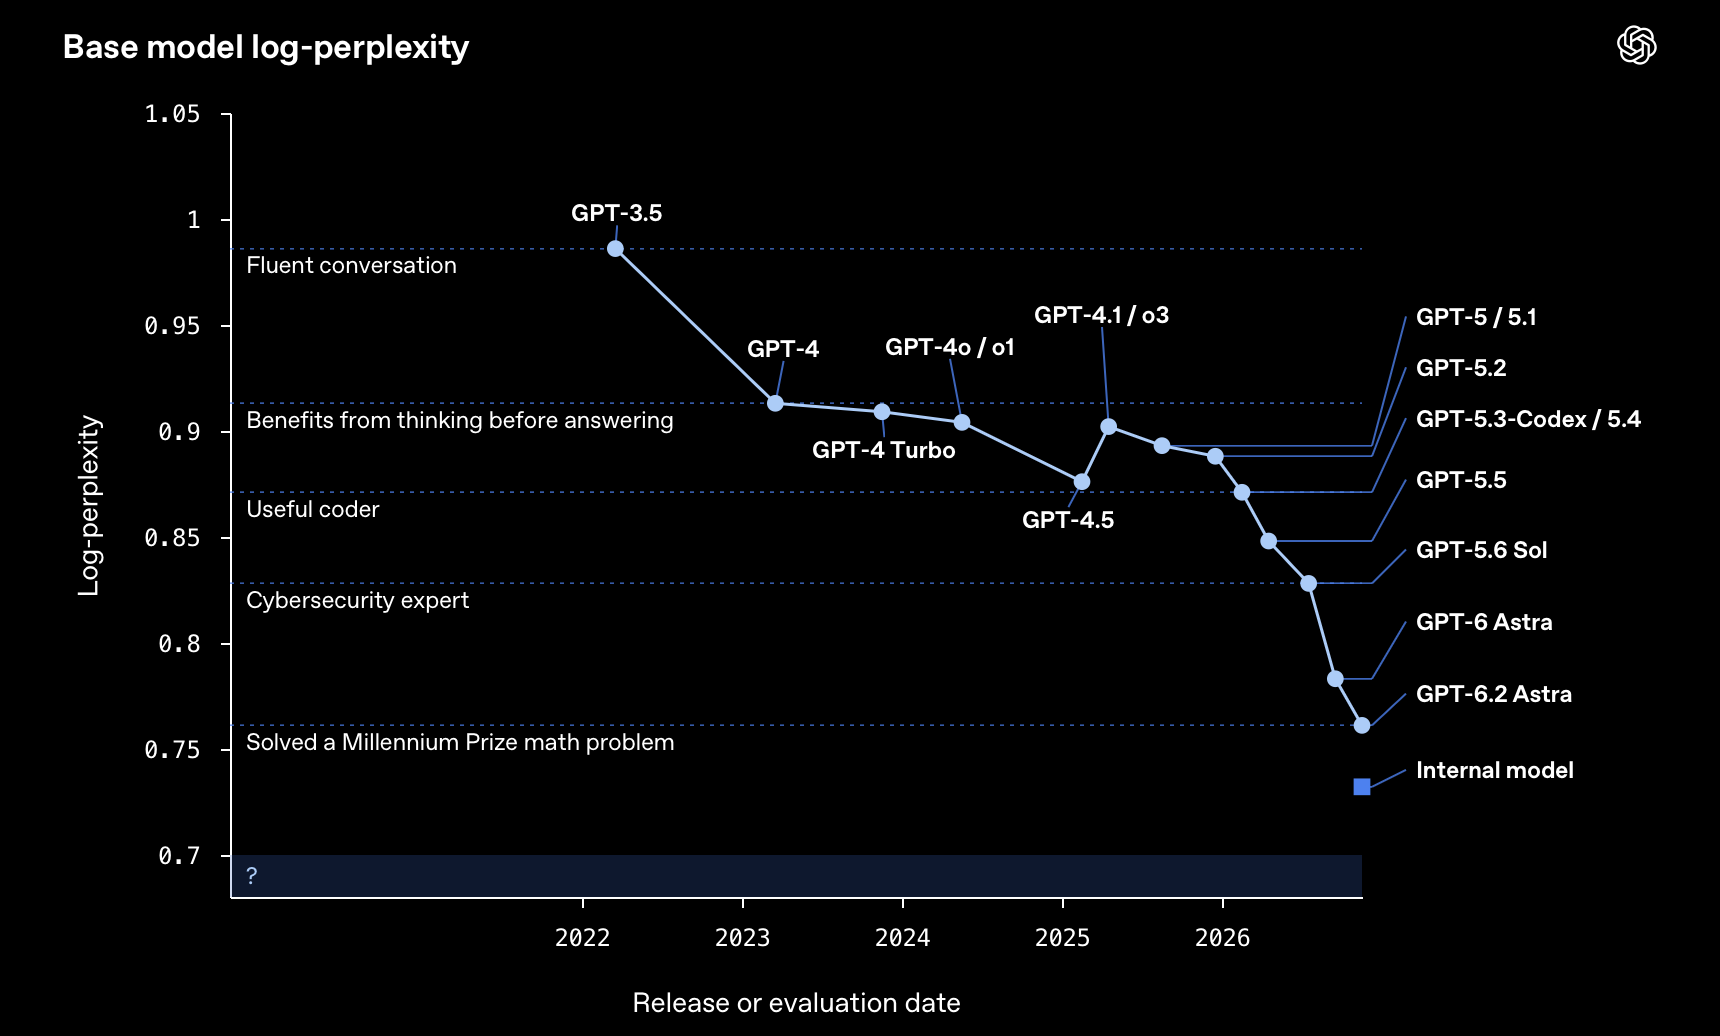
OpenAI has published data showing that pre-training loss, measured as log-perplexity on next-token prediction, continues to decline rather than plateauing, according to Sebastian Raschka's analysis of the chart. Raschka called the disclosure "great and rare transparency from OpenAI" and said pre-training remains essential because it equips a model with knowledge that post-training (supervised fine-tuning and reinforcement learning with verifiable rewards) later unlocks and an agent harness applies. Raschka said he would still like to see the same plot with training FLOPs on the x-axis and expects the big labs to keep investing in pre-training even as attention stays on RLVR for reasoning.

key takeaway

OpenAI's log-perplexity curve shows next-token pre-training loss still falling, and that metric continues to track perceived real-world model performance even as RLVR and harness engineering absorb most attention.

read2 min views3 publishedNov 22, 2026
Pre-training is (still) not plateauing
Image: Sebastianraschka (auto-discovered)

Finally, there is some information from one of the closed labs that backs up the fact that pre-training is not plateauing. (This is great and rare transparency from OpenAI.)

As I kept saying last year, pre-training is not plateauing, but it’s boring. Reinforcement learning with verifiable rewards (RLVR) for reasoning and agent harness was where most of the attention was.

Still, pre-training is super important to establish the foundation for later progress via RLVR and harness engineering. I.e.,

  • pre-training equips the model with knowledge,
  • and post-training (supervised fine-tuning and RLVR) lets the model access the knowledge
  • and the harness lets the model apply that knowledge.

Note that the chart above reports log-perplexity, which is a next-token prediction metric (not a task-solving success metric). It’s fascinating how well it (still) correlates with perceived real-world performance, though.

(How do we compute perplexity? Take the sentence “I really like chocolate”. We give the model “I really like” and look up the probability it assigned to “chocolate” as the next token. We do that for each target token, take the negative natural log of each probability, and average the results. That’s the cross-entropy loss, or log-perplexity on the chart. (I have a longer section, with hands-on coding examples in both my LLMs from Scratch and Reasoning From Scratch books in case you are new to it and want to build a solid intuition and understanding.)

Now, I’d still love to see the same plot with training FLOPs on the x-axis.

Anyways, I expect the big labs to keep investing in pre-training. It won’t be the flashy and sexy work people will talk about (like RLVR in 2025 & 2026), but some of the gains may still come from this fairly boring work, like figuring out how much code to put in the training mix.

What is perplexity, and what does it actually tell us about an LLM? Perplexity is the exponential of average next-token cross-entropy and measures how much probability an LLM assigns to a specific evaluation corpus.

Pre-Training Without Learning Rate Decay A quick comparison of LLM pre-training recipes using cosine decay, warmup-stable-decay, or constant learning rates with checkpoint averaging.

How are input-target training examples constructed for LLM pretraining? LLM pretraining examples use L+1 consecutive tokens to form an L-token input and the same sequence shifted by one position as the L next-token targets.

── more in #large-language-models 4 stories · sorted by recency
── more on @openai 3 stories trending now
sponsored brought to you by zahid.host 4,200+ EU-deployed projects
reading about agents? ship yours in a single git push.

Run your AI side-project on zahid.host

EU-based hosting, git-push deploys, automatic HTTPS, no cold starts. Free tier with a custom domain — perfect for shipping the agent you just read about.

$git push zahid main
→ Live at https://your-agent.zahid.host ✓
Get free account → Pricing
from €0/mo · no card required
LIVE [news/pre-training-is-stil…] indexed:0 read:2min 2026-11-22 · —