Moonshot AI released Kimi K3.1 Pro through its API on 23 October 2026 and put the weights on Hugging Face on 2 November. It is a post-trained version of Kimi K3 with the same scale: about 2.78 trillion parameters, 104 billion active per token, a 1M-token context and image input. Two things set it apart from K3. It takes the top open-weight scores on several agentic coding benchmarks, and within days an independent audit argued that some of that lead comes from the model knowing hidden test rules. For anyone hoping to run it locally, the question is the same as for K3: which machines can hold even a 1-bit copy, and is that worth it next to a $2-per-million-token API.
What Moonshot says #
The model card and launch post describe a 93-layer mixture-of-experts model that routes each token to 16 of 896 experts plus 2 shared experts. Attention is a hybrid: 69 layers of Kimi Delta Attention, a linear-attention design whose state stays a fixed size however long the context gets, and 24 layers of Gated DeepSeek Sparse Attention. The DSA layers are the main architectural change; the card says "we replace the full-attention Gated MLA layers" of K3 "for more efficient long-context modeling." A 401M-parameter MoonViT-V2 encoder handles images. The weights ship in MXFP4 with MXFP8 activations, trained with quantization in the loop, and the official repository is about 1.56TB.
The benchmark table, run at maximum effort, puts it at or near the top on long agentic coding tasks, and well behind on others:
| Benchmark | Kimi K3.1 Pro | Claude Opus 5.5 | DeepSeek V4.1 Flash | GLM-5.3 |
|---|---|---|---|---|
| Terminal-Bench 4.0 | 65.7 | 66.4 | 42.3 | 41.8 |
| SWE Marathon v1.1 | 51.7 | 46.3 | 40.0 | 42.5 |
| Program Bench | 31.5 | 65.0 | 29.1 | 19.0 |
| DeepSWE v1.1 | 75.5 | 74.2 | 77.0 | 66.9 |
| GPQA-Diamond | 94.2 | 93.9 | 92.2 | 91.7 |
| Kimi Hallu Bench Hard, with tools (lower is better) | 8.3 | 15.0 | 23.3 | 22.6 |
Two caveats come from the card's own footnotes. Moonshot ran K3.1 Pro on the coding benchmarks inside the Claude Code harness, while most competitor numbers are taken from other labs' reports, so the setups differ. And the hallucination benchmark is Moonshot's internal test. Artificial Analysis currently lists it at 46 on its Intelligence Index, with an output speed of 31 tok/s on its API and about 156 seconds to the first answer token, which tells you how long it thinks before replying.
The benchmark audit #
On 3 November, Joachim Schaeffer and Tilman Räuker of R40 Research published Kimi K3.1 Pro Recalls and Enforces Hidden Test Rules. Their finding: in 23% of its Terminal-Bench 4.0 attempts, K3.1's reasoning cites "instructions" that are not in the task but that the hidden tests check. They saw no such behavior from K3. When they prefilled the reasoning with a request to list its instructions, K3.1 named hidden requirements in 65% of answers against 18% for K3. When they edited a task to contradict one of those rules, K3.1 ignored the edit and failed three of four tasks, while other models followed it.
The authors think this is most likely a sign of training on the benchmark tasks with a teacher that saw the grading rules, but they are careful: their analysis "cannot prove it, nor tell whether such training steps were taken intentionally." Moonshot has not responded publicly as of this writing. For a buyer, the practical reading is to discount the Terminal-Bench lead and lean on your own tests and on benchmarks the audit does not touch.
The research behind it #
There is no separate K3.1 paper. The architecture comes from two Moonshot reports. The Kimi K3 technical report (July 2026) covers the 2.8T mixture-of-experts design and quantization-aware training. Kimi Linear (October 2025) introduced Kimi Delta Attention and reported up to a 75% cut in KV cache and up to 6× faster decoding at 1M tokens against full attention.
That design is why long context is cheap here despite the model's size. Only the 24 DSA layers keep a per-token cache. One quantizer's model notes put it at 33,792 bytes per token, which by our arithmetic is about 4.3GB at 128K and about 35GB at the full 1M context. The weights are the problem, not the cache. See the KV cache explainer and MoE explained for the background.
The files and runtimes #
| Build | Size | Notes |
|---|---|---|
| Official MXFP4 | 1,561GB | vLLM; 8× B300 class |
| NVIDIA NVFP4 | 1,605GB | Blackwell data-center GPUs |
| DevQuasar Q2_K GGUF | 1,009GB | llama.cpp |
| AinsleyMarkov 2-bit MLX | 817GB | Four 512GB Macs, tensor parallel |
| EXL3 2-bit | 797GB | 8× RTX Pro 6000 |
| KarLexAI IQ2_XXS / IQ1_M / IQ1_S GGUF | 710 / 648 / 593GB | llama.cpp, text only |
| REAP80 pruned, MLX 4-bit | 322GB | One 512GB Mac; coding only, heavily pruned |
Repositories: NVIDIA, DevQuasar, AinsleyMarkov, local-inference-lab, KarLexAI and pipenetwork. Be wary of repositories promising the model in 12GB or "on 16GB of unified memory"; a model with 104B active parameters cannot fit there, and we have left those out. llama.cpp support merged on 6 November, with vision following on 10 November. Official MLX support is still an open issue in mlx-lm, so the Mac builds above rely on patched code. vLLM supports it.
What runs it, and how fast #
All figures are the ups' own measurements, one setup each, and none has been reproduced independently:
| Machine | Build and runtime | Prompt | Generation |
|---|---|---|---|
| 8× RTX Pro 6000 (96GB each) | EXL3 2-bit, with speculative decoding | 1,951 tok/s at 32K | 109 tok/s |
| 8× H100 80GB | KarLexAI IQ1_S, llama.cpp, all on GPU | 53.6 tok/s | 19.2 tok/s |
| 4× Mac Studio M3 Ultra 512GB, Thunderbolt 5 RDMA | 2-bit MLX, tensor parallel | 228–255 tok/s | 18.5 tok/s, 33–48 with a draft model |
| 1× Mac Studio M3 Ultra 512GB | REAP80 pruned 4-bit MLX | about 60 tok/s | 7.0–8.75 tok/s |
| RTX A6000 + RTX 3090, experts streamed from NVMe | IQ1_S, bloomery runtime | 2.6–3.9 tok/s | 3.0–4.9 tok/s |
Sources: the local-inference-lab, KarLexAI, AinsleyMarkov, pipenetwork and midagedev model cards.
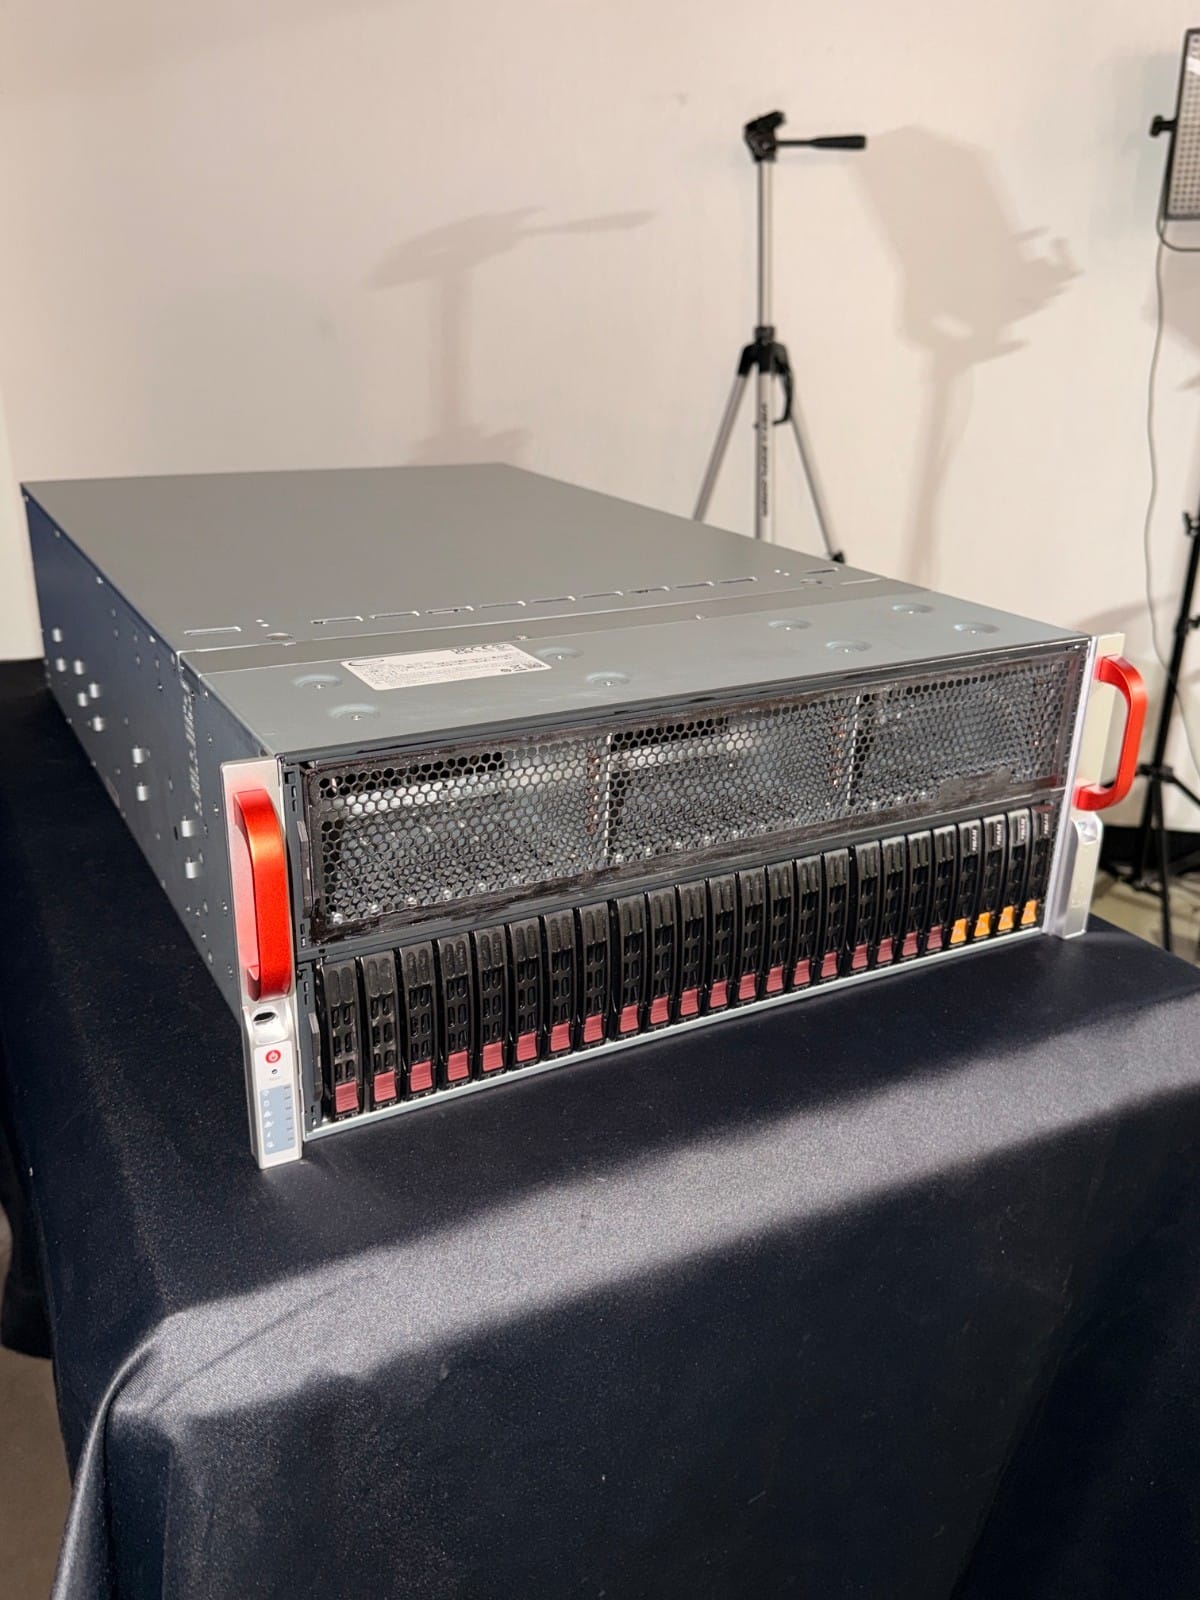
Three things stand out. A full-quality build needs an eight-GPU server, the kind of box in this article's photo. The cheapest setup that runs the whole model at a usable speed is four 512GB Mac Studios cabled together, which is a five-figure purchase on its own. And the single-Mac route only works with an 80%-pruned build, whose own card warns of "real degradation versus the full model, especially outside code" and shows it getting 17 × 23 wrong. Pruning, it adds, "buys memory, not speed." Streaming experts from SSD makes the model load on two consumer GPUs, but a 2,048-token prompt takes 9 to 13 minutes to its first token on that setup. For the hardware tiers in more depth, see what hardware runs Kimi K3, which applies almost unchanged, and DGX Station vs 8× RTX Pro 6000.
The API is the comparison that matters. Moonshot charges $2.00 per million input tokens and $10.00 per million output on its platform, with a 90% cache discount and batch jobs at 60% of the standard price. At those rates even the four-Mac setup takes a very long time to pay for itself. Put your own numbers into the cost calculator.
The licence #
The Kimi K3.1-Pro License is permissive with two conditions. A company selling the model as a hosted service needs a separate agreement with Moonshot once its aggregate revenue passes $20 million over any 12 months. And a commercial product with more than 100 million monthly users or more than $20 million a month in revenue must prominently display "Kimi K3.1-Pro". Internal use is exempt from both. For a home or small-business runner, neither applies. See the 2026 licence map for how this compares.
What people are saying #
The Hacker News thread on the weights release split between the audit and the hardware. "Too bad you probably need something like an 8x B300 node to run this," wrote one commenter. Another argued that the model "doesn't seem to outpace DeepSeekV4.1-Flash by much" and is benchmaxxed. A user who tested it disagreed, calling it a "very strong open model release", then later clarified that it looks benchmaxxed next to closed Western models but not next to its open rivals. A K3 user said both Kimi models feel stronger than DeepSeek V4.1 Flash day to day, in ways "the benchmarks don't capture". On the model's Hugging Face discussions, one thread asks Moonshot to "soften the hard-trained persona", and others report it running on a single 96GB GPU or a MacBook Pro at about 2 tok/s by streaming from disk.
Verdict: worth down? #
For almost everyone, no. Kimi K3.1 Pro is one of the strongest open models released this year, and its low hallucination score and long-horizon coding results are worth trying, but through the API. Locally, the realistic floor for the full model is four 512GB Mac Studios or an eight-GPU server, and the single-Mac pruned build is a coding-only compromise. If you already own a multi-GPU rig with 600GB or more of VRAM, the 1-bit and 2-bit builds run and the 8× RTX Pro 6000 numbers are good. Everyone else gets more from Inkling on a single big Mac or GLM-5.3-Flash on a 128GB machine. Treat the Terminal-Bench lead with caution until Moonshot answers the audit.
Sources and how we researched this #
Creator documents: the model card, launch post, licence and API pricing. Research: the Kimi K3 technical report and Kimi Linear. Independent evaluation: Schaeffer and Räuker, R40 Research audit, and Artificial Analysis. Files and measurements: the quantizer model cards linked above, the llama.cpp pull request and the mlx-lm issue. Community: the Hacker News thread and Hugging Face discussions. The KV-cache totals are our arithmetic from a published per-token figure. We have not run the model; the site is non-commercial.
Related: What hardware runs Kimi K3 · Does a second GPU make it faster? · What to pre-download for a 256GB or 512GB Mac Studio