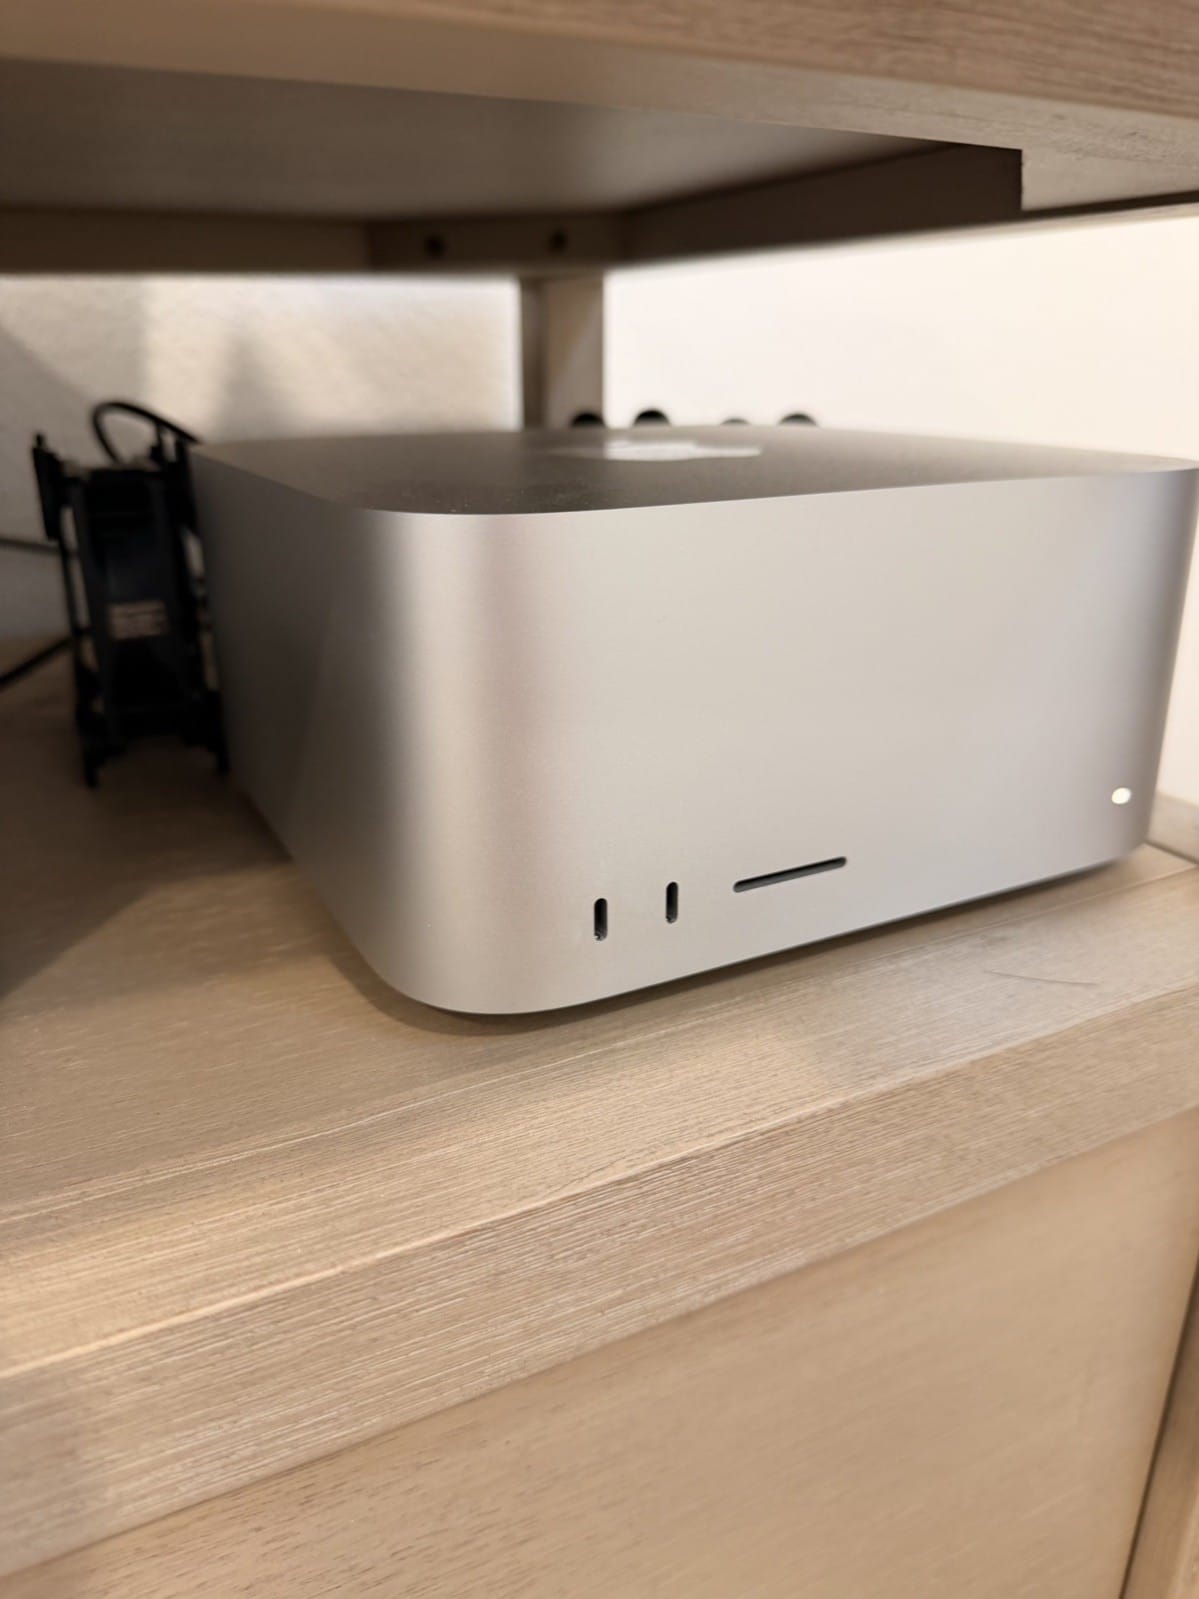
Thinking Machines announced Inkling 2 Small on 5 November 2026 as a model you could only use through its Tinker service, then published the weights on Hugging Face a week later under Apache 2.0. It is "small" only next to the original Inkling: 594 billion parameters, of which 17 billion are active per token, with image input and a 1M-token context. That combination is what makes it interesting for local hardware. A 594B model fits a 512GB Mac Studio at 4-bit and a 256GB Mac at 2-bit, and 17 billion active parameters is light enough to generate at a usable speed once it fits. It is also the largest model its makers know of that was trained natively in 4-bit precision, which changes how its quantized files should be read.
What Thinking Machines says #
The model card describes a 48-layer mixture-of-experts transformer in which "each token is routed to 8 of 384 experts", with no shared expert. Attention mixes 40 local layers that see a 1,024-token window with 8 global layers that see everything, using 8 key-value heads and no rotary position encoding. A 292-million-parameter vision encoder handles images, and a five-layer draft head ships alongside for speculative decoding. Reasoning effort is a dial from 0 to 0.99, defaulting to 0.9.
The launch post, Introducing Inkling 2 Small, reports pre-training on about 12 trillion tokens across stages that extended context to 512K and then 1M, and a single reinforcement-learning run of 1,075 steps on 2,048 GPUs. It is candid about weaknesses: the model is "not the most succinct communicator", is "less optimized for the chat experience", and "overuses slashes". The previous small model, Inkling Small, was 276B with 12B active, per Tinker's pricing page.
The card's benchmark table, all self-reported at maximum effort, puts it in the pack with the other open "flash" models rather than ahead of them:
| Benchmark | Inkling 2 Small | GLM-5.3-Flash | DeepSeek V4.1 Flash |
|---|---|---|---|
| Artificial Analysis Index v5 | 30.6 | 27.8 | 32.6 |
| DeepSWE v1.1 | 72.1% | 63.4% | 77.0% |
| BrowseComp | 90.2% | 76.0% | 87.8% |
| MMMU Pro (vision) | 81.6% | 79.0% | 80.6% |
| AA-Omniscience non-hallucination | 73.3% | not shown | 35.9% |
The standout is the low hallucination rate. One number the card shows without comment is FORTRESS on benign prompts, where Inkling 2 Small scores 79.7% against 84–97% for every other model in the table, which suggests it refuses harmless requests more often than its peers. Independently, Artificial Analysis scored it 31 on its Intelligence Index, 18 points above Inkling Small, while noting it used about four times as many output tokens as typical, roughly 150,000 per task.
The research: trained in 4-bit from the start #
The technical story is in a companion post, End-to-End 4-Bit Training (Jack Cook and Thinking Machines Lab, 13 November). The expert layers ran their forward passes in NVFP4, NVIDIA's 4-bit floating-point format, throughout pre-training, mid-training and reinforcement learning, with the backward pass in 8-bit and stochastic rounding. The team kept the last 16.6% of layers in higher precision, which matches the shipped weights: experts in layers 0 to 39 are NVFP4 and layers 40 to 47 are 8-bit. The post reports about a 2% cost in compute efficiency against an 8% speed-up in pre-training and 20% in reinforcement learning, and calls it "the largest model we are aware of that was trained end-to-end with a native 4-bit forward pass." It builds on the team's earlier quantization work, Four Over Six (Cook, Guo et al., 2025), on more accurate NVFP4 block scaling.
For a local runner this has two consequences. First, the official checkpoint is already a 4-bit file, about 394GB, and the card says that "this is the native precision for the model", with the 623GB 8-bit release offering only a "very marginal 1–2 percentage points gain". You are not losing quality to a post-hoc conversion the way you are with most 4-bit downloads. Second, the attention, vision encoder and output layers stay in 16-bit in that release, so they make up a large share of what is read per token. One owner who measured it in the model's discussions found that "one decoded token reads 19.3 GB of it, and half of that is BF16 attention weight." Community GGUF and MLX builds that also compress the attention layers read less. The attention design keeps long context affordable. Only the 8 global layers keep a cache that grows with context; by our arithmetic from the config (8 layers × 8 KV heads × 128 dimensions × keys and values × 2 bytes), that is 32KB per token at 16-bit, or about 32GB at the full 1M context and about 4GB at 128K. The 40 windowed layers hold a fixed cache of roughly 160MB. See the KV cache explainer for why that matters.
Runtime support #
- llama.cpp: text and vision support merged on 14 November (pull request 32217 ). The draft-head speed-up is a separate pull request that is still open.
- MLX: support is anopen draft in mlx-lm ; the oMLX server already runs it.
- vLLM: works on Blackwell GPUs; support for Hopper cards such as the H100 and H200 is still pending, and owners report the error "Minimum capability: 100. Current capability: 90".
- Ollama: only a cloud tag so far, no local download.
The files #
| File | Size | Fits |
|---|---|---|
| Official MXFP8 | 623GB | 8× H200 or 4× B300 |
| Official NVFP4 (native) | 394GB | 2× B300, 4× H200, or 512GB of Mac memory via MLX |
| Unsloth UD-Q4_K_XL | 354GB | 512GB Mac |
| bartowski Q4_K_M | 369GB | 512GB Mac |
| Unsloth UD-Q2_K_XL | 205GB | 256GB Mac |
| Unsloth UD-IQ1_S | 172GB | 256GB Mac or 2× 128GB boxes |
Sizes are from Unsloth and bartowski. Unsloth published how far each quant drifts from the original: the 4-bit dynamic quant agrees with the full model's top token 98.0% of the time, the 2-bit 92.7%, and the 1-bit 89.7%. Its guide adds a reminder that file size is not total memory, and suggests starting with a 32K context.
What runs it, and how fast #
Every number below is an owner's own measurement; none has been independently reproduced:
| Machine | Build and runtime | Prompt | Generation |
|---|---|---|---|
| Mac Studio M3 Ultra, 512GB | Official NVFP4, mlx-lm draft PR, 4K context | 478 tok/s | 21.2 tok/s |
| Mac Studio M5 Ultra, 256GB | 3.07 bits per weight, oMLX | not given | 40.5 tok/s, 74.8 with the draft head |
| One DGX Spark (128GB) | 110GiB vector-quantized build, custom runtime | 1,248 tok/s | 29.8 tok/s |
| 3× RTX Pro 6000 Max-Q | EXL3 3.17 bits, 1M context | about 5,400 tok/s | about 105 tok/s |
| One RTX 5090, experts in system RAM | Streamed from host memory | 14.5 s to first token | 1.5 tok/s |
Sources: the mlx-lm pull request, Hygaard's M5 Ultra build, Baekpica's DGX Spark build (a custom format that llama.cpp and Ollama cannot read), mel-bw's EXL3 build and the model's discussion 8.
The pattern is clear. A 512GB Mac Studio runs the native 4-bit weights at about 21 tok/s, and the newer M5 Ultra roughly doubles that on a 3-bit build and nearly doubles it again with the draft head. Multi-GPU workstations are much faster. A single consumer GPU streaming experts from system RAM is not practical. No owner has yet published a speed for a 128GB Strix Halo box; it only fits the heavily pruned 98GB build, which drops 77 of the 384 experts per layer. See what to pre-download for a 256GB or 512GB Mac Studio and M5 Max vs M5 Ultra.
The API alternative is cheap: Thinking Machines charges $0.30 per million input tokens and $1.00 per million output on Tinker, according to its pricing page. At those prices, local hardware pays off only if you need the weights on your own machine. Run the comparison in the cost calculator.
What owners say #
The Hacker News thread (298 points) was mostly about the name. "This isn't small at all, for most budgets outside of enterprise," wrote one commenter. Another noted that "it doesn't beat DS v4.1, and they have so much more compute capacity than any Chinese company." On cost, one suggested that "you could probably run a Q2-Q3 with 2x DGX Sparks. So...$12k at today's prices." The most optimistic: "If Thinkingmachine's self reported benchmark is true, I'm certain it's going to get into heavy rotation." Owners on Hopper GPUs are still waiting for vLLM support.
One licence note. The weights are Apache 2.0, but Thinking Machines also publishes an acceptable-use policy that it says applies to the model and modified versions. Beyond the usual weapons and abuse categories, it bars automated decisions about people's credit, employment or housing, and unlicensed medical, legal or financial advice, and requires telling users they are talking to an AI. Read it before building a product on the model.
Verdict: worth down? #
If you own a 512GB Mac Studio, yes. Inkling 2 Small is the most practical frontier-class open model for that machine right now: the official 4-bit weights fit with room for long context, they are the model's native precision rather than a lossy conversion, and owners measure about 21 tok/s on an M3 Ultra. A 256GB M5 Ultra runs a 3-bit build faster still. Its low hallucination rate suits research and agent work; expect long, wordy answers and the occasional unnecessary refusal. With 128GB or less, it is not for you yet, and GLM-5.3-Flash or Qwen3.8-Flash-Next remain the better local picks. For everyone else, the $1-per-million-token API is hard to beat.
Sources and how we researched this #
Creator documents: the Inkling 2 Small model card, launch post, End-to-End 4-Bit Training and acceptable-use policy. Research: Cook, Guo et al., Four Over Six: More Accurate NVFP4 Quantization with Adaptive Block Scaling (2025). Independent scoring: Artificial Analysis. Files and measurements: the Unsloth, bartowski, Hygaard, Baekpica and mel-bw repositories linked above, the mlx-lm and llama.cpp pull requests, and the model's Hugging Face discussions. Community: the Hacker News thread. The KV-cache sizes are our arithmetic from the published config. We have not run the model; the site is non-commercial.
Related: What hardware runs the original Inkling · MoE explained · MLX vs llama.cpp on a Mac