Source:
The Register SPONSORED POST: The Context Memory Storage platform aims to improve the economics of large-scale AI inference
As organizations move from straightforward AI interactions towards longer conversations, complex
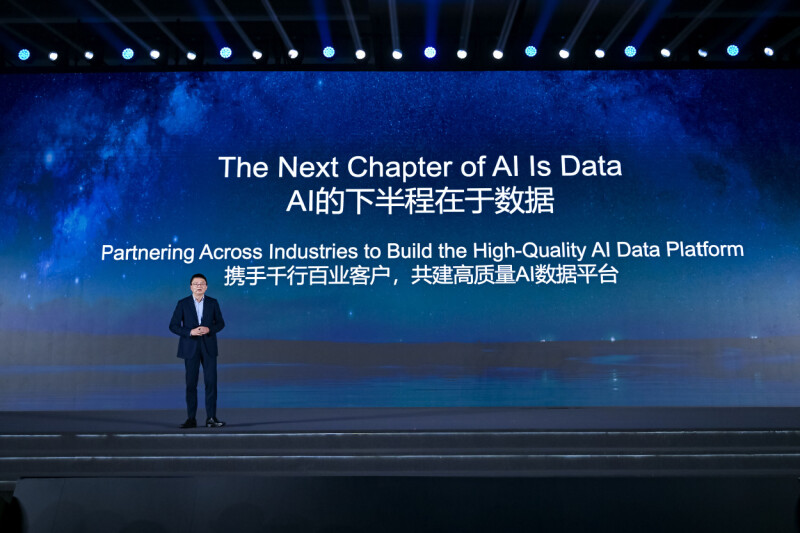
reasoningand autonomous agents, the demands on their infrastructure are changing. Processing increasingly large amounts of context places significant pressure on memory capacity, while keeping accelerators supplied with data becomes just as important as raw computing power. One particular challenge is the key-value (KV) cache, which stores information generated duringinferenceso models can reuse previous computations rather than repeatedly processing the same context. As context windows expand and multi-turn interactions become more demanding, these caches grow considerably. GPU memory and system memory provide fast access but are expensive and capacity constrained. Traditional storage offers greater capacity, yet its longer, CPU-mediated data paths can introduce latency that leaves valuable accelerator resources waiting for data. Huawei believes addressing this gap requires a different approach to storage. Bringing context memory closer tocomputeAt HUAWEI CONNECT 2026 in Shanghai, Huawei introduced OceanStor M900 Context Memory Storage, designed to support AI inference across hyperscale datacenters and its Ascend SuperPoD infrastructure. The platform introduces what Huawei describes as a dedicated Context Memory Storage layer, extending KV cache beyond accelerator and system memory into a shared, multi-tier storage pool. Using Huawei's UnifiedBus high-speed interconnect, OceanStor M900 enables KV cache resources to be shared across a cluster, with Huawei claiming capacity of up to 64PB and substantially more context available per NPU. Its innovative ASU disk also integrates CPU, networking and storage controller functions. Combined with native KV semantics, this allows NPUs to access stored cache data in a single hop, avoiding conventional protocol conversion and CPU forwarding. According to Huawei, this approach reduces access latency to 60 microseconds, potentially doublingtokenthroughput and halving time to first token in typical AI coding workloads. Cost and durability are also part of the proposition. Huawei's KV-aware adaptive storage technology manages data placement according to cache lifecycles, with claimed endurance of up to 24 drive writes per day, or 16 times that of conventional SSDs. The company argues this could reduce replacement and maintenance costs over time. The wider significance of OceanStor M900 lies in Huawei's approach to AI infrastructure. Rather than treating storage as a separate supporting component, the company is positioning memory, networking and compute as increasingly interconnected elements of inference performance. Asagentic AIworkloads grow, how efficiently infrastructure retains, shares and retrieves context may become as important as how quickly its accelerators can process it. Sponsored by Huawei Get AI news in your inbox
Daily digest of what matters in AI.