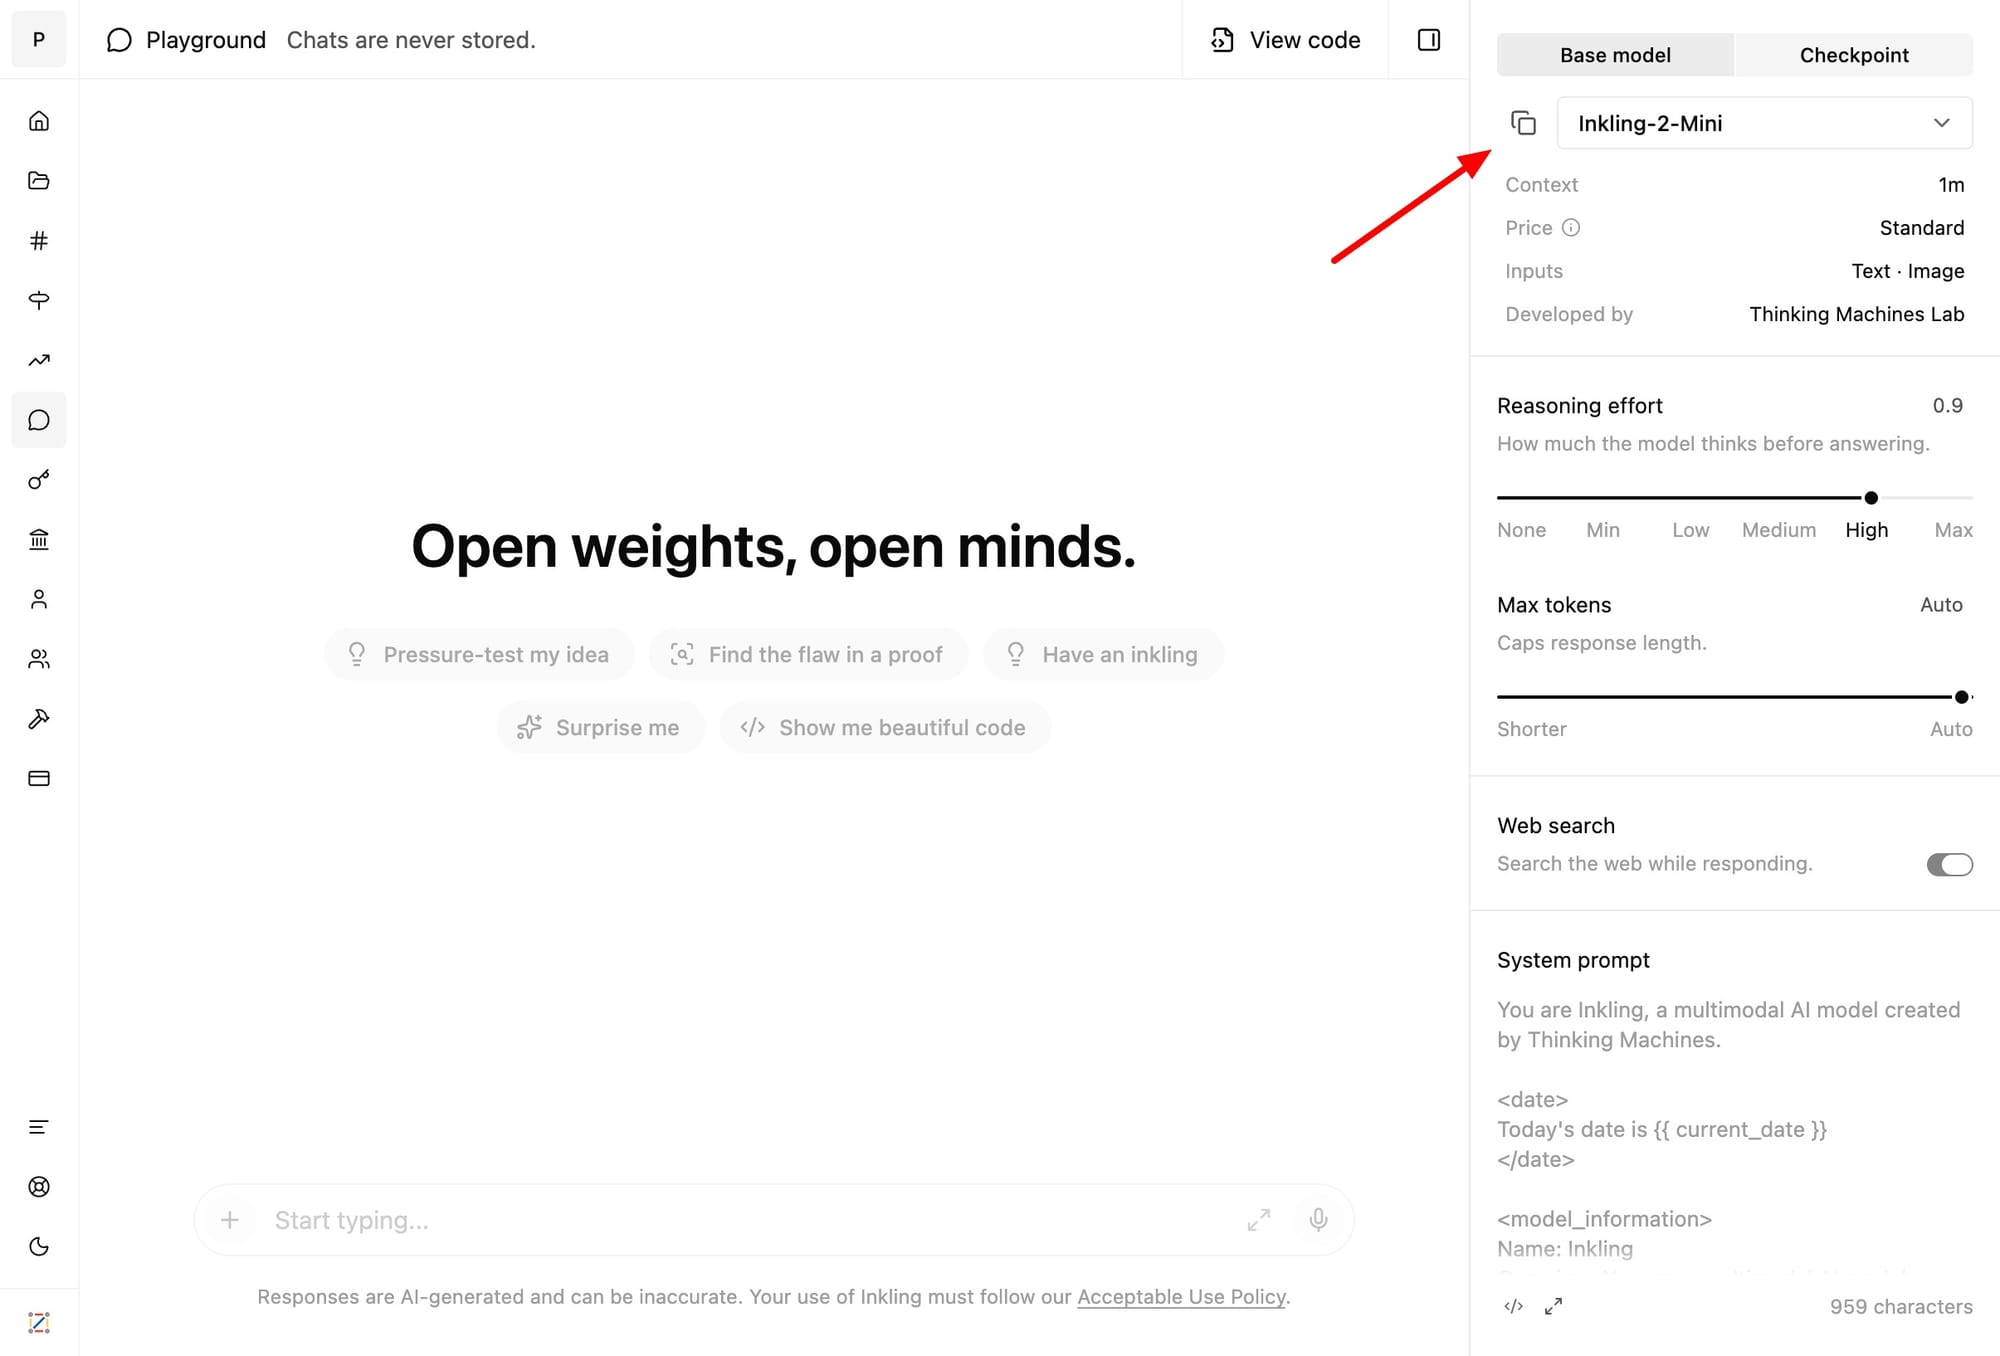
Thinking Machines Lab has released Inkling 2 Mini, an open-weights model built to be fast, capable at agentic work, and small enough to run on a laptop. The weights for Inkling 2 Mini and a research-specific variable-loop variant are on Hugging Face, and the model is live on Tinker for inference and fine-tuning, with chat in the Tinker Playground.
Open-source inference is supported from day one on SGLang, vLLM, Ollama, Unsloth, NVIDIA Dynamo and TokenSpeed, with RL fine-tuning on SkyRL, Miles and NVIDIA AutoModel.
Inkling 2 Mini is a looped transformer. Of its 24 layers, the middle 12 run three times per token, while the first and last six run once, letting the model apply more reasoning and reach the right answer with fewer tokens. It is a Mixture-of-Experts model with 26.4B total parameters, 3.4B active and 5.4B weight activations per token once looping is counted. Most weights were trained and are deployed natively in NVFP4, with the last four layers in MXFP8, so there is no quantization loss and the full footprint sits around 20GB. On a flight, the team ran it offline on a MacBook Pro and built a playable flight simulator in a few minutes.
According to Thinking Machines, Inkling 2 Mini leads every open-weights model under 100B total parameters on DeepSWE v1.1 with 48.2% and Vals Index v2.2 with 46.5%, and ties Qwen3.8-27B at 20.1 on the Artificial Analysis Index. It also tops its size class on BrowseComp, DeepSearchQA, and MCP Atlas, using search and tools to make up for the limited knowledge a small model can store. The company is upfront about the gaps: it trails Qwen3.8-27B on multi-turn chat and on instructions with many constraints.
Looping lets a model reason longer without writing its reasoning down, which raises questions about monitoring a model through its chain of thought. Thinking Machines studied this with the variable-loop model. Its no-CoT time horizon grew from 16 seconds at one pass to 37 seconds at three, the chain of thought got shorter but stayed legible, and scores on agentic sabotage tests did not trend higher as loops were added.
Thinking Machines Lab, led by Mira Murati, follows Inkling 2 Small, a 594B parameter model that some users found too big to run themselves. Mini is the answer to that feedback and one of the first looped models open to researchers. The lab is working with the National Deep Inference Fabric to bring it to interpretability researchers, and gave Goodfire early access to study how looped models work inside.
I think this release lands in a spot many local model fans were watching. We expected Qwen to drop a new SOTA model for local work, but we got Inkling instead, and it is going straight into my local testing.
Sources and related context #
- Artificial Analysis on X: Inkling 2 Mini on the Intelligence Index : Supports: Artificial Analysis independently places Inkling 2 Mini at 20 on its Intelligence Index and lists its Apache 2.0 license and 1M token context window.
- Thinking Machines on X: Inkling 2 Mini announcement : Supports: The lab's launch post frames Mini as its reply to users who found the 594B parameter Inkling 2 Small too big.
- Thinking Machines launched open-weight Inkling-Small : Related context: Earlier coverage of the first Inkling-Small open-weights release that preceded the Inkling 2 family.