cd /news/large-language-models/show-hn-sunk-cost-how-long-until-a-l… · home topics large-language-models article
[ARTICLE · art-129723] src=sunkcost.ai ↗ pub= topic=large-language-models verified=true sentiment=· neutral

Show HN: Sunk Cost – How long until a local LLM rig pays for itself?

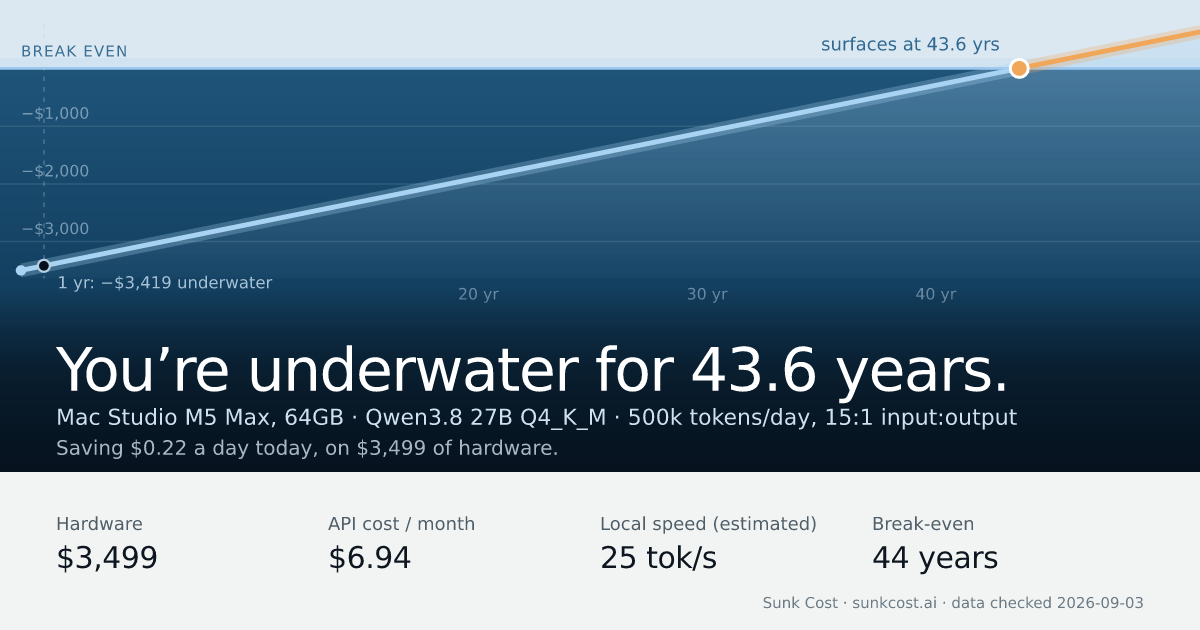
A Show HN project called Sunk Cost calculates how long it takes for a local large language model rig to pay for itself versus using API access. The tool estimates local inference speed as memory bandwidth divided by bytes read per token when no measured figure is available, and labels those estimates as such, while API speed only affects the time comparison. The project exposes its assumptions as user-editable inputs.

read1 min views1 publishedSep 15, 2026
Show HN: Sunk Cost – How long until a local LLM rig pays for itself?
Image: source

The break-even #

How you’d use it #

Assumptions you can change #

Where nothing has been measured, local speed is estimated as memory bandwidth ÷ bytes read per token × , and labelled as such. API speed only affects the time comparison.

I’m looking at a , the with of memory.

── more in #large-language-models 4 stories · sorted by recency
── more on @show hn 3 stories trending now
sponsored brought to you by zahid.host 4,200+ EU-deployed projects
reading about agents? ship yours in a single git push.

Run your AI side-project on zahid.host

EU-based hosting, git-push deploys, automatic HTTPS, no cold starts. Free tier with a custom domain — perfect for shipping the agent you just read about.

$git push zahid main
Live at https://your-agent.zahid.host
Get free account → Pricing
from €0/mo · no card required
LIVE [news/show-hn-sunk-cost-ho…] indexed:0 read:1min 2026-09-15 ·