A game company is now an open-weights lab. KRAFTON (PUBG: Battlegrounds, Dark and Lonely) shipped its first open LLM on Tuesday and the design choices read like they came from someone who plays their own games: a 30B MoE with 4B active that runs on one RTX 5090, with the thinking channel and the speculative-decoding draft model both in the box.
What Raon-1 mini is #
Raon-1 mini TLDR: an open source 30B MoE (4B active) from Krafton with built-in reasoning and a shipped DFlash2 draft model. It enables 30B-class quality on a single 32 GB GPU via NVFP4, or on Apple silicon via MLX. The difference between Raon-1 mini and regular LLMs is that the thinking channel and the draft model ship with the release, so the speed tricks are supported out of the box rather than bolted on.
The benchmarks, read honestly #
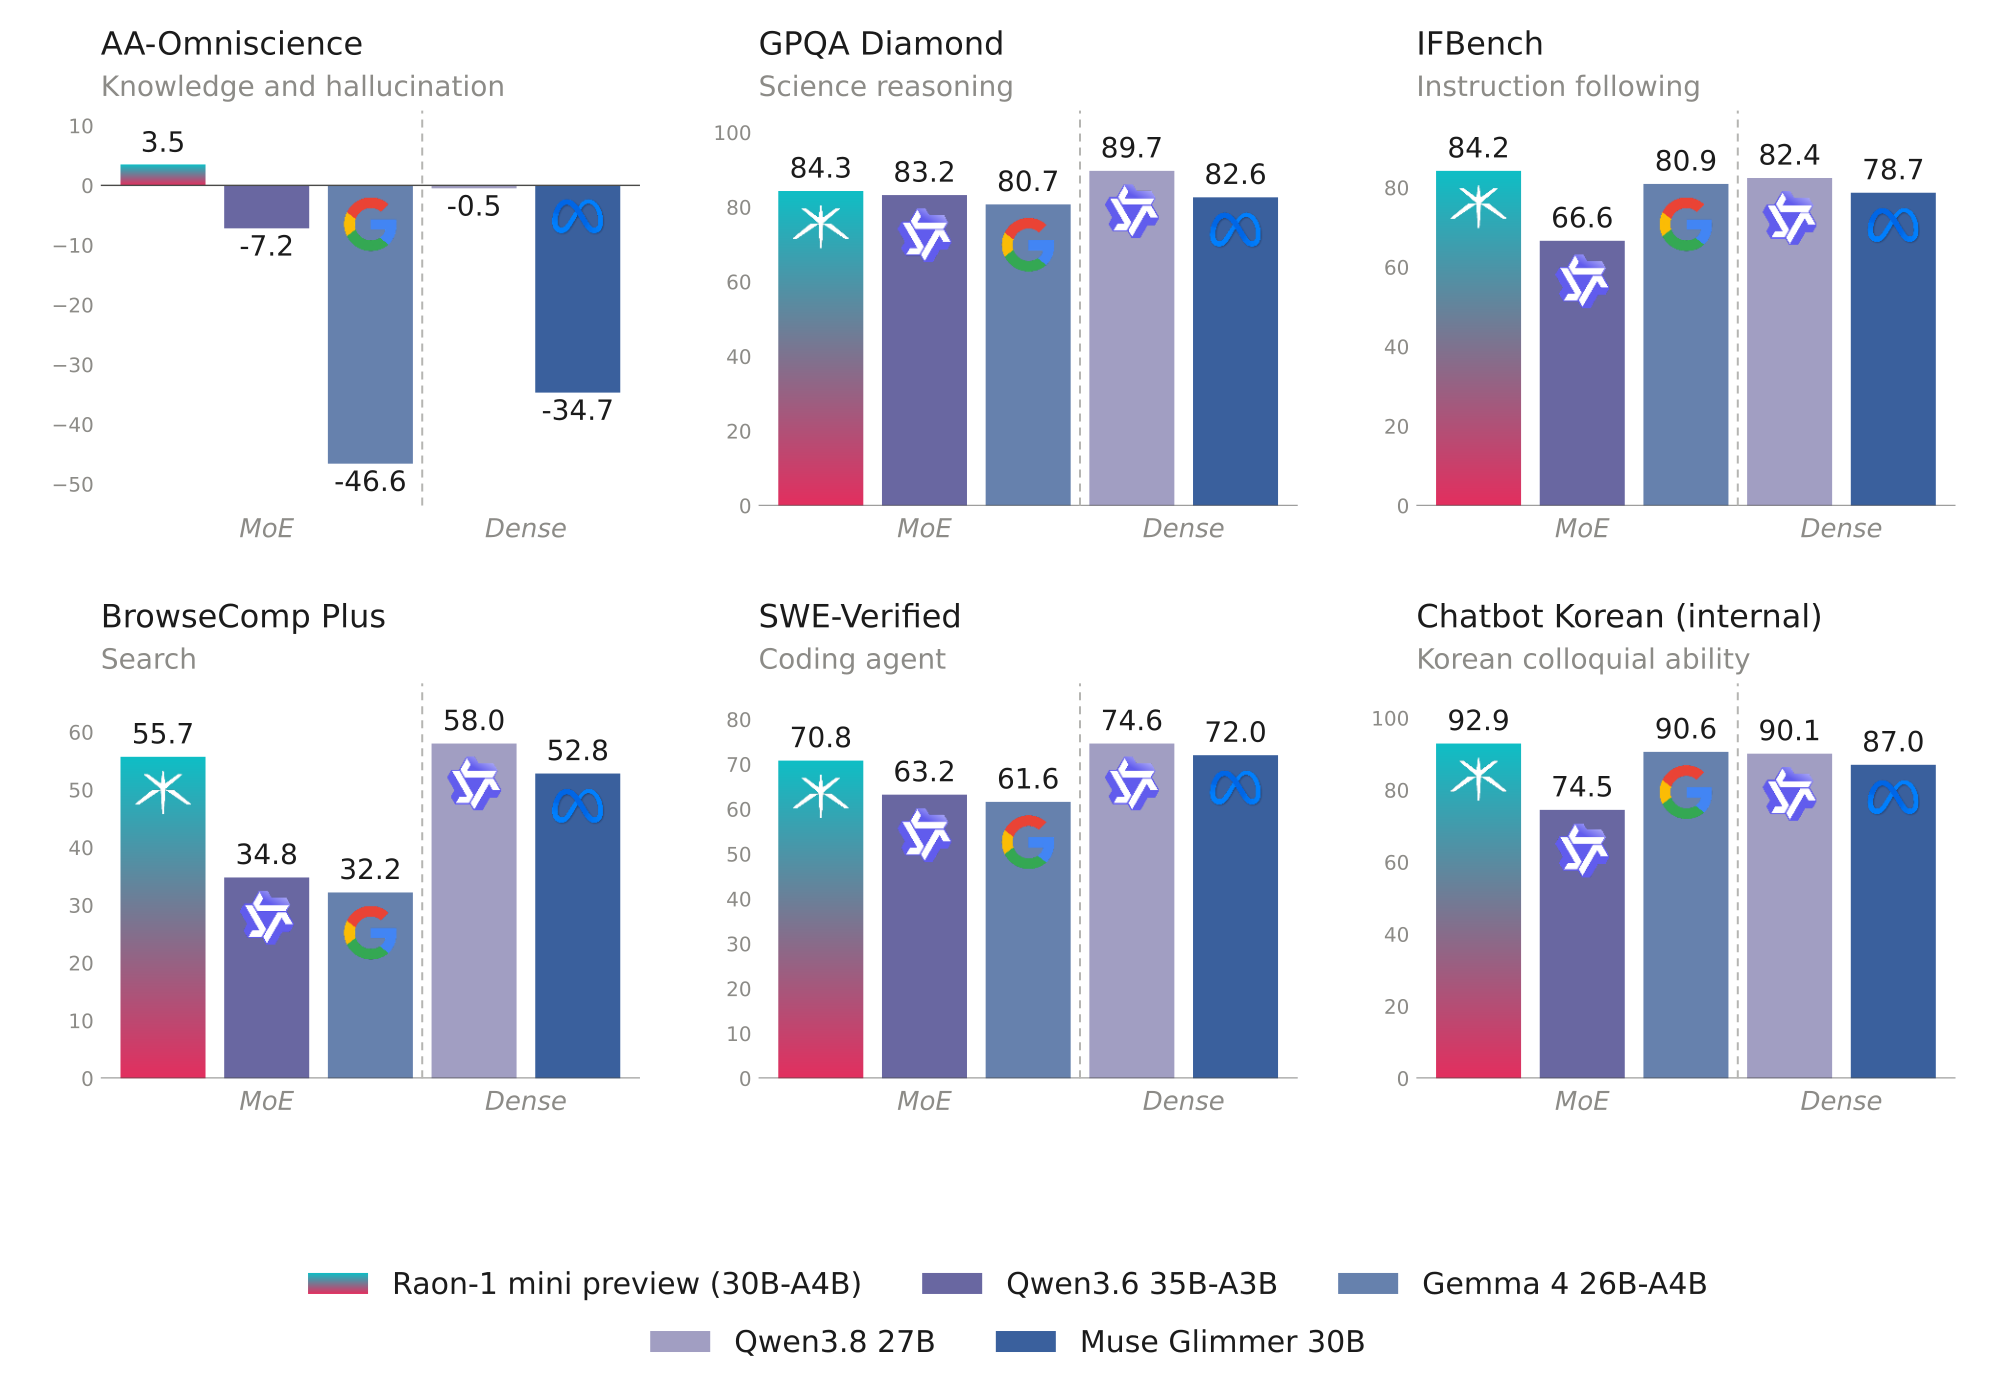
Krafton’s panel puts Raon-1 mini against the current local peer set: Qwen3.6 35B-A3B, Qwen3.8 27B, Gemma 4 26B-A4B, Muse Glimmer 30B. Raon leads five of the six boards against the MoE peers:
- AA-Omniscience (knowledge and hallucination control): Raon 55.7 positive; Qwen3.6 35B 34.8; Gemma 4 26B 32.2; two dense models score NEGATIVE (-7.2, -46.6), which is the panel’s most honest panel of the week.
- GPQA Diamond: 84.3, level with Qwen3.8 27B’s 89.7 above it (that one goes to Qwen)
- IFBench (instruction following): 84.2 vs 80.9 for Qwen3.8
- BrowseComp Plus (search): 55.7 vs 34.8/32.2 for the MoE peers
- SWE-Verified (coding agent): 70.8, mid-pack here; Qwen3.8 82.6 leads
- Chatbot Korean (internal eval): 92.9, and the gap to every peer is the largest on the panel
The pattern is coherent with the pitch: Korean-native instruction following and agentic search are the differentiators; coding is present but not the headline.
The fit math #
At 4B active, decode speed should feel immediate, and the shipped DFlash2 draft model exists to make it more so: speculative decoding pairs a big verifier with a small drafter, and Krafton shipping BOTH halves in the release removes the glue work that usually kills day-one speed runs.
NVFP4 on one RTX 5090 (32 GB): 30B total at 4-bit is about 15 GB; the rest of the 32 GB covers KV and the drafter. Comfortable. #
MLX on Apple silicon: the official MLX build targets 32-to-48 GB machines the same way. #
GGUF for llama.cpp: live, with the caveat that Krafton ships their own llama.cpp branch until the support merges upstream. The GGUF repo shows 7,661 downloads already. #
Context: 256K, gated-but-auto-approved on HuggingFace (you click, you get weight access).
Why a game company building this matters #
Krafton trains models for a reason: their games need believable AI teammates and their pitch is that Raon-1 is the internal capability spun out. The preview flag on the name says the family continues. If the Raon-1 line keeps open weights the way this first release did, Korean-first open models get a proper home, and the “open weights at every size” ladder (Jais 3’s ladder, Nemotron’s ladder) gains one more rung from an unexpected region.
Sources: the KRAFTON model repo on HuggingFace (Apache-2.0), Krafton’s announcement page at raon-mini.krafton.ai, the benchmark panel from the release assets.
Related on this site: the engine catalog covers runtimes for the GGUF and MLX builds; Bolt 74B on one card covers the same one-GPU class from NVIDIA’s side.