Qwen3.8-Flash-Next for a single DGX Spark got a serious upgrade with TensorFold🔥 This is a completely new recipe, optimized and tuned for TesnorFold! Expect further improvements!
- KV cache pool is ~1.3M
- Default context 256k, with 5 concurrent.
- Faster everything compared
Last updated Sep 29, 2026
TensorFold's new inference engine delivers decode speeds over 62 tokens per second on a single stream and 119 across five, with prefill at 2,500 tokens per second and a 256k context window. It outperforms prior vLLM setups in time-to-first-token and multi-user tests, while supporting vision and video inputs on DGX Spark's unified memory. Community builders praise its accessibility, running strong performance on consumer hardware like RTX 3090 with 64GB RAM, and look forward to tweaks for models like GLM 5.3 Flash.
This story is a summary of posts on X and may evolve over time. Grok can make mistakes, verify its outputs.
Related Trending Stories on X #
You can now run an LLM which scores higher than Sonnet-5 medium, and GPT-6-Sol medium for 3000$ in compute
- 65 decode tok/s
- 2000 prefill tok/s
- 200k kv cache
- RTX 3090 / 4090 / 5090 / Intel Arc B70 / AMD
- 64 GB of RAM
- 100 GB of NVMe Recipe today
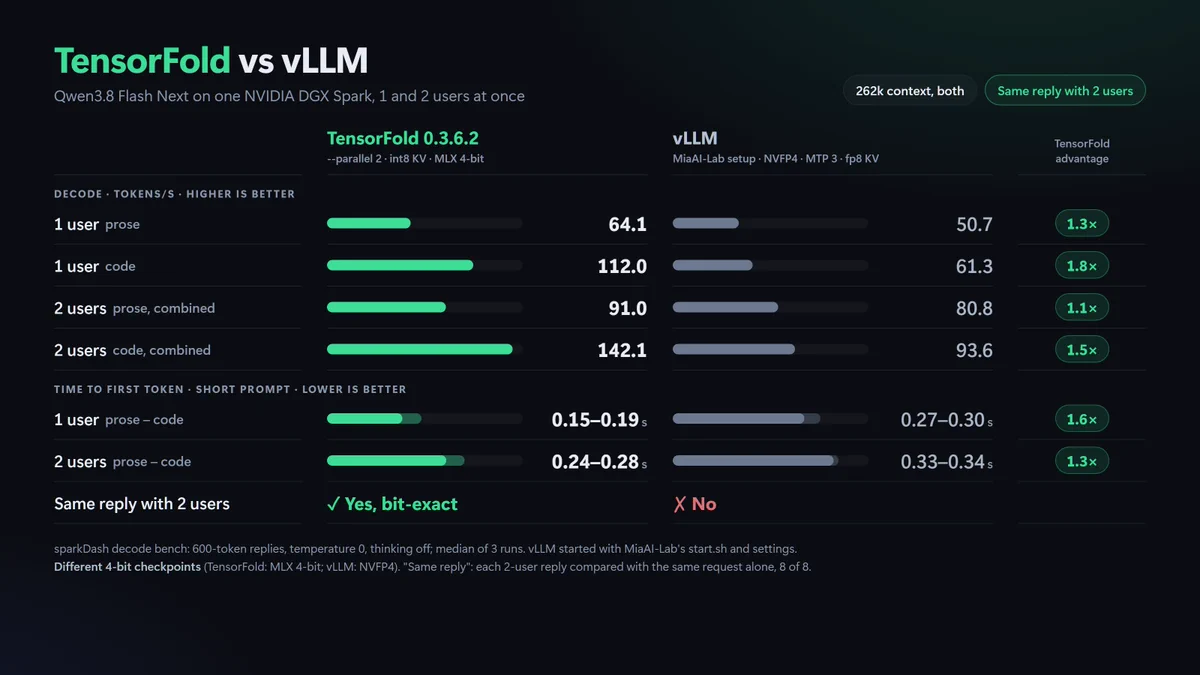
Edit: In the previous post I was running old vllm version. I ran the tests again with the following setup: 𝐐𝐰𝐞𝐧𝟑.𝟖 𝐅𝐥𝐚𝐬𝐡 𝐍𝐞𝐱𝐭, 𝐨𝐧𝐞 𝐃𝐆𝐗 𝐒𝐩𝐚𝐫𝐤, 𝟐𝟔𝟐𝐤 𝐜𝐨𝐧𝐭𝐞𝐱𝐭: 𝐓𝐞𝐧𝐬𝐨𝐫𝐅𝐨𝐥𝐝 𝟎.𝟑.𝟔.𝟐 𝐯𝐬 𝐯𝐋𝐋𝐌 (𝐌𝐢𝐚𝐀𝐈-𝐋𝐚𝐛 𝐬𝐞𝐭𝐮𝐩).
what an insane performance leap and great accomplishment. Congratulations to Mia and
@ashxhartcan’t wait to see the next recipes Qwen3.8-Flash-Next for a single DGX Spark got a serious upgrade with TensorFold🔥 This is a completely new recipe, optimized and tuned for TesnorFold! Expect further improvements!
- KV cache pool is ~1.3M
- Default context 256k, with 5 concurrent.
- Faster everything compared