ARTICLE
Discover how Jev outperforms GPT Luna 6 by being 13.6x faster and 2.7x cheaper for Tessl verifiers. Try Jev in the CLI now and boost efficiency!
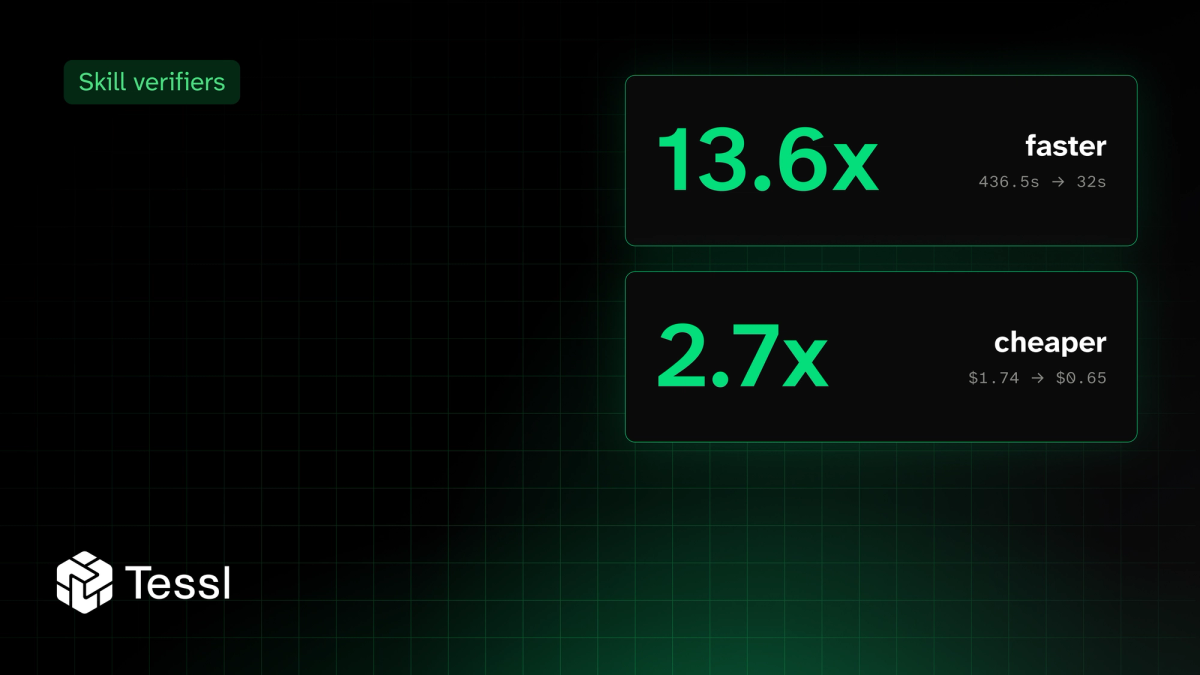
Jev is 13.6x faster and 2.7x cheaper than GPT Luna 6 for Tessl verifiers. Try it yourself. #
This evaluation was run against Tessl’s internal production code. We have shared the methodology, model details, and commands so you can run the same comparison on your own repository.
We ran our whole verifier test suite (think linting, but with reasoning, read the blog for details) through Jev, TypeSafe's new decision model, and compared it against the current LLM we have been using as a judge, GPT Luna 6. This means six projects, around 2,725 verifier and file pairs, both judged on identical targets, with the gateway cache bypassed so that every LLM call was a genuinely fresh generation.
Here are the key takeaways:
- Jev ran our verifier suite 2.7x cheaper and13.6x faster than our default LLM judge, GPT Luna 6.
- You can try it now. Tessl supports Jev in the CLI, alongside GPT Luna 6 .
Here's some of the data points as a table for you to compare:
| GPT Luna 6 (gpt-6-luna) | Jev (jev-1.13.0) | |
|---|---|---|
| Cost, ~2,725 targets | $1.74 illustrative | $0.65 list |
| Cost per 1,000 targets | $0.64 | $0.24 |
| Wall clock | 436.5 s | 32 s |
It’s worth noting that we also ran the same suite against our previous judge, GPT Luna 5.6, and found Jev 6.6x cheaper and 10x faster there. Luna 6 is both cheaper and slower than its predecessor, so Jev's cost advantage narrows while its speed advantage grows.
If you have not come across Jev, it's a new model built to make decisions. It works as a generalised classifier: give it a question and some context, and it returns a decision with a probability, without generating a chat response. Jev will never say "you're absolutely right", and I have 100% confidence that you're ok with that.
That makes it interesting for a familiar problem in software teams. Your coding agents can produce changes quickly, but they still need to follow the rules of your codebase. Some rules fit into tests or traditional linters. Others require reading the code and making a judgment: does this user-facing error tell someone how to resolve it? Does this change follow the architecture described in our design doc?
We've added Jev as a model for Tessl verifiers, so you can try it on rules in your own repository. The Tessl CLI is free to install, and there's a free tier for getting started.
What did we actually test?
We tested our Tessl verifiers, which are rules you check into your codebase. They say what should be true, when the rule applies, and what the judge should check. Your tessl.json controls which files the verifier runs against. The CLI then makes it easy to efficiently run all the required checks for a diff or across the full codebase, making it easy to run them locally or in CI.
For example, a verifier might say that user-facing errors about missing resources should give the user a concrete next step. It might be configured to only run on TypeScript files in the front end codebase. Tessl can work out if any files are relevant in your diff, or let you run a sweep across main. The rule lives alongside the code it governs, where your team and your agents can inspect and improve it.
That gives you a practical loop: agents generate code, verifiers check it, and review feedback helps you improve the rules.
Let's take a look at what a simple verifier looks like:
1{
2  "name": "no-token-in-git-url",
3  "instruction": "Git remote URLs must not embed credentials.",
4  "relevant_when": "The file constructs or writes a git remote URL.",
5  "checks": [
6    "No git URL in this file contains a token, password or PAT.",
7    "Credentials, where needed, come from the environment or a credential helper."
8  ],
9  "level": "error"
10}
In our codebase, Jev and GPT Luna 6 agreed on 85.9% of verifier decisions. The differences were concentrated in rules about comment structure and content, where Jev tended to be more lenient: on warn-level prose rules Luna 6 failed 50.1% of files against Jev's 30.4%, while on warn-level code rules the two sat much closer at 15.3% and 10.3%. We also saw some unexpected disagreements, including on error-handling rules, and we're still looking into them.
We recommend tuning a verifier against the judge you plan to use, following the method in the tessl-verify skill. Try both models on examples you know and inspect where they differ. You can output the full responses for every judgement: GPT Luna 6's results include written reasoning, Jev's include decision probabilities. Those give you different ways to investigate a result and improve the rule.
You can reproduce what we've done in minutes. The comparison is more useful on your rules than on ours, so don't just take our data.
Start by writing some verifiers for things your team already enforces by review comment, since those are the rules you already know the answers to. The verifier docs have the full schema and a worked example. Run tessl change verify --all for a baseline, run it again with --model jev, and then diff the two reports. The number worth your attention is not the agreement rate but the specific files where they part company.
Try it for yourself #
Install the Tessl CLI and initialise it in your repository. If you already have verifiers, run them on your current changes with Jev:
1tessl change verify --model jev
To see which files a full run would inspect before making judge calls:
1tessl change verify --model jev --dry-run --all --show-files
Then try a sample:
1tessl change verify --model jev --all --sample 20
If you're starting from scratch, ask your coding agent to use the tessl-verify skill to find a few concrete rules in your review comments, repository guidance, or design docs. Have it set up the verifier files and their scopes in tessl.json, then inspect the dry run and sample results together. The Tessl docs also walk through verifiers and running them in CI.
We want these building blocks to be visible and editable in your repository. Your agents can help create the rules, Jev can help check them, and your team can keep improving both through loops so they get more and more useful over time. Join our discord and share your results with the community!
COPY & SHARE
Simon Maple
Simon Maple is the Head of Developer Relations at Tessl, and AI Native Dev co-host. Previously, Simon was the Field CTO, and VP Developer Relations at Snyk, ZeroTurnaround, and IBM. He became a Java Champion in 2014, JavaOne Rockstar speaker in 2014 and 2017, Duke’s Choice award winner, Virtual JUG founder and organiser, and London Java Community co-leader.
Amy Heineike
Amy is Founding AI Engineer at Tessl. She was previously the VP of Engineering at 7bridges and Primer.ai as well as Director of Mathematics and Machine Learning at Quid.
READING
·
0%
IN THIS POST
COPY & SHARE
Simon Maple
Simon Maple is the Head of Developer Relations at Tessl, and AI Native Dev co-host. Previously, Simon was the Field CTO, and VP Developer Relations at Snyk, ZeroTurnaround, and IBM. He became a Java Champion in 2014, JavaOne Rockstar speaker in 2014 and 2017, Duke’s Choice award winner, Virtual JUG founder and organiser, and London Java Community co-leader.
Amy Heineike
Amy is Founding AI Engineer at Tessl. She was previously the VP of Engineering at 7bridges and Primer.ai as well as Director of Mathematics and Machine Learning at Quid.
YOUR NEXT READ
Who Owns your/the Context? #
Explore the complexities of context ownership in agentic transformations, focusing on workflows, processes, and the critical role of explicit ownership models.
Rob Hudson, Simon Maple