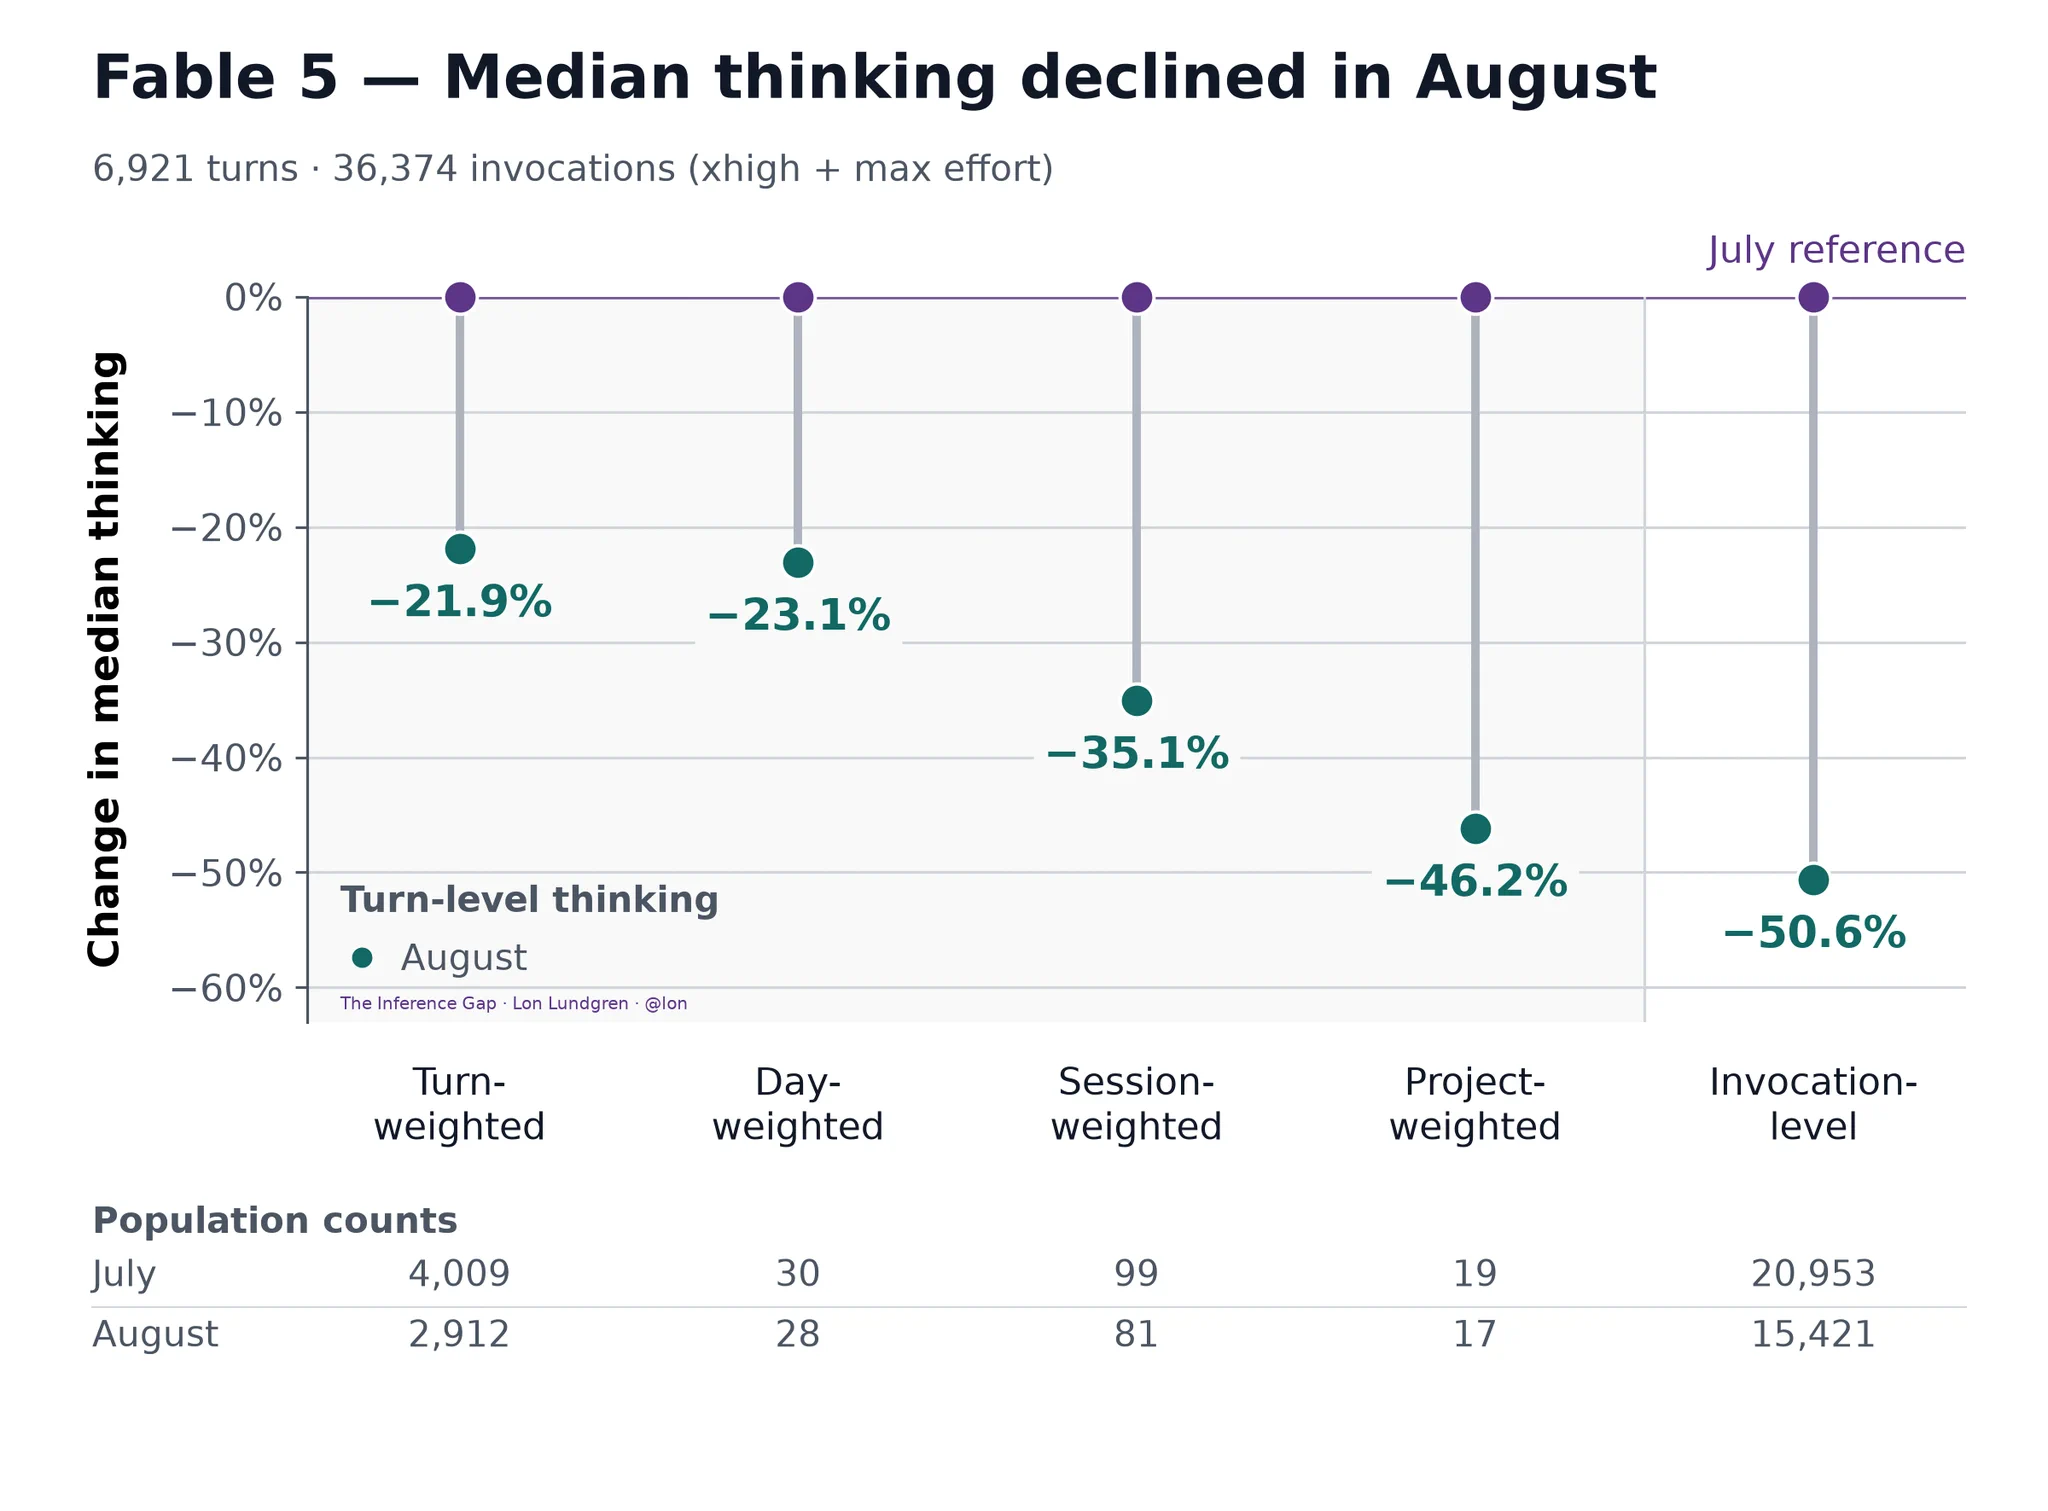
Lon Lundgren on X: "After Anthropic made Fable 5 permanently available in subscription plans, I noticed a large drop in performance. The model felt dumber, and I couldn't explain why. Measured five different ways, August delivered dramatically fewer thinking tokens than July." / X
Lon Lundgren on X: "After Anthropic made Fable 5 permanently available in subscription plans, I noticed a large drop in performance. The model felt dumber, and I couldn't explain why. Measured five different ways, August delivered dramatically fewer thinking tokens than July."
After Anthropic made Fable 5 permanently available in subscription plans, I noticed a large drop in performance. The model felt dumber, and I couldn't explain why. Measured five different ways, August delivered dramatically fewer thinking tokens than July.
After Anthropic made Fable 5 permanently available in subscription plans, I noticed a large drop in performance. The model felt dumber, and I couldn't explain why. Measured five different ways, August delivered dramatically fewer thinking tokens than July.
This wasn't a one-time drop. Reasoning fell over the entire period, and fluctuated across multi-day episodes. Some of these fluctuations aligned with specific product announcements and releases. I started to see how the model could feel great one day, and terrible the next.
I was consistently using an xhigh or max effot level, but when I looked deeper, I found that most invocations to the model were receiving little to no thinking tokens at all. And when longer thinking runs did happen, they almost never reached published benchmark levels.
This unfolded across a six week data capture and analysis odyssey, and led to a number of surprising findings. Next time the model feels dumber, don't ask if the model was "nerfed". Ask about the inference regime you were served, instead.
Buddy its so simple. If one person used fable. It'll blow your socks off. Divided by millions It starts to suck. Models get dumber as usage goes up until they make another datacenter. Then on and on forever