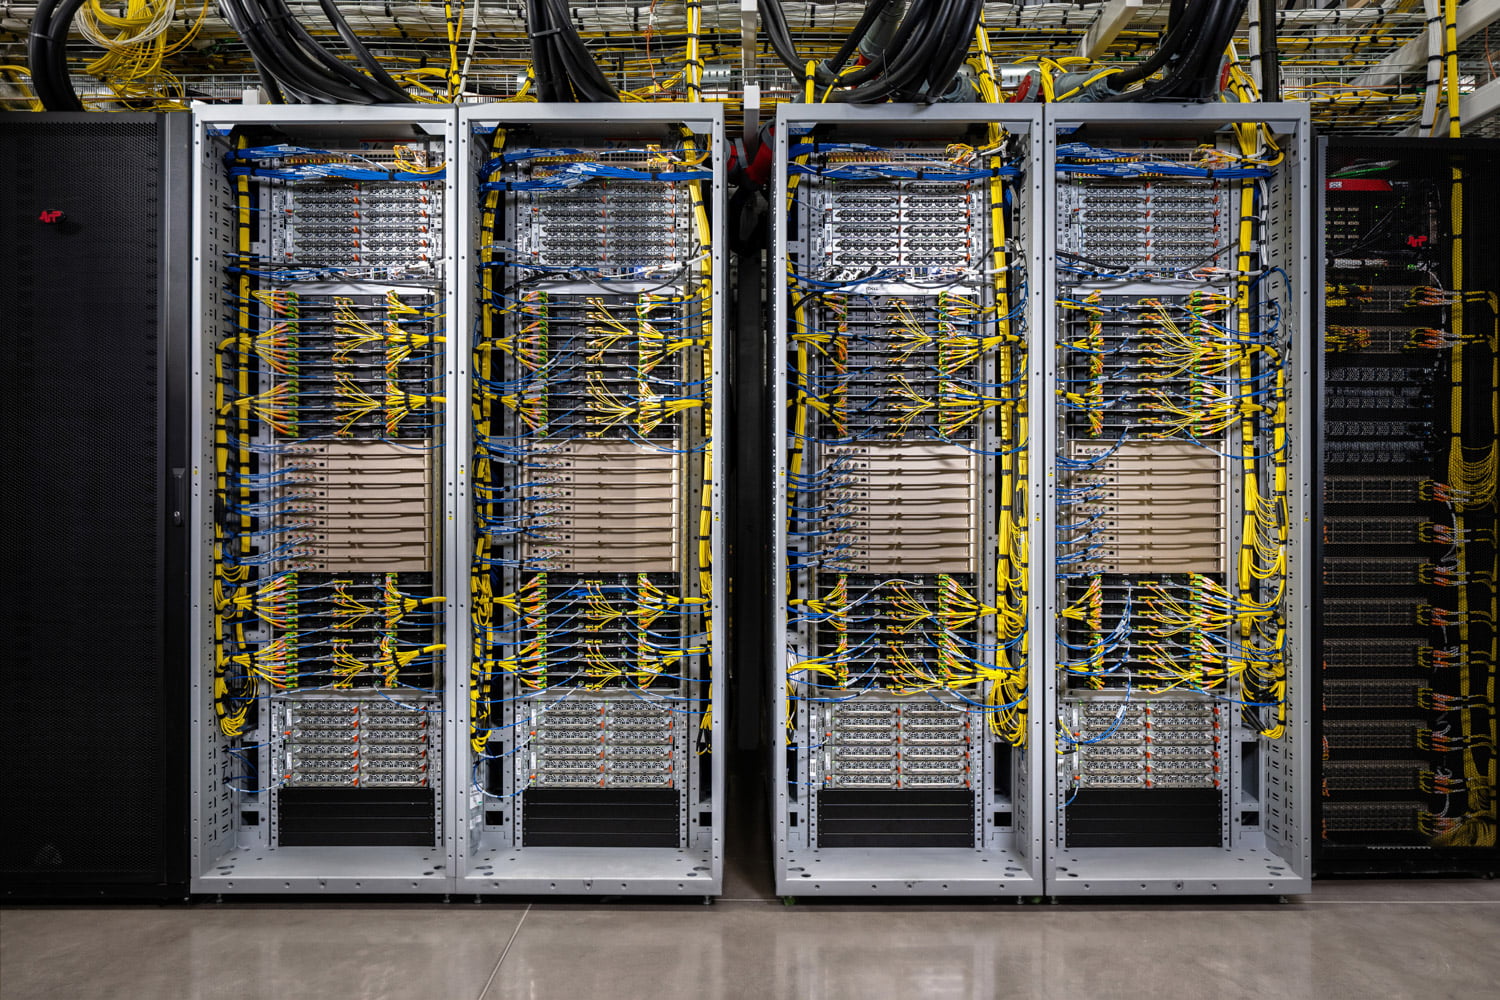
CoreWeave used its Fully Connected 2026 conference in San Francisco to put NVIDIA Vera Rubin NVL72 into production, with Cognition as the first customer running live workloads on it. Cognition’s engineers report up to 4.8x the total token throughput per GPU of a GB200 NVL72 baseline on SWE-2 inference at matched interactivity, and 3.8x the output token throughput per GPU on reinforcement learning. Both are Cognition’s own benchmarks on CoreWeave Cloud, run on production-style agentic workloads, with no model sizes, context lengths, or batch settings disclosed.
Vera Rubin NVL72 Enters CoreWeave Production #
Cognition runs training, reinforcement learning, and production inference for Devin on CoreWeave. CoreWeave says it stood up the Vera Rubin NVL72 cluster in early September and had Cognition’s workloads running within days of rack handover, and it calls Cognition’s run the first customer-executed Vera Rubin inference benchmark. Cognition’s framing is that the SWE-2 result means more concurrent Devin sessions per GPU and faster research turns.
CoreWeave’s press release says Vera Rubin NVL72 is now available; its own blog post on the Cognition deployment calls it limited availability, so expect allocation to be gated for now. Customers run it through the same software and operating model as CoreWeave’s GB200 NVL72 and GB300 NVL72 fleets: CoreWeave Kubernetes Service, SUNK, Mission Control, Sandboxes, and serverless inference.
The racks themselves, the Dell-built NVL72s with two ConnectX-9 SuperNICs per GPU, and the staged validation CoreWeave runs before a rack reaches production are what we covered in the September multi-rack bring-up. What’s new is a paying customer on them.
NVIDIA Vera CPU Targets Agent Sandbox Density #
CoreWeave will also add the NVIDIA Vera CPU to its portfolio as a standalone compute tier for agentic work: sandbox execution, reinforcement learning environments, tool calls, code execution, and the data processing that surrounds GPU training and reasoning jobs. No date was given beyond “coming soon.”
A Vera node on CoreWeave pairs two 88-core Vera CPUs with 1.5TB of RAM, 15.36TB of local NVMe, and a BlueField-4 DPU at 800Gbps. A full rack holds 128 CPUs and 11,264 cores with BlueField-4 DPUs and Spectrum-X Ethernet switching, which CoreWeave says supports more than 11,000 concurrent isolated environments. In its own testing, CoreWeave reports more than 3x faster agent sandbox startup on Vera than on an x86 CPU it doesn’t name. Vera will run bare metal under the same platform and consumption models as the GPU fleet, including spot capacity.
CoreWeave Forge Connects Development and Production #
CoreWeave Forge, launched at the show, folds Weights & Biases Models, OpenPipe’s post-training work, and the open-source marimo notebook project into one development layer for models and agents. It covers experiment tracking, evaluations, agent traces, checkpoints, sandboxed execution, post-training, and inference deployment, and CoreWeave says it’s open across models, frameworks, and other clouds. MasterClass and Canva are already building on it.
Forge ships in Free, Pro, and Enterprise editions, with Pro starting at $60 a month and a 30-day trial. Generally available today: ARIA, Sandboxes, Weights & Biases Models, Serverless SFT, Serverless RL, Registry, Notebooks, and both Serverless and Dedicated Inference. In preview: Agent Lens, Model Distillation, and RL Rollouts, which let a checkpoint load into a live deployment while the training loop keeps running.
CoreWeave’s release says Agent Lens detects 20 percent more critical failures and fixes issues at one-tenth the cost, benchmarked against an unnamed general-purpose frontier LLM; the company’s own blog post puts the cost figure at half, so take the number loosely. Serverless RL is claimed to train 1.4x faster at 40 percent lower cost than a self-managed setup. Workload, model, hardware, and methodology weren’t provided for either.
Partner Network and Clinical Inference Deployment #
The CoreWeave Partner Network, available today, groups integrations CoreWeave says it has tested under production load and qualified on customer demand, across infrastructure, data services, ISVs, security, and models and inference. Named partners include CrowdStrike, VAST Data, Reflection, ClickHouse, LanceDB, Inferact, RadixArk, IBM, and Red Hat. Exa, Parallel Web Systems, and You.com join through a shared search integration for agents hosted on CoreWeave, rolling out in the weeks after the announcement. The pitch is that customers keep their existing serving layers, observability, runbooks, and security tooling as workloads move onto the cloud.
Ennoble Care, which provides home-based primary, palliative, and hospice care to roughly 50,000 patients a year across 15 states, has picked CoreWeave Cloud for clinical AI inference. The deployment runs on reserved NVIDIA RTX PRO 6000 Blackwell Server Edition nodes through CoreWeave Kubernetes Service, with hardware-enforced isolation and zero-trust controls for clinical data and direct engineering support included. CoreWeave claims CKS spins up containers 8 to 10 times faster than a general-purpose cloud alternative, without naming the platform, workload, or test configuration.