Runtime controls add another layer of protection for Harvey and its customers by governing tool access, information flow, and agent actions beyond the initial connector review.
Legal teams work across research platforms, document management systems, and communication tools. Connecting Harvey Agents to those systems gives them more context and more ways to help users complete work. It also creates a security challenge: tools can change after initial review, return malicious instructions, or be exploited in ways that expose sensitive information.
As we rebuilt our Connector Library, we built a Model Context Protocol (MCP) Policy Engine to govern how agents use partner MCP tools throughout a workflow. Prompt injection remains an open problem in AI security, so our approach draws on security research and uses multiple architectural controls to reduce the likelihood and impact of misuse.
Our design draws inspiration from Sondera, Progent, ETDI, and CaMeL, which explore enforcing policies outside the model, limiting tool privileges, and controlling information flow. These ideas inform the boundaries we enforce as agents use partner MCP tools. In this post, we explain how the controls work, what we’ve learned, and where we’re continuing to improve.
Why MCP Integrations Need Runtime Controls #
MCP expands what agents can do through a common, reusable standard for discovering tools, accessing data, and acting across services. It also expands the attack surface: bringing externally supplied tool definitions, content, and interaction requests into an agent’s workflow while also increasing existing supply chain risk. These risks have surfaced in multiple real attack campaigns and disclosed vulnerabilities.
Our approach to MCP security starts with four considerations:
- MCP can grant individual servers power over the workflow. Alongside exposing tools that access data and act across services, servers can, where supported, ask clients to invoke models or collect information from users. This bidirectional design requires explicit limits on what servers can request and what clients will allow.
- Risk compounds across tools. We are concerned about the“lethal trifecta” : combining access to private data, exposure to untrusted content, and external communication can result in impactful prompt injection leading to data exfiltration. MCP makes these capabilities both easy to combine and hard to control across independently evolving integrations. Even a trusted tool can return attacker-controlled content that redirects subsequent calls to retrieve and disclose sensitive information.
- Security depends on implementation. The NSAdescribes MCP’s security posture as “uneven and highly dependent on implementation discipline rather than protocol guarantees.” Each server, client, and host must enforce permissions, validate inputs, and handle consent.
- The protocol keeps evolving.New specifications canclose existing gaps while introducing capabilities withnovel risks .
Our policy engine targets two particularly persistent threats that are harder to mitigate using existing tools. Both can exploit the lethal trifecta to exfiltrate sensitive data. In a tool poisoning attack, malicious instructions embedded in a tool's definition redirect the agent's behavior. In a rug-pull attack, a server introduces malicious changes after it has been approved, exploiting the trust placed in a previously reviewed tool.
Security Reviews Start Before the Connection #
We set and enforce strict security standards for our partner MCP integrations, starting with an in-depth review of each server and its tools. Working with partners, we examine authentication, capabilities, permissions, and data handling; we enforce MCP security best practices and constrain OAuth scopes and tool access according to least privilege where possible. Our data-handling requirements reflect the principles Chad Scott outlines in Your Data, Your Control: How Harvey Manages Customer Data.
New tools and protocol features are not enabled by default simply because a server offers them. Each addition can change what an agent can access, where information can flow, or how a server can interact with users, so we subject additions to review as well. From a systems security perspective, we’re minimizing the trusted computing base.
Assessing What Tool Arguments Can Do
A tool’s read/write label does not tell us everything it can do. A read-only search tool, for example, could still disclose confidential information if that information is placed in a query sent to an external service. We therefore assess two properties of a tool’s arguments:
- Capacity: How much information can the argument carry? An unrestricted text field can carry more than a field limited to a small set of values. Repeated calls can increase that capacity.
- Authority: What does the argument control? A value might supply content, select a document, or specify a recipient. Even a small value can pose a high risk if it controls the entire flow.
These properties help us treat prompt injection as an information flow control problem. They let us assess both malicious tools and malicious uses of legitimate tools based on what information their arguments can carry and where that information can go.
To ground this analysis in what servers actually enforce, we built an internal MCP security analysis tool that runs at integration time. It examines authentication configuration, exposed capabilities, and JSON schemas, collecting information about argument types, declared limits, and return contracts. It extends our initial review by automatically identifying the gaps between the guarantees we want, what the server promises in its schema and documentation, and what it actually enforces.
From Review to Runtime Enforcement #
While mitigations such as safety training, content marking, and classifiers can reduce risk, they are bypassable and do not meet the Harvey security bar in isolation. We must also prepare for stronger attacks as models improve. Following the NCSC’s guidance to limit the consequences of compromise, we primarily rely on architectural mitigations. Enforcement therefore sits in the orchestration layer, outside the model, where policies can constrain proposed actions even when the model follows a malicious instruction. Fundamentally, our MCP Policy Engine relies on a series of defense-in-depth controls to mitigate the consequences of a single tool being compromised. Drawing upon “Systems Security Foundations for Agentic Computing,” three principles primarily guide our approach:
- Least Privilege: Restrict the capabilities available to an agent and the conditions under which it can use them.
- Complete Mediation: Check each partner MCP tool call before execution. Approval to connect a server does not authorize every subsequent action.
- Secure Information Flow: Use workflow context to restrict combinations of capabilities that could expose private information or allow untrusted content to drive consequential actions.
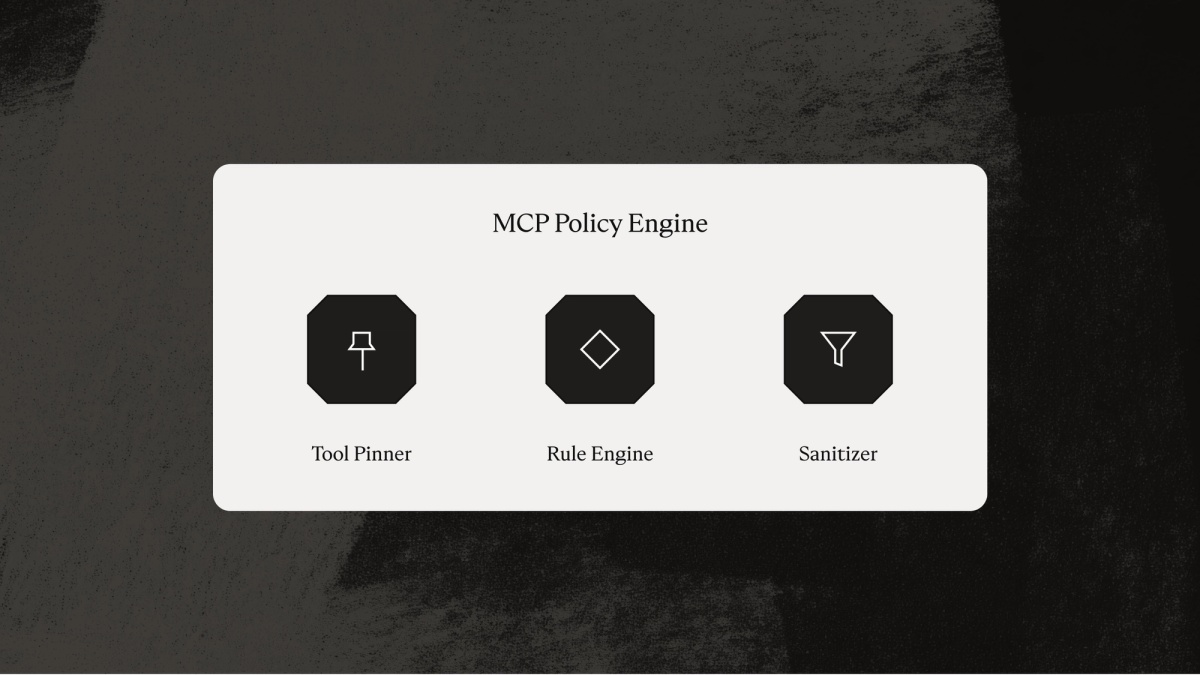
The controls operate at different points in the lifecycle.
These components connect our security reviews to the agent’s execution, with defined responsibilities at each stage.
Keeping Tool Reviews Current
MCP does not require versioning of individual tool definitions, so a tool can change after approval. The MCP Policy Engine has a “Tool Pinner” that records approved tools, including their model-facing descriptions and input schemas. During discovery, it compares each connector’s advertised catalog with that baseline and flags additions, removals, and changes for Security review.
That creates a practical trade-off. Pinning a tool on first use and rejecting all updates would guard against rug-pull attacks, but connector catalogs change frequently. Some changes alter a tool’s capabilities; others are minor description edits. The pinner currently generates a substantial volume of alerts, so we need a way to prioritize review.
We’re developing an approach we call fine-grained pinning and semantic edit classification. It breaks changes into components and assesses their policy-relevant properties in terms of risk. That assessment, together with contextual information and strategic human-in-the-loop (HITL), will inform which version of a tool is delivered and how the Policy Engine handles it. We’re also developing ways to examine cumulative changes to account for salami-slicing attacks, in which a series of small edits adds up to a consequential change. Wherever possible, we’ll use deterministic checks and test our assumptions against adversarial examples.
Evaluating Actions in Context
A proposed tool call can carry different risks depending on what happened earlier in the workflow. For example, a call to a tool that can transmit information externally may warrant a different decision after an agent has accessed private data or encountered untrusted content. Our MCP Policy Engine evaluates these sequences of calls, or agent trajectories, before the proposed call runs.
To support those decisions, we assess each tool’s purpose, capabilities, and risks and record them in structured annotations maintained by Harvey. These are distinct from a server’s self-reported hints, which we treat as untrusted. The annotations give our policies concrete tool properties to evaluate alongside the proposed arguments and relevant call history.
Our Security team writes policies in Rego, chosen for its flexibility in expressing rules over structured data, and runs them with Regorus. The interpreter receives tool identifiers, Harvey’s annotations, and relevant call history. It does not inspect prompt content or customer data. Keeping those inputs explicit makes policy decisions easier to test.
For each proposed call, a policy can permit it, deny it, or execution for explicit user approval. If the engine cannot complete the required checks or reach a valid decision, it denies the call. Workspace settings can add restrictions but cannot override an engine denial. Approval requirements reflect the call’s context and potential consequences. Our policies also address the risks of agent-to-agent interactions. MCP tools that create or invoke agents can form implicit multi-agent systems, where one agent’s response prompts another delegation and another call. Exploiting cycles in these interactions offers a path to hijacking multi-agent systems. Our policies aim to detect and interrupt these cycles, giving users a chance to review the workflow and decide whether to continue.
Evaluating and Refining Policies
Effective enforcement depends on accurate annotations, sufficient context, and well-specified rules. We are constantly evaluating our rules against adversarial behavior and legitimate workflows through red teaming, quality evaluations, and observations of tool use. This enables us to maintain security without compromising usability.
The policy engine in turn empowers our detection and response tooling with prompt injection detection heuristics. Non-sensitive information about tool calls, policy decisions, risk flags, and network telemetry guide our Agentic Security Operations Center and support investigations. Findings can further inform tool reviews, evaluations, and policy coverage. This allows us to establish an interplay between detection and response tooling and product security tooling.
Removing Hidden Characters
Stealthy prompt injections exploit the gap between what users see and what models process. Research on invisible characters shows how they can carry instructions a model interprets but a reader never sees. We address this threat with our MCP Policy Engine’s Sanitizer, which removes selected hidden characters and control sequences from tool results before they enter the model’s context.
It also detects potentially misleading combinations of lookalike characters from different writing systems. We scope these controls to preserve legitimate multilingual content and keep transformations predictable and testable.
We can address specific vectors for stealthy prompt injections through controls such as our sanitizer, but it remains true that text can still contain malicious instructions. That’s why we build architectural controls that constrain the consequential actions an agent can take in response to untrusted content.
What We’re Improving Next #
The MCP Policy Engine builds on the commitment Mike Parowski describes in his post on Harvey’s agentic SOC: We make security central to our engineering work and design our defenses for sophisticated adversaries. That means adopting evolving standards and conducting original research where the answers remain unsettled. As with our work on embedding reversal, we’re continually building, refining, and testing our security architectures in light of the latest research.
We’re investigating automated improvements to policy creation and refinement that do not compromise our security guarantees while mitigating human failure modes. To move closer to the guarantees demonstrated by CaMeL, we’re exploring program analysis approaches to agent behavior that are tied to capability-based constraints. We want formalized, automatic controls that are easy to reason about, verify, and test. Stay tuned for more research from the Harvey security team!
If this work interests you, join us at Harvey to tackle open problems in AI security and build defenses that protect our customers’ most sensitive work.