AI’s hidden energy tax: More than 80% of scale-up traffic is just memory moving around
Memory bottlenecks are emerging as one of the costliest problems in AI infrastructure as inference overtakes training. GPUs sit idle waiting on data, while high-bandwidth memory, or HBM, stays bolted to processors that cannot share it.
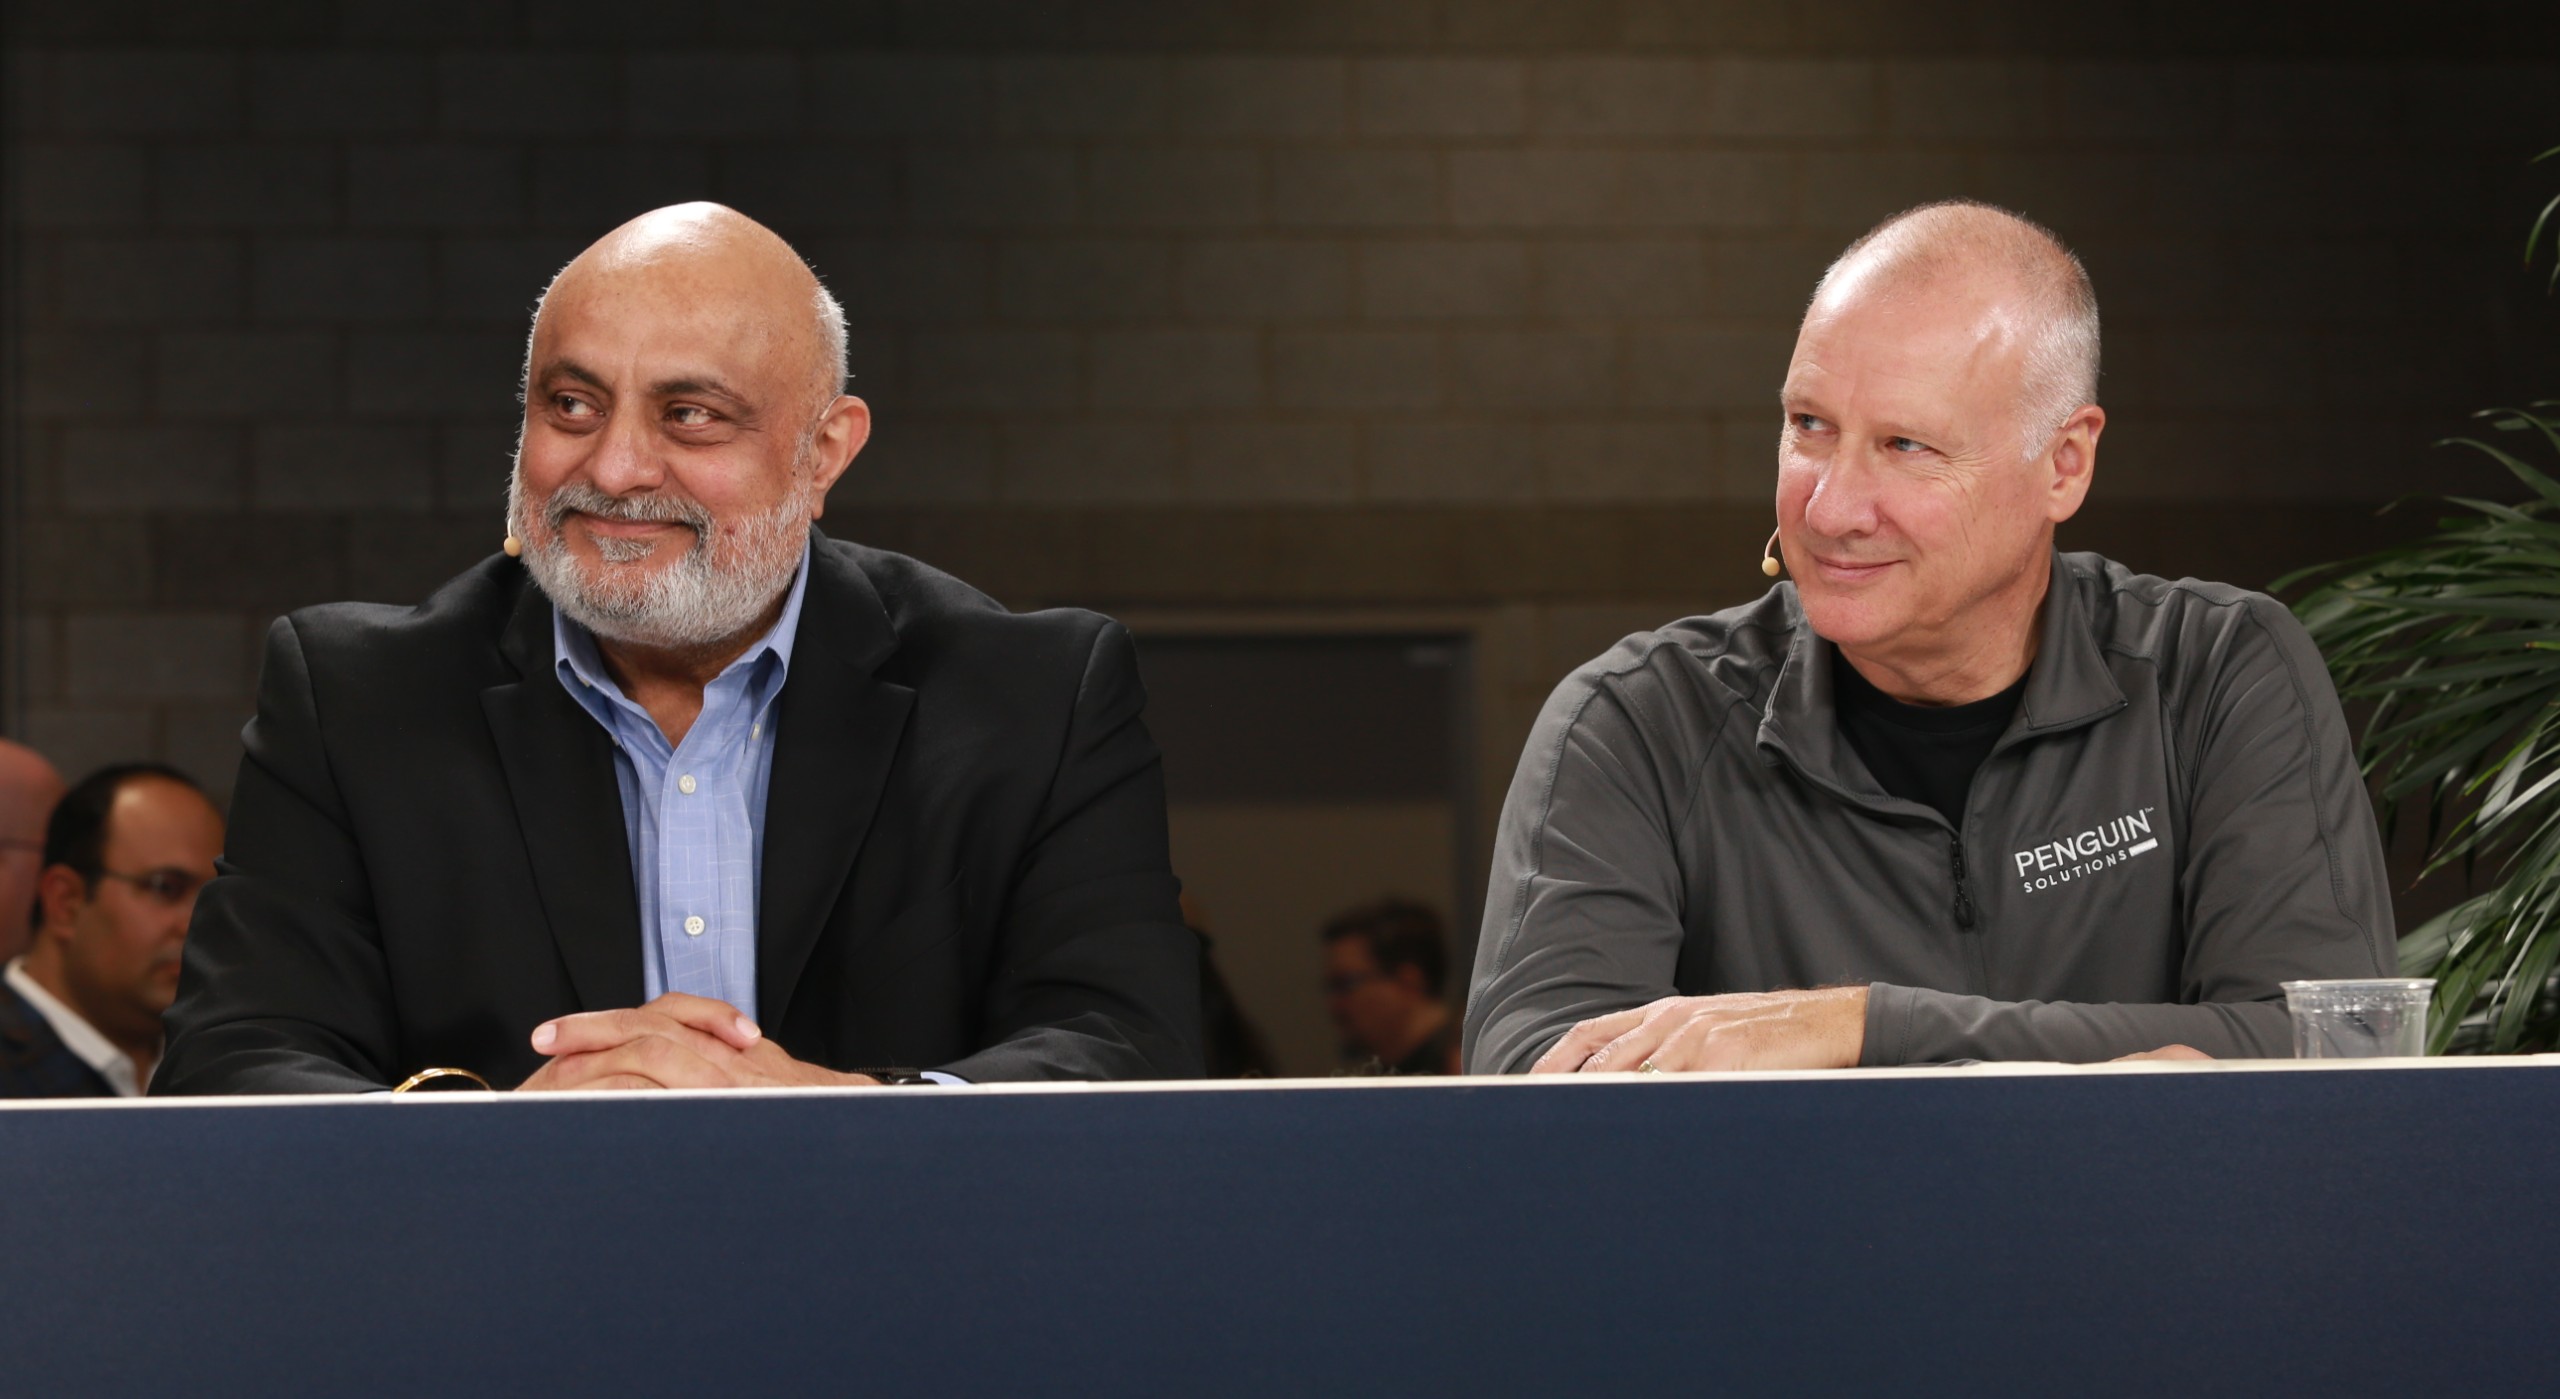
Photonics is shaping up as one way out. Marvell Technology Inc. has been pairing optics with photonic memory to stretch memory beyond the edge of a chip. The payoff is better efficiency in data centers enterprises have already paid for, according to Preet Virk (pictured, left), senior vice president and general manager of the Photonic Fabric Business Unit at Marvell.
“In the data center today, we have a lot of room for improvement of efficiency,” Virk said. “And when I say efficiency, I’m alluding to the wasted flops because we have GPU utilization that’s very low.”
Virk and Andy Mills (right), vice president of advanced product development at Penguin Solutions Inc., spoke with theCUBE Research’s John Furrier and Amit Eyal Govrin at SC26, during an exclusive broadcast on theCUBE, SiliconANGLE Media’s livestreaming studio. They discussed how photonics and shared memory pools can ease memory bottlenecks in AI infrastructure. ( Disclosure below.)*
Shared pools take aim at memory bottlenecks
Penguin’s MemoryAI Photonic Appliance moves HBM into a separate box tens of meters from the GPU, linked by Marvell’s Photonic Fabric. Each appliance holds 16 terabytes of HBM and DDR5 memory that servers across multiple racks can share, Mills explained.
“The challenge there is making sure your LLM doesn’t forget what you started talking to it about 10 minutes ago,” Mills said. “To do that, you need a large amount of memory, large token lengths.”
Optics also changes the energy math. Copper still works inside a rack, but crossing a pod of thousands of GPUs requires optics, according to Virk. More than 80 percent of scale-up network traffic is memory transactions, and a shared pool means much of that data never moves at all, he noted.
“Within data movement, the memory transactions are a place to focus on,” Virk said. “So with this solution versus a copper-based data movement, we could immediately get to a quarter of the energy, picojoules per bit, of data movement.”
Agents raise the stakes, generating far more token requests than human users ever did. As inference spreads across more racks and sites, Mills sees shared pools as the practical answer to memory bottlenecks.
“If anything, distributed encourages shared because you don’t want to recompute,” Mills said. “The whole thing about KV cache was a huge success because it stops recomputation of the same data. And when you can share that data on a broader base and wider across more racks, your efficiencies go up as well.”
Here’s the complete video interview, part of SiliconANGLE’s and theCUBE’s coverage of SC26: ( Disclosure: Penguin sponsored this segment of theCUBE. Neither Penguin nor other sponsors have editorial control over content on theCUBE or SiliconANGLE.)*
Photo: SiliconANGLE
Support our mission to keep content open and free by engaging with theCUBE community. Join theCUBE’s Alumni Trust Network, where technology leaders connect, share intelligence and create opportunities.
- 15M+ viewers of theCUBE videos , powering conversations across AI, cloud, cybersecurity and more
- 11.4k+ theCUBE alumni — Connect with more than 11,400 tech and business leaders shaping the future through a unique trusted-based network
Are you an AWS customer? Support SiliconANGLE financially by buying your AWS services from our Marketplace portal page and links: https://siliconangle.com/aws-marketplace/
About SiliconANGLE Media
theCUBE AIand theCUBE SuperStudios — with flagship locations in Silicon Valley and the New York Stock Exchange — SiliconANGLE Media operates at the intersection of media, technology and AI.
Founded by tech visionaries John Furrier and Dave Vellante, SiliconANGLE Media has built a dynamic ecosystem of industry-leading digital media brands that reach 15+ million elite tech professionals. Our new proprietary theCUBE AI Video Cloud is breaking ground in audience interaction, leveraging theCUBEai.com neural network to help technology companies make data-driven decisions and stay at the forefront of industry conversations.