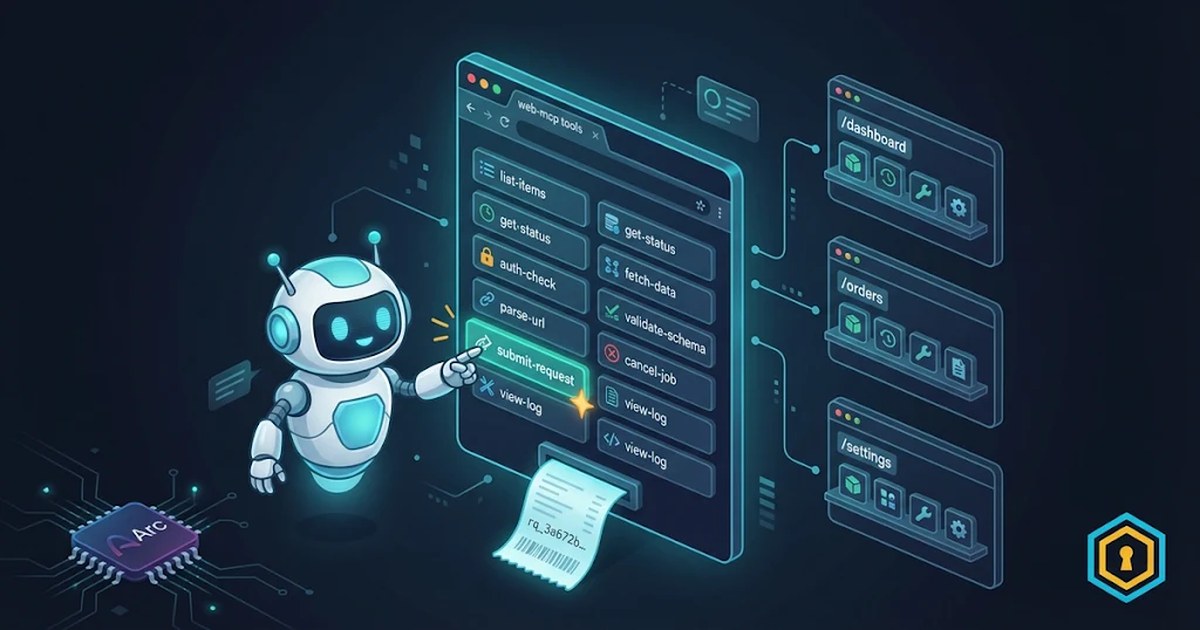
A website can now hand a browser agent a structured menu of tools instead of HTML to scrape. We shipped 16 page-scoped WebMCP tools on production - one shared registry behind three facades (in-tab WebMCP, /mcp/public JSON-RPC, plain REST), honest async submit/poll into the ops inbox, and a consent-gated public QA corpus. External verification found two real bugs, both fixed.
WebMCP is a W3C draft - already documented by OpenAI as Site tools and shipping in Chrome 146+ behind an Origin Trial - that lets a page register typed tools into document.modelContext: the page itself hands an agent a menu, so it stops scraping. We put it on production: agentbadge.xyz exposes 16 tools from one shared registry across three facades (WebMCP in-tab, /mcp/public JSON-RPC, plain REST), page-scoped so a scanner-page agent sees scanner tools only. One write action - submit-request - posts into the ops inbox; poll-request returns honest async states; consented answers materialize into a public QA corpus that search-agent-qa can hit instantly. Live Chrome-OT verification found two shipped bugs - a publicly cacheable submitted poll body and a pg/json codec that 500'd on top-level string writes - both fixed and regression-tested.
Why does a website need tools for agents at all? #
Agents don't need another API key - they need a menu on the page.
For a junior: today an AI agent that wants to use your website has two bad options - scrape the HTML and guess, or go read your REST API documentation and wire a client. WebMCP is a third option: the page itself registers JavaScript functions - name, description, JSON schema - into document.modelContext, and any WebMCP-aware agent can list them and call them with structured arguments. No key, no SDK, no parsing.
Three things converged in November 2026 that made us ship this now:
- OpenAI documented Site tools - their implementation of the WebMCP proposal. The built-in browser in the ChatGPT desktop app discovers site tools and uses them while you watch the same page. (
learn.chatgpt.com/docs/webmcp) - Chrome runs an Origin Trial -
document.modelContextlives behind--enable-features=WebMCPon Chrome 146+; we tested on Chrome 153. - The W3C community spec (
webmachinelearning.github.io/webmcp) defines the contract:registerTool,getTools,executeTool.
And the honest positioning, straight from OpenAI's own doc: WebMCP is for when the human and the agent look at the same page; backend MCP is for integrations that run without one. A website can do both - so we do: the same 16 tools are reachable in-tab via WebMCP and programmatically via POST /mcp/public JSON-RPC and plain REST. REST stays the source of truth; both facades are thin adapters.
What can an agent actually do on the site? #
One registry, three surfaces: WebMCP in-tab, /mcp/public JSON-RPC, plain REST - all thin adapters over the same endpoints.
16 tools today - but not 16 everywhere. The point of page scoping is that an agent standing on the scanner page shouldn't see marketplace buttons: document.modelContext.getTools() returns the shelf for that page, from PAGE_TOOLSETS in the shared registry:
Real output: 16 on /, a focused shelf on each scoped page.
- Discovery & trust :
agent-readiness-scan,get-compliance-score,search-rules,verify-verdict,check-address-risk,passport-verify,badge-generate - Marketplace :
list-services,browse-tasks,get-task,get-task-status - Interaction :
submit-request,poll-request,search-agent-qa,list-surveys,how-to-register
Read tools are keyless thin wrappers - the same JSON the REST endpoints return, plus one discipline we enforce in every tool description: no secrets, no PII, no internal URLs. agb_ credentials never appear in a tool result. Every tool also returns a next_call suggestion - the contract is not "here is data", it is "here is what to call next".
We did not start from zero. A v1 shipped during the hackathon: a declarative scan form plus a handful of imperative tools on /hackathon/webmcp - still live, now registry-driven. V2 is what the v1 taught us: one shared registry instead of scattered registrations, page-scoped shelves instead of everything-everywhere, and a real write path instead of read-only demos.
How does an agent ask a question - and get an answer? #
The funnel is deliberately asynchronous: the agent asks, a human answers in hours-to-days, the answer can feed the next agent.
There is exactly one write action: submit-request. It posts a question into our ops inbox (the agent request inbox from our previous article - this is its browser-native front). What comes back is deliberately boring:
A request_id, not an answer. Async is a feature, not a broken chatbot.
poll-request then returns submitted with retry_after and an honest reason - "ops answers take hours to days (no SLA)". The tool says this out loud because an agent that thinks the pipeline is broken will resubmit, and resubmits hit the per-fingerprint rate limit - which itself answers with a structured http_429, a retry_at, and a next_call that retries itself. Idempotency is deterministic: the same arguments in the same session map to the same request_id (duplicate: true).
Then, on the other side of the wall, an ops human answers. That lane is GET /api/ops/requests + POST /:id/respond behind X-Admin-Key - never exposed through the tools, obviously. And the next poll just works:
Verbatim prod: completed, the answer inline, and a suggestion where to look next.
Where do good answers go? A corpus with a consent gate #
Private by default, public by consent, reversible always.
Every answered request can become public knowledge - but only if the asker opted in. publish_to_qa defaults to false: your question and our answer stay yours. When consent is on and the answer exists and the request isn't flagged spam, completing the request materializes a qa_* pair into the public corpus - the thing search-agent-qa reads and the fast-path that answers repeated questions instantly, uses counter ticking up per hit. Ops can retract a pair at any time and it drops out of search and matching, idempotently.
The corpus as it stands - and an honest empty state when nothing consented exists yet.
This is the part we think most agent-facing sites will get wrong, twice: first by publishing everything (a privacy breach with a search box), then by showing an empty corpus as a bug. Ours says what it is: "No public QA answers yet - the corpus only grows from consented, ops-answered requests."
What did production verification actually break? #
Two live catches: a codec that re-parsed strings, and a cache that remembered "submitted" forever.
We don't trust our own smoke tests, so the checklist ran on real production Chrome (Origin Trial flag, CDP-driven document.modelContext) and an external agent. It found two shipped bugs - both now fixed with regression tests:
Bug 1 - the stale "submitted". Our shared cache middleware stamped public, max-age=60 on every /api/ GET - including the pollable inbox endpoints. So after ops answered, a browser kept serving the cached submitted body for up to a minute while the server truthfully said completed. For a polling agent that's a lie generator. Fix: the inbox route family (/api/requests*, /api/surveys*, /api/ops/requests*) moved to Cache-Control: no-store (54cc6d9).
Bug 2 - the string that broke the codec. agentRequest.response is a json column. Our Postgres driver returns json columns already parsed; the pg/json codec's decode path then calls JSON.parse again - fine for objects, fatal for a top-level JSON string. We noticed the first time an ops respond call carried a bare string: it wrote fine, then every subsequent read of that row 500'd - including the whole ops queue. Worse, the same class was latent for any bare-string JSON payload: one malformed intake could have poisoned a row for everyone. Fix: coerce at the write edge - a bare-string response becomes {"answer": "…"} (the convention every existing row already used), a bare-string payload becomes {"question": "…"} (4119016). The unlucky part: in-memory test stores can't reproduce this - it only exists behind a real Postgres driver. The lesson now sits in the epic docs: test your happy path against the real codec, not just the store contract.
Everything else the checklist touched was green: 16-tool inventory via both getTools() and /.well-known/webmcp.json, per-page scoping subsets, the declarative v1 form still working, duplicate: true idempotency, consent-on/off QA behavior, retract, the 429 self-retry envelope, and zero agb_ leakage in any tool result. 10,768 server tests + 98 e2e + one real browser walk.
What can you verify right now? #
The read half needs nothing but curl - or a WebMCP browser:
curl -s https://agentbadge.xyz/.well-known/webmcp.json | jq '.tools | length'

curl -s -X POST https://agentbadge.xyz/mcp/public \
  -d '{"jsonrpc":"2.0","id":1,"method":"tools/list"}' | jq '.result.tools | length'

curl -s "https://agentbadge.xyz/api/requests/qa?q=passport"
A menu isn't a promise that the kitchen is fast - it's a promise that the agent can read it. The page is the registry; the human still writes the letters.