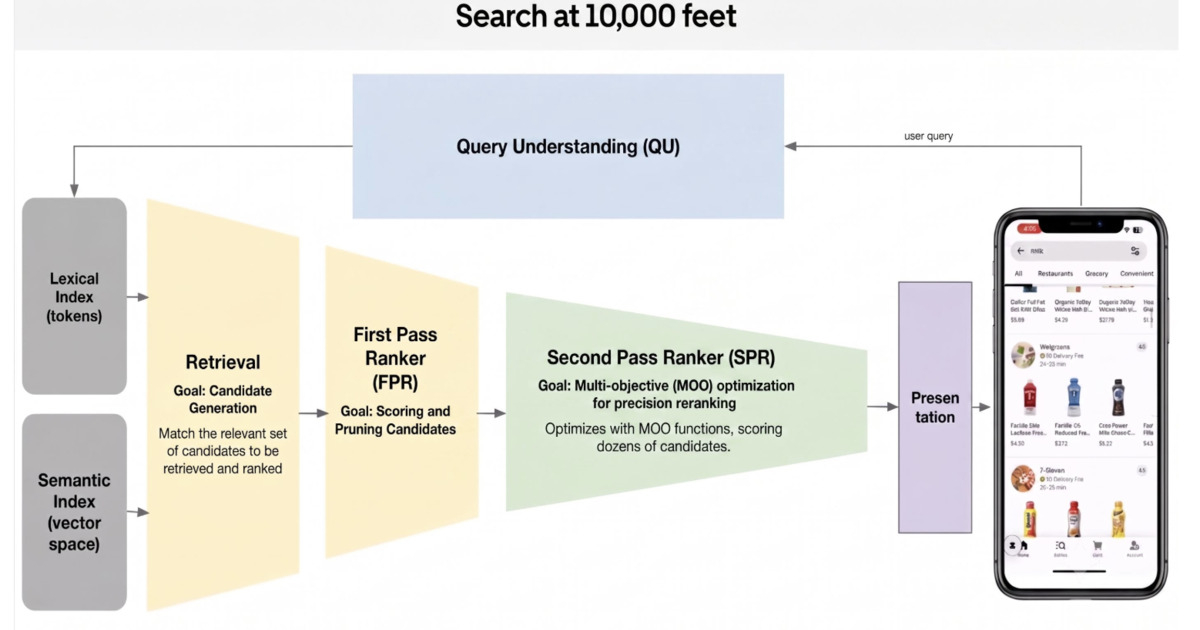
Uber has rebuilt major parts of the Uber Eats search pipeline and reports a 50% reduction in end-to-end search latency. The changes span retrieval, feature hydration, ranking, advertising, presentation, and infrastructure, while an agentic coding workflow was also used to identify, benchmark, and validate additional optimizations.
The work began with a change in the primary latency metric. Instead of focusing on backend API response time, Uber began measuring Above-the-Fold completion, defined as the time until the first screen of results is rendered with images. Pagination with server-side caching reduced the initial response, while asynchronous rendering allowed result items to be processed concurrently. Uber reports that these changes improved Above-the-Fold latency by more than 200 milliseconds.
Uber Eats search pipeline architecture (Source: Uber Blog Post) Uber reduced retrieval work after finding that tens of thousands of candidates were hydrated before ranking, and discarded many of them. Removing low-value retrieval strategies cut about 120 milliseconds, while product-level embeddings reduced data lookups by more than 100 times and saved another 50 milliseconds. Separating ranking hydration from presentation data reduced latency by more than 100 milliseconds, with dependency removal and request hedging contributing another 35 and 40 milliseconds, respectively. The advertising path was redesigned with column-oriented bid data, in-memory access, and less serialization, reducing latency by about 130 milliseconds. Additional infrastructure changes included parallel encoding, smaller embeddings, connection management improvements, and Go data structure changes to reduce garbage collection overhead.
The approach has drawn attention from engineers discussing the work publicly. Anubhooti Nagar described the performance challenge as,
It’s less about doing things faster and more about doing less work and avoiding unnecessary waiting.
Nagar also highlighted Uber’s
Measure, Identify, Fix, Validate loop as a model for continuous performance optimization.
Pratik Dhanave emphasized that the result came from incremental optimization rather than a single architectural change, describing it as no single big idea behind it, but a long list of careful decisions across the full stack. He pointed to changes across latency measurement, hydration, advertising, and infrastructure as examples.
Vidya Pandey distilled those changes into three principles: Do less work. Start work earlier. Remove unnecessary dependencies. Pandey also connected Uber’s planned microbatching approach with techniques used in AI systems to reduce synchronization between processing stages.
The changes build on Uber’s existing search platform, which has previously been described as using Apache Lucene, Spark-based indexing, Kafka-based streaming updates, and a distributed serving layer. InfoQ’s previous coverage of Uber’s search architecture provides additional context on the platform’s earlier indexing and query execution work.
Uber is now exploring end-to-end microbatching, product-based retrieval, Zero Pass Ranking, and HTTP multipart streaming. The company reports that early product-based search testing has produced more than a 50% reduction in p99 latency. The planned changes allow processing stages to overlap rather than waiting for entire preceding stages to complete.