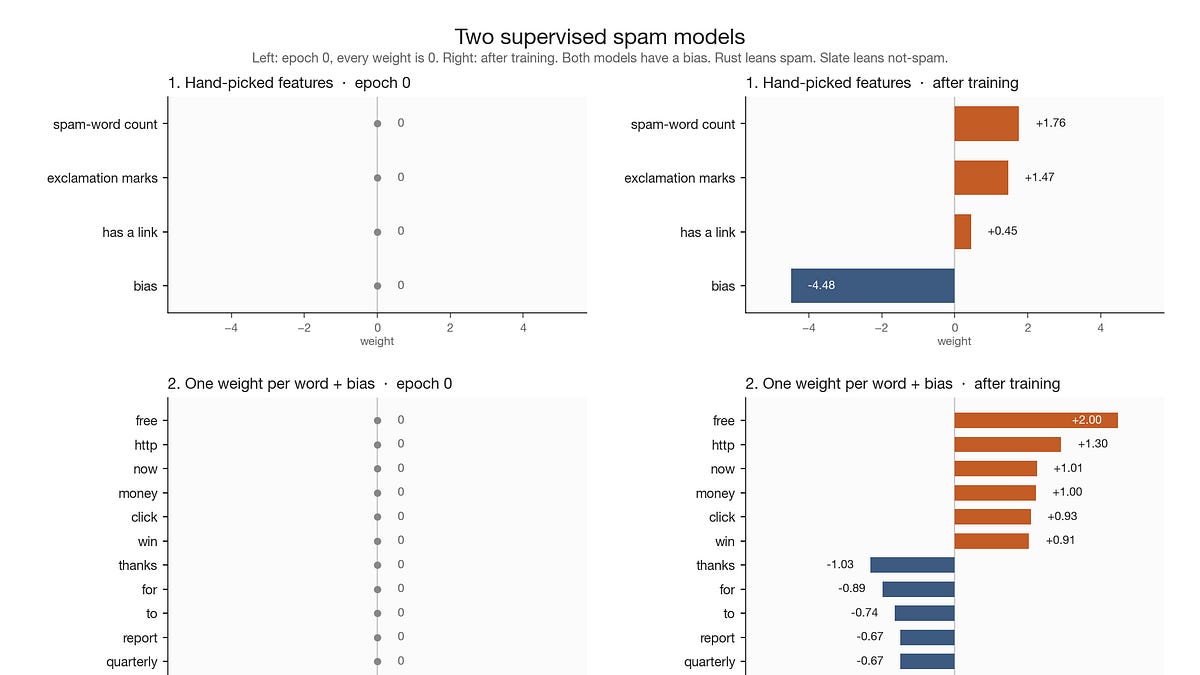
Quick recap of the simplest machine learning models, using spam.
You have emails that are already marked spam or not.
You train: the program looks at them and learns a few numbers (i.e. weights). Then a new email comes in and you use those weights to decide.
I did two versions. Both have labels on the inputs, so both are supervised. You know the job: spam or not. Inference is the same. A new email comes in. You want an answer. What changes is how you turn the email into numbers.
- I pick the features
Count of words from a list I wrote, count of !, and whether there is a link. Training only learns how much those three matter. Three weights, plus a bias.
- The features come from the emails
No list. About 70 words from the data, one weight each, all starting at 0. A word in spam goes up. A word in not-spam goes down. How often a word appears is a count. That is not the weight.
Same loop in both. Go through the emails many times. Guess, compare to the label, change the weights. Stop, and the weights are the classifier.
Both models also learn a bias: the guess when every feature is 0. At epoch 0 every weight is 0, so both models guess 0.50. After training, Model 1’s bias is about -4.5. Model 2’s is about -0.74, because ham words like thanks already pull toward not-spam.
Github repo: https://github.com/nirmal91/model-experiments