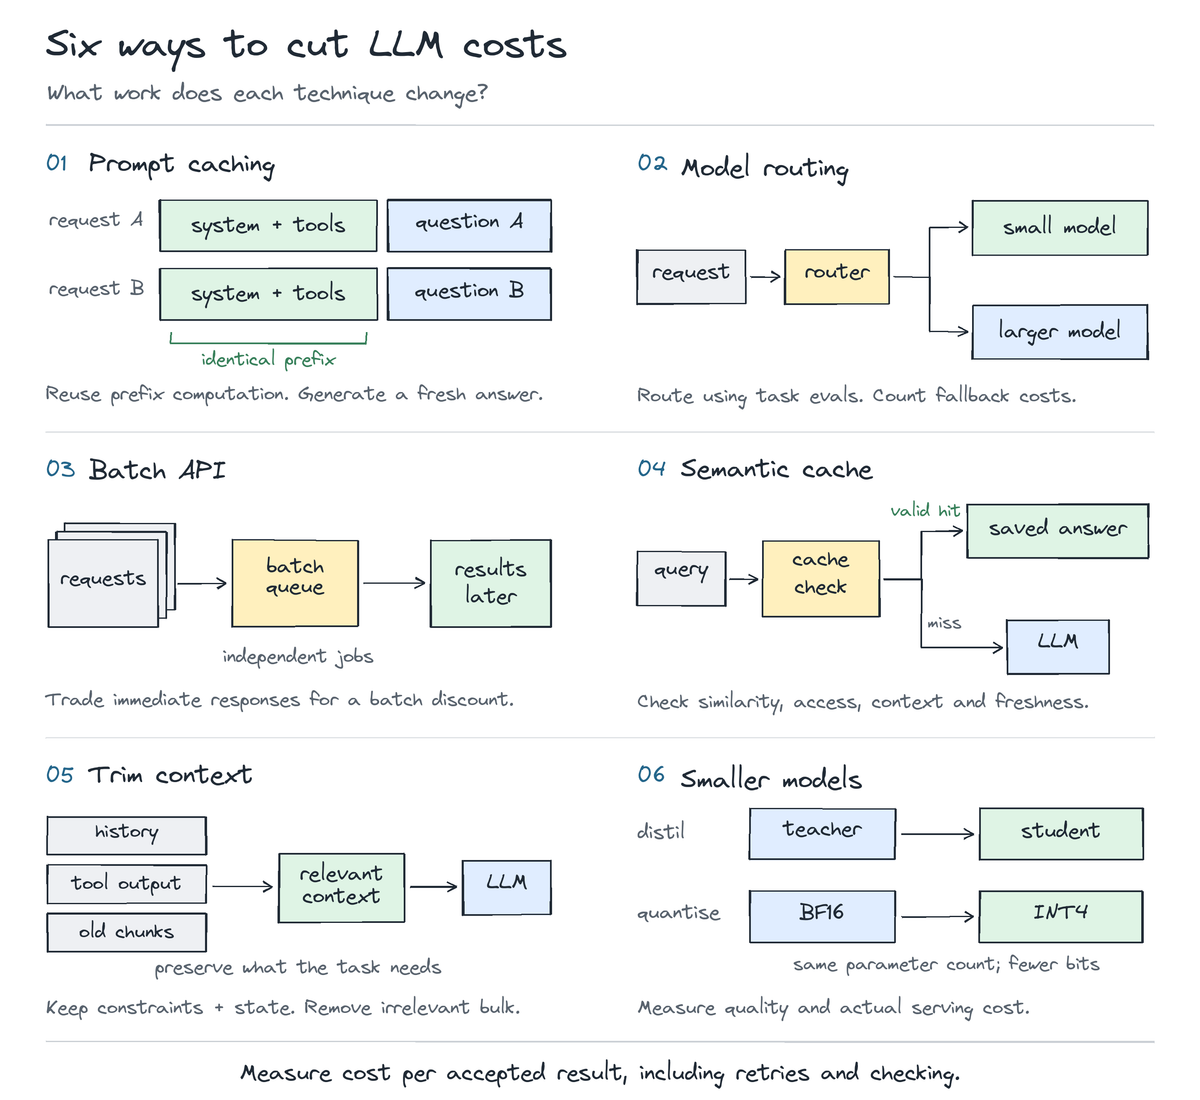
- Prompt caching. Put stable instructions, examples and tool schemas before changing inputs. An identical prefix can reuse earlier computation; the model still generates a fresh answer. Measure cache hits and account for cache-write costs.Claude Platform Docs
- Model routing. Send each task to the cheapest model that passes your evals. Use a larger model where it earns its cost. Include the router and fallback calls when measuring savings.
- Batch API. Move work that can wait, such as overnight extraction or offline evals, to an asynchronous batch API. Providers such as Anthropic discount these requests. You are trading response time for price.Claude Platform Docs
- Semantic caching. Reuse a stored answer when a new query has equivalent meaning and relevant context. A valid hit skips generation. Similar wording alone is insufficient: enforce access boundaries and invalidate stale answers.Docs
- Trim context. Remove irrelevant retrieved chunks and bulky old tool results. Preserve task constraints, decisions and current state. Run evals after trimming, and watch for lost prompt-cache hits when you change the prefix.
- Smaller models. Choose a smaller model that meets the quality bar, or train one through distillation. Quantisation is different: it reduces numerical precision, not parameter count. For self-hosting, benchmark memory, throughput and quality on your actual hardware.Hugging Face
Measure cost per accepted result. Count inference, routing, cache infrastructure, retries and human checking. Keep quality and latency visible alongside the bill.
Join AI engineers getting weekly insights on agents, RAG & production LLM systems
No spam, no sharing to third party. Only you and me.
source & further reading
anup.io — original article
What is Jev? A Simple Primer on AI That Makes Decisions
Defining an AI Agent
TIL: What’s actually different about GGUF and ONNX?