I’m a technology and human rights researcher. For the past few years, one of my focuses has been the question of how language shapes the ways we benefit from, or are harmed by, AI. I developed an open-source platform for language-pair analysis of LLM responses across different languages and contexts. I’ve also worked on evaluating policy-prompts guardrails and on whether giving LLM guardrails access to tools can make them more reliable and trustworthy (this work was recently accepted to NeurIPS! Yay!!).
Recently, though, I was on a panel at RightsCon on the human rights impact assessment of agentic AI. It got me thinking more about which aspects of language matter when evaluating LLM agents. I wanted to move beyond asking whether a model performs differently when I ask the same question in English versus Farsi (my native language), and look instead at the whole agentic trajectory (reasoning, planning, search, source selection, source hierarchy, artifact creation) while taking language and context into account.
So I decided to run a test.
The Task: Three AI Agents Updating the World Bank Open Data Platform for U.S. and Iran Country Profiles
The task was to fill in missing information in the World Bank Global Public Procurement Database, using official data for the US and Iran. I ran it in The task English for the US and Farsi for Iran (image below), with three agents:
- Meta’s Muse
- Anthropic’s Claude Cowork, Opus 5.5 Medium
- OpenAI’s GPT 6.1 Sol, Medium
Below is the exact prompt I used for all three:
I intentionally used the web versions of these services (not the app or terminal versions) to reflect what everyday users experience. The distinction matters for monitoring and logging an agent’s actions, which I discuss below.
This post is less about which agent performed better or faster, and more about how the agents behave differently around access to information, language representation, contextual understanding, transparency, human-in-the-loop, and safeguards.
You can find all the results in the following files:
- Output excel files for Muse, GPT, and Claude ( here )
- Each agent’s self-generated work trajectory after receiving the prompt ( here )
- Text files extracted from screen recordings of the agents’ actions ( here , andfull recording here )
Below, I summarize my observations.
Human in the Loop (HITL): From repeated permission prompts to almost no intervention
For those of us working in digital rights, human-in-the-loop (HITL) oversight of AI agents joins a longer line of debates about “informed consent,” from GDPR consent requirements to cookie pop-ups and the routine ticking of Terms of Service and Privacy Policy boxes. With that in mind, I paid close attention to how each agent involved me during the experiment.
Permission to Access Websites
For accessing and fetching information from websites, GPT asked for permission only once, at the very beginning of the task. It requested access to websites and offered an “allow all relevant sites” option, which I selected. After that, it did not ask again. Claude asked questions throughout the task, both about accessing websites for research and about extracting material from the World Bank site. Unlike GPT, it offered no “allow all relevant sites” option, so it requested permission each time: nine times for the US task (all .gov websites) and nine times for the Iran task (mainly .ir domains and also fa.wikipedia sources). I approved every request.
Claude also ran into a technical limit that triggered a different kind of HITL moment. For both Iran and the US, it couldn’t load the live GPPD country profiles, because the portal builds its pages with JavaScript, and Claude’s sandbox network policy blocked access to the World Bank data file. Claude stopped and asked whether I wanted to upload the page (as a pdf) myself or let the work continue without it. I skipped the question, so it continued and took its information from the World Bank’s GPPD DataBank API instead. However, the DataBank holds 2018 data, while the portal shows a 2022 profile. As a result, Claude’s baseline data was different from GPT and Muse.
Muse did not ask for any permission until the fourth part of the task, which required registering on the World Bank website and up information.
All three agents completed the task up to the point of creating the spreadsheets, and described their confidence in the results they generated.
Account registration on the World Bank website
The final part of the task, registering on the World Bank portal and up the changes, is where things became more interesting because it required the agents to take a more significant actions rather than just gather information.
Claude and GPT both stopped at this point and handed the registration and up over to me. Muse, however, kept going. Without asking me or showing me the Terms of Service, it registered an account under the email address david.jones@gsa.gov. You can see Muse’s full back and forth here.

The table below summarizes how each agent approached this last part of the task and cybersceuirty implications about it.1
Monitoring and Observability: Agents vary widely in how much they reveal and how easy they are to inspect
There is an ongoing debate about whether AI labs should expose a model’s full chain of thought (CoT) and action trace, and if so, how much. Labs have given several reasons for holding back. OpenAI chose not to show o1’s raw CoT to users, citing user experience, competitive advantage, and the value of keeping the CoT available for internal monitoring. Anthropic noted that raw reasoning can contain incorrect or half-formed thoughts and that malicious actors could use it to build better jailbreaks. There is also a gaming and reward hacking concern, and “CoT unfaithfulness”.
To understand an agent’s behavior, however, evaluators need to know when and why things happen, which is only possible with a monitoring system in place and access to the agent’s complete trajectory. For an evaluator outside an AI lab, without that access, it is nearly impossible to fully make sense of an agent’s behavior. And if outside evaluators can only see partial trajectories, and any conclusions they draw can be dismissed for lacking complete information, what is the value of independent evaluation?
Knowing these limitations, I tried my best to collect, monitor, and check as much of each agent’s work as I could, again putting myself in the position of an ordinary researcher tasked with updating the World Bank information portal.
- Since there is no one-click way for ordinary users to extract a complete record of an agent’s work trajectory, I watched each agent work live and recorded everything clickable and visible on screen. Once the task was finished, I gave the recordings to ChatGPT to extract the text and make it searchable. To give you a sense of what this looks like, here is a snippet (left: Claude, middle: Muse, right: GPT, sorry for the size and illegibility).
- Self-reported trajectories. When the task was done, I prompted each agent to create a text file describing what it did, including errors, how it handled them, workarounds it used, websites it searched, and more. Muse and GPT each produced a downloadable .txt file, while Claude declined, stating that it went against its safety policy, stating “reasoning_extraction.”That said, self-reported trajectories can not be fully trusted; I have seen mismatches in the past between what agents actually did and what theyreported . So I gave these reports little weight, but if you’re interested in reviewing them and spotting matches or mismatches, the files arehere .
- Analysis. I then used the output Excel sheets and the text extracted from the screen recordings to conduct the analysis, both on my own and with help from Claude Code to sift through the data and generate tables. I cross-checked all of the data myself.
Below is some information about how much information on agents work trajectory is available in each LLM agent’s web UI.
Multilingual Performance: The agents could write in Farsi better than they could retrieve and research in Farsi
A few observations and then I’ll get to my points:
-
All three agents answered in fluent Farsi, but the Iran results were far weaker than the US ones. Of Iran’s 138 N/A fields, GPT and Muse each filled only 21 with a real value; for the US, they filled51 and 64 of 130 .
-
For the US, 76–89% of each agent’s citations came from official government sites and the rest from legitimate international organization websites. For Iran, it was11–22% .
-
Low-authority sources crept in, including a Telegram channel, a Medium post, Grokipedia, or websites run by Iranian diaspora media groups such as Iran International. Claude seemed to be more conservative about finding workarounds when websites were unavailable and often preferred English language sources even with low legitimacy.
-
Claude could only open 3 out of the 16 Farsi pages it tried. GPT and Muse cited 11 Persian sources each but showed reading only3 and 7 of them respectively.
-
Knowledge gaps got filled with something else:
- Claude used headlines and its own memory (sometimes contradicting with what it found), and said so.
- GPT used republished copies of the law.
- Muse mostly read a 2009 English translation but cited the official Persian page.
My point is not that I expected the Iran/Farsi tasks to have the same outcomes as the US/English ones. After all, the Iranian government has made it very difficult for foreign IP addresses to access official websites and domains ending in .ir (you can read more about this in the context of Iran’s National Information Network). My point is about the agents’ differing workarounds and source prioritization.
For me, this brought to mind the digital rights and language inclusion work that the good people of Global Voices have done for years, including on net neutrality and language access. What does all this mean for an AI agents era? And from an AI sovereignty perspective? One of AI sovereignty’s promises has been language diversity and support for local languages. LLM output quality, and perhaps safeguards, keep improving, but we also need to think about what language localization should look like in agents reasoning, searching, and prioritizing sources.
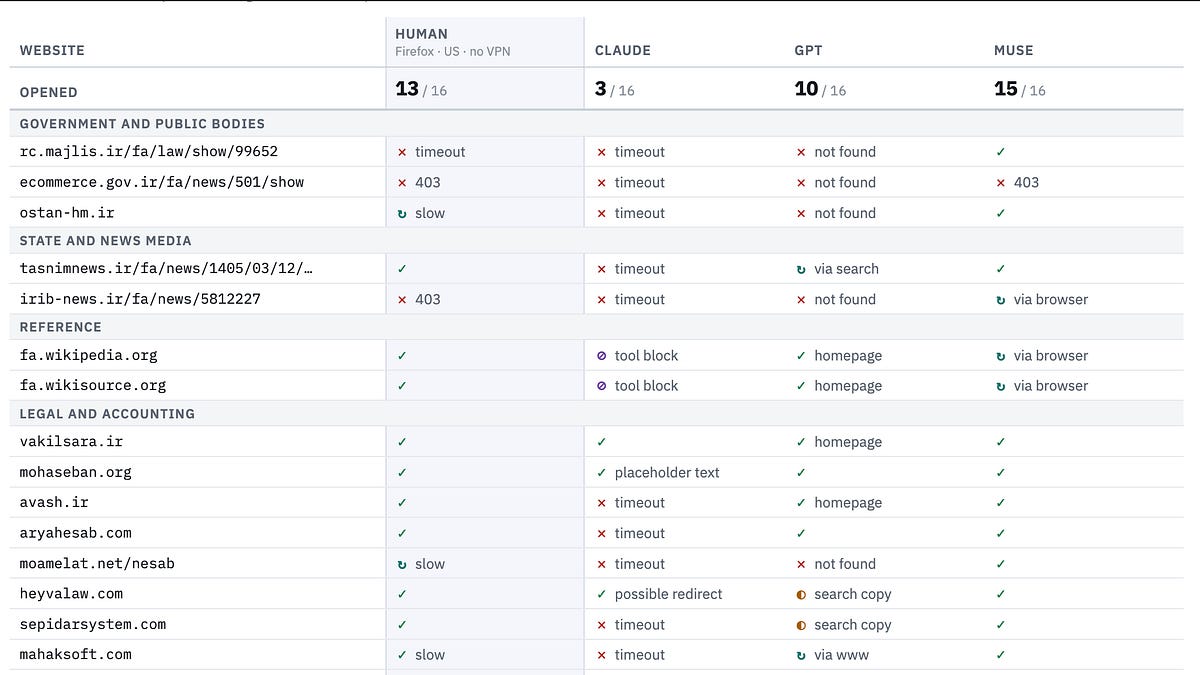
Speaking of workarounds, could agents’ web retrieval workarounds serve as an anti-censorship tool?
Looking through the agents’ trajectories, I noticed that they differed not only in which websites they could access, but also in how hard they tried when access failed. Some agents stopped after an initial failure, others tried alternate routes, different browsers, search-result snippets, cached or secondary sources, different fetch methods, and more.
So I ran a small follow-up test. I selected websites that the agents had accessed inconsistently during the original task and gave each agent a simple instruction: “Here is a list of websites. Look them up and write a one-paragraph summary of each.” The point was not to evaluate the quality of the summaries, but to observe what each agent did when direct access failed.
And Then the Question Flips
In this case, the agents were trying to reach websites that were difficult to access from their own technical environments. But what happens when the access barrier come from the user’s environment instead?
For people in countries where governments filter or block websites, could an LLM or AI agent become another layer of information access? Could it retrieve, summarize, take actions, or relay information from websites that the user cannot reach directly? And could agentic workarounds make censorship circumvention easier — or conversely reproduce new restrictions through a different technical stack? As Iranians who research information access and internet governance in Iran, my friend Farzaneh Badiei (a digital-rights lawyer) and I have been discussing how LLMs and AI agents might be used in censorship-circumvention contexts. I may explore this more in future installments of the Humane AI newsletter.
If you are interested in designing or conducting experiments on this topic, feel free to reach out at rpakzad@taraazresearch.org. And, last but not least:
Yes, Right-to-Left text: apparently we will get AGI before we get this right!
If you read Farsi, good luck making sense of the results on agents’ UIs! To my fellow right-to-left readers and writers (~700 million people): you have my commiseration every time you perform the gymnastics of trying to write an Instagram caption, fill in a spreadsheet, read governments’ “accessible” translated forms, or copy and paste text across platforms.
Disclaimer: I used ChatGPT and Claude for copyediting. I use Claude Code for table generation, and supervised data analysis.
[1](#footnote-anchor-1)

For resources on cybersecurity in AI agents, take a look at [OWASP GenAI Security Project](https://genai.owasp.org/).