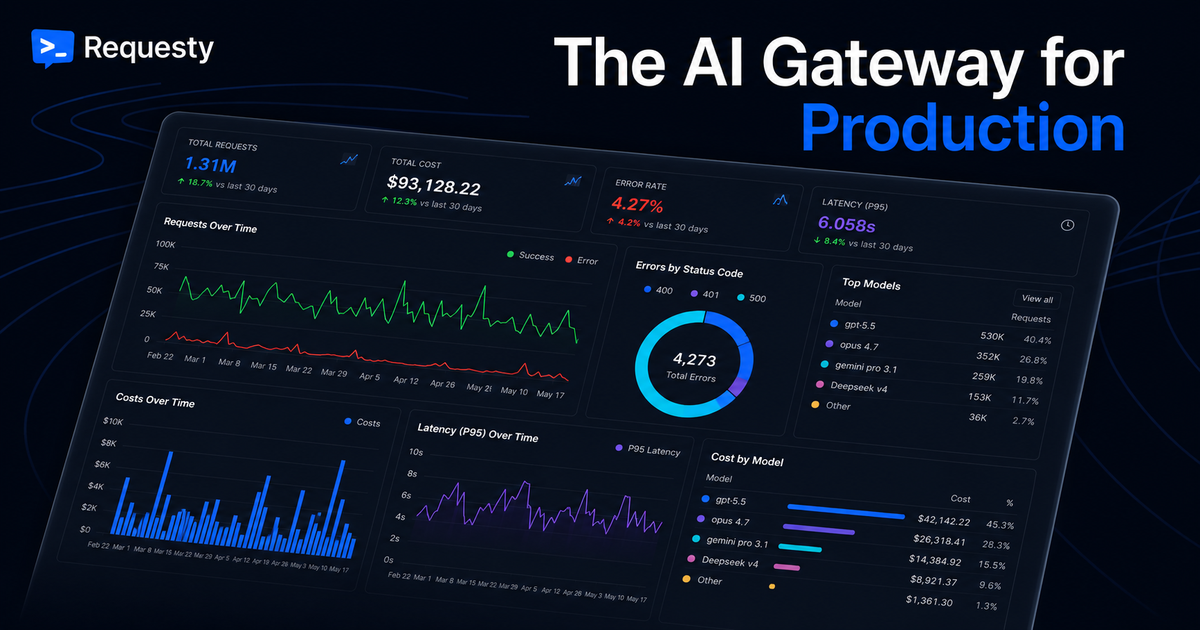
Access 600+ models through one API with routing and failover, spend limits, governance and full observability of every request.
Or email us at sales@requesty.ai
Analytics #
| Model | Requests | Tokens | Cost | Avg Latency |
|---|---|---|---|---|
| opus-5 | 42,180(34.2%) | 18.4M(38.0%) | $163.15 | 892ms |
| gpt-5.6-sol | 31,420(25.5%) | 12.8M(26.4%) | $114.70 | 445ms |
| gemini-3.7-flash | 24,100(19.6%) | 9.6M(19.8%) | $81.20 | 512ms |
| deepseek-v4-flash | 15,600(12.7%) | 5.2M(10.7%) | $52.90 | 380ms |
| glm-5.3 | 9,900(8.0%) | 2.4M(5.0%) | $34.00 | 310ms |
Your AI ops, at a glance #
Heatmaps, cost breakdowns, cache gauges across all your AI providers.
Across all providers and models. Peak: 8.2K/hr at 14:00 UTC.
Down from $1,422 last month thanks to auto caching and a cheaper model on two routes.
111.8K cache hits saved $978 this month. Auto caching enabled.
Auto-failover triggered 3 times. Zero downtime for your users.
from openai import OpenAIclient = OpenAI( base_url="https://router.requesty.ai/v1", api_key="your-requesty-key")response = client.chat.completions.create( model="anthropic/claude-opus-5", messages=[{"role": "user", "content": "Hello!"}])print(response.choices[0].message.content)
Integrate in #
a minute
Integrate Requesty in just 3 lines of code. No changes to your existing stack. Use the OpenAI SDK you already know.
Route every request #
Fail over, load balance or route by latency across 600+ models, and choose the region with the base URL. No retry logic in your app.
See where the money goes, then cap it #
Hard limits per key, user, team and organization, alerts before a limit hits or a key leaks, and every dollar attributed to the model, team and customer that spent it.
Define and enforce the rules #
Decide which models and regions each team can use, mask PII before it reaches a provider, hand auditors the evidence, and sync your teams from Entra.
Every request, traced and attributed #
Logs and traces for every call, sessions stitched back together, and usage tagged to the user, end customer or pull request it served.
See it in production #
Three different reasons to put a gateway in front of your models: scale, sovereignty, and growing across 13 providers on one integration.
Built to survive procurement #
The questions security and legal ask, answered before they ask them.
SOC 2 Type I, Type II under audit
We hold SOC 2 Type I and are in the audit period for Type II. Controls are in place and documented; status is on the trust page.
GDPR, DPA on request
An Article 28 DPA, signed on request at any spend, with sub-processors listed.
EU residency
Frankfurt, on AWS eu-central-1, via router.eu.requesty.ai.
Zero data retention, enforced
Require zero data retention models for the whole organization, and anything else is refused. 131 of the EU model endpoints qualify.
One number, and it sits on top of the model cost #
No per-seat pricing, no minimum spend. You pay for what your application spends, plus 5%.
Routing, failover, caching, spend limits, alerts and analytics on every plan. Guardrails are billed per token scanned. No seat fees.
Keep the pricing you have negotiated with each provider and still get routing, limits and observability across all of them.
SSO with Entra or Okta directory sync, groups, role scoped logs, guardrails included, a DPA on request and a named contact.
Questions & Answers #
An AI gateway between your app and 600+ models. Change your base URL to router.requesty.ai and get routing and failover, spend limits, governance and observability on every request.
One line of code: client = OpenAI(base_url='https://router.requesty.ai/v1', api_key='your-key'). Works with the OpenAI and Anthropic SDKs and any OpenAI-compatible framework.
Create a policy in the dashboard and call it as model="policy/name". A policy is a failover chain, a weighted load balance or a latency policy, and policies can be nested. Changing the chain needs no deploy.
Set monthly limits per API key, user, team and organization, with email or webhook alerts at the thresholds you choose. Auto caching cuts up to 90% on repeated context, and moving a route to a cheaper model is a string change.
Yes. Sign in with Microsoft Entra ID, Okta or any SAML or OIDC provider. With directory sync, Entra groups stay in sync with Requesty groups, and deprovisioning a user revokes their API keys.
Yes. Send requests to router.eu.requesty.ai in Frankfurt and an admin can restrict the organization to the EU gateway, so requests through any other endpoint are rejected. You can also require zero data retention models.
Yes. Pass a user_id in request metadata, or add headers such as X-Requesty-Customer and X-Requesty-Branch. Every X-Requesty header becomes a dimension you can filter and group by in analytics.
Yes. Point the tool at Requesty with your key and it gets every model, routing policies and spend tracking. Setup guides for each are in the docs.
5% markup on model costs, 0% with your own keys. Enterprise plans add SSO, directory sync and volume discounts.