#
            Rebuilding my voice assistant pipeline
            [https://blog.platypush.tech/article/Rewriting-my-voice-assistant-pipeline](https://blog.platypush.tech/article/Rewriting-my-voice-assistant-pipeline)
Swapping openwakeword for microwakeword and making voice detection smarter
I wrote an article a couple of months ago describing how I rebuilt my old voice assistant pipeline in Platypush.
And I wrote earlier articles describing my journey through self-hosted voice assistants - in 2024 (with Picovoice), in 2020 (diving into the legacy assistant.google integration, the now defunct assistant.alexa integration, the now defunct Snowboy integration, the now defunct DeepSpeech integration and Picovoice) and the original article in 2019 describing the Google Assistant integration.
For a couple of months I used the voice pipeline described in my latest article as my main driver, but after getting used to the robustness of commercial voice assistants I was unhappy with the high rates of false positives/negatives of my self-hosted pipeline, as well as its lack of robustness in detecting start/end of speech, especially in noisy environments and using cheap microphones.
After a bit of experimentation, I decided to swap and fine tune a few parts, and after a couple of days of trying the results are satisfying enough for me to write a short article about it.
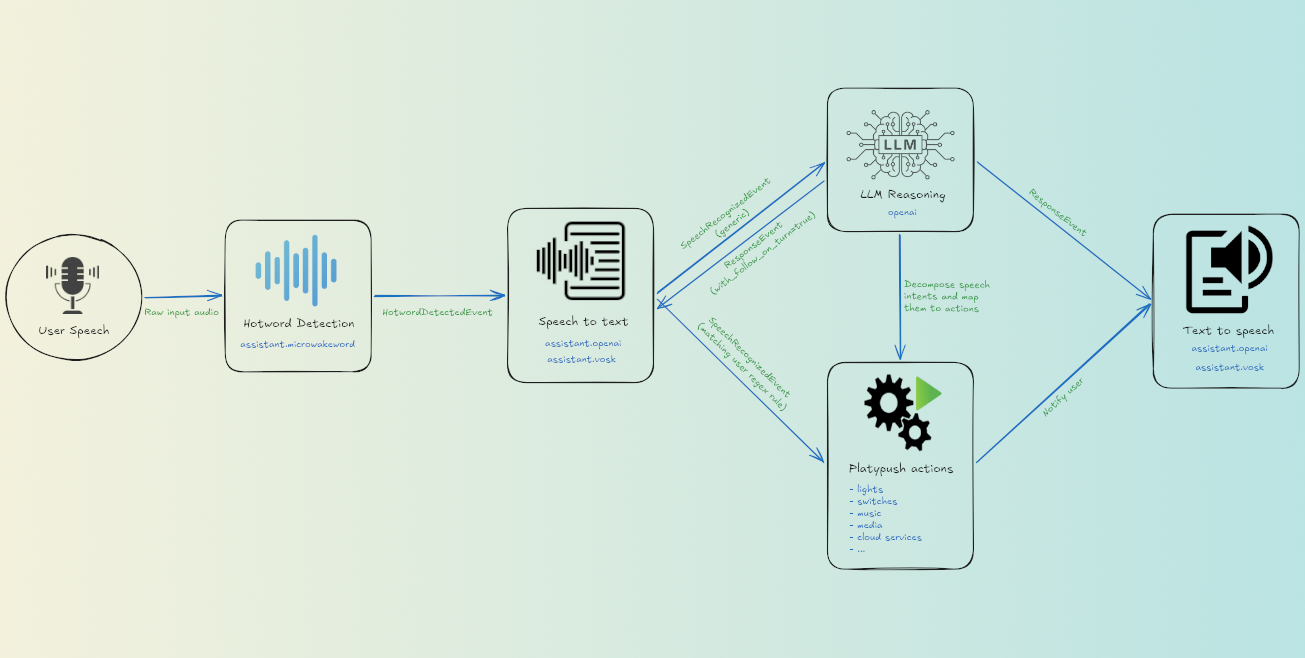
The resulting pipeline is:
Wake word detection: a new assistant.microwakeword plugin #
Until recently I used assistant.openwakeword, which wraps openWakeWord.
It works, but the project has been quiet for a while and all of its pre-trained models are v0.1 files from 2023, mostly trained on synthetic speech.
In practice I was getting both false positives (the hotword triggering on background noise) and false negatives (the hotword not detected unless I was close to the microphone).
I added a new plugin, assistant.microwakeword, on top of microWakeWord through the pymicro-wakeword Python bindings.
microWakeWord is the engine used by ESPHome and Home Assistant Voice, its models are actively maintained, and the built-in models (okay_nabu, hey_jarvis, hey_mycroft, alexa) ship with the package — no download required.
The current official models are provided under the ESPHome micro-wake-word-models repository.
Custom models are supported too: drop a microWakeWord JSON manifest (with its .tflite model) in the plugin's models directory and reference it by name.
The plugin exposes the same API as assistant.openwakeword (same models, detection_threshold, frame_duration, patience_frames, input_device, input_volume parameters, same list_models action, same HotwordDetectedEvent), so switching is a matter of just changing the configuration to point to the new plugin:
assistant.microwakeword:
  models:
    - alexa
A few design notes:
- Without an explicit
detection_threshold, each model uses theprobability_cutofffrom its own manifest (0.9 foralexa), which is the value the model was validated against. - Models already smooth their output over a sliding window, so unlike openwakeword,
patience_framesdefaults to 0 here. - The audio thread never touches the TFLite models directly: it queues frames (and a reset marker) to the main thread, because
MicroWakeWord.reset()reloads the interpreter and isn't safe to call concurrently. - Like
assistant.openwakeword, the plugin releases the audio device when another assistant plugin starts a conversation, and re-acquires it when the conversation ends.
Speech-to-text: assistant.openai, with a much better ear #
assistant.openai records audio when a conversation starts and transcribes it through Whisper.
The tricky part has always been end-of-speech detection: knowing when the user has finished talking. The previous implementation used a per-frame boolean from WebRTC VAD, and any single frame classified as speech would reset the silence timer. With even a bit of background noise, phrases would only end when the maximum conversation duration was hit.
The audio preprocessing layer (AudioPreprocessor, shared by the STT integrations) has been reworked:
- Silero VAD as the primary backend (through
onnxruntime, noPyTorch required), with WebRTC VAD and a plain RMS-based detector as fallbacks. To get an idea of Silero VAD's performance compared against other solutions for speech activity detection, take a look at the insightful articleOne voice detector to rule them all . The Silero model is downloaded on first use into the Platypush workdir and checksum-verified:
assistant.openai:
  vad_backend: auto
Hysteresis + sliding window : a frame becomes speech above the VAD threshold and stays speech until its score drops by a margin, and the per-frame decisions are smoothed by majority vote over a 0.5s window. A single noise burst can no longer keep a conversation alive. #
Adaptive noise floor : the background noise level is tracked over time, and frames that aren't louder thannoise_floor_factor (default 2.0, ~6 dB) times the floor are never considered as speech.
On a synthetic benchmark (Piper-generated phrases mixed with babble and burst noise), the old settings kept conversations open for 6–10 seconds after the speech had ended; the new pipeline ends them 1.0–1.6 seconds after the last word, which is the configured conversation_end_timeout plus the smoothing lag.
Since the changes on Platypush have been performed directly in the AudioPreprocessor also used by other native speech-to-text engines, other speech-to-text plugins also benefit from them - e.g. if you use assistant.vosk for full on-device detection.
Responses and context: the openai plugin #
The transcribed phrase is processed by the openai plugin, which handles both the API key and the conversation context. By default the assistant renders the response through the configured tts_plugin; if the response ends with a question mark, the conversation continues with a follow-up.
Custom hooks can intercept phrases before the default response kicks in — for example, to handle home automation commands locally without an LLM round-trip:
from platypush import run, when
from platypush.message.event.assistant import SpeechRecognizedEvent

@when(SpeechRecognizedEvent, phrase='play (the)? music')
def play_music():
    run('music.mpd.play')
And the hotword event is wired to the conversation start with a similar hook:
from platypush import run, when
from platypush.message.event.assistant import HotwordDetectedEvent

@when(HotwordDetectedEvent)
def on_hotword(**_):
    run('assistant.openai.start_conversation')
Text-to-speech: tts.openai #
Responses are rendered by tts.openai, with volume and voice configurable. In my tests however tts.piper also yielded good results, and it runs entirely locally. In my tests on a RaspberryPi 5 however it added ~3-4s of latency to process the response to audio compared to tts.openai.
Since the TTS output goes to the speakers and the wake word detector listens on the microphone, the assistant plugins hotword detection while a conversation is active — otherwise the assistant would hear itself.
The full configuration #
openai:
  api_key: YOUR_API_KEY

assistant.microwakeword:
  models:
    - alexa

assistant.openai:
  tts_plugin: tts.openai
  conversation_start_sound: ~/sounds/wake_word_detected.wav
  input_volume: 100


tts.openai:
  output_volume: 80.0
What changed on the code side #
- New
assistant.microwakewordplugin : microWakeWord hotword detection throughpymicro-wakeword, same API asassistant.openwakeword, built-in models bundled with the package, custom models via JSON manifests. assistant.openwakewordfixes : frames are now 80ms (1280 samples, the size openWakeWord recommends) instead of 500ms — longer chunks only return the highest score over their sub-frames and can miss hotwords — plus apatience_framesparameter (consecutive frames above threshold) and an explicitdetection_thresholdparameter (default 0.5).- Shared
AudioPreprocessorrework : Silero/WebRTC/energy VAD backends withvad_backend: autoselection, threshold hysteresis, sliding-window majority vote, and an adaptive noise floor. Used by bothassistant.openaiandassistant.vosk. - New Silero VAD wrapper : ONNX inference through
onnxruntime, recurrent state carried across frames, checksum-verified model download into the workdir.
Caveats #
The microphone on my RPi doesn't support 16 kHz natively, so audio is captured at 44.1 kHz and software-resampled — it works, but if detection feels sluggish software resampling is usually the first suspect.
The VAD and threshold defaults were tuned on synthetic audio plus a couple of my audio recordings.
Different rooms, microphones and acoustics may yield different results. You may want to adjust detection_threshold on the wake word plugin and noise_floor_factor on the STT plugins if you don't feel satisfied with your mileage.
Reactions #
How to interact with this page #
Webmentions
      To interact via [Webmentions](https://indieweb.org/Webmention),
      send an activity that references [this URL](https://blog.platypush.tech/article/Rewriting-my-voice-assistant-pipeline) from a platform that supports Webmentions,
      such as [Lemmy](https://joinlemmy.org/),
      [WordPress with Webmention plugins](https://wordpress.org/plugins/webmention/),
      or any [IndieWeb-compatible site](https://indieweb.org/Webmention#Publishing_Software).
ActivityPub
-
Follow [@blog@platypush.tech](https://blog.platypush.tech/@blog) on your ActivityPub platform (e.g. Mastodon, Misskey, Pleroma, Lemmy). -
Mention [@blog@platypush.tech](https://blog.platypush.tech/@blog) in a post to feature on the[Guestbook](https://blog.platypush.tech/guestbook) . -
Search for [this URL](https://blog.platypush.tech/article/Rewriting-my-voice-assistant-pipeline) on your instance to find and interact with the post. - Like, boost, quote, or reply to the post to feature your activity here.
It's 2026. You deserve a good local-first or local-only voice assistant on your #RaspberryPi
blog.platypush.tech/article/Rewriting-my-voice-assistant-pipeline