Read the RGC preprint (PDF) for the full method and experiments, including comparisons with LoRA and dense AdamW and the analysis behind our memory predictions.
Reinforcement learning is how language models learn to reason better, but updating every weight is expensive: dense AdamW keeps FP32 weights, a gradient and two optimizer moments. Randomized Gradient Compression (RGC) trains the original attention and MLP projection weights from a compressed gradient, keeps those weights in BF16, and stores no optimizer state at all.
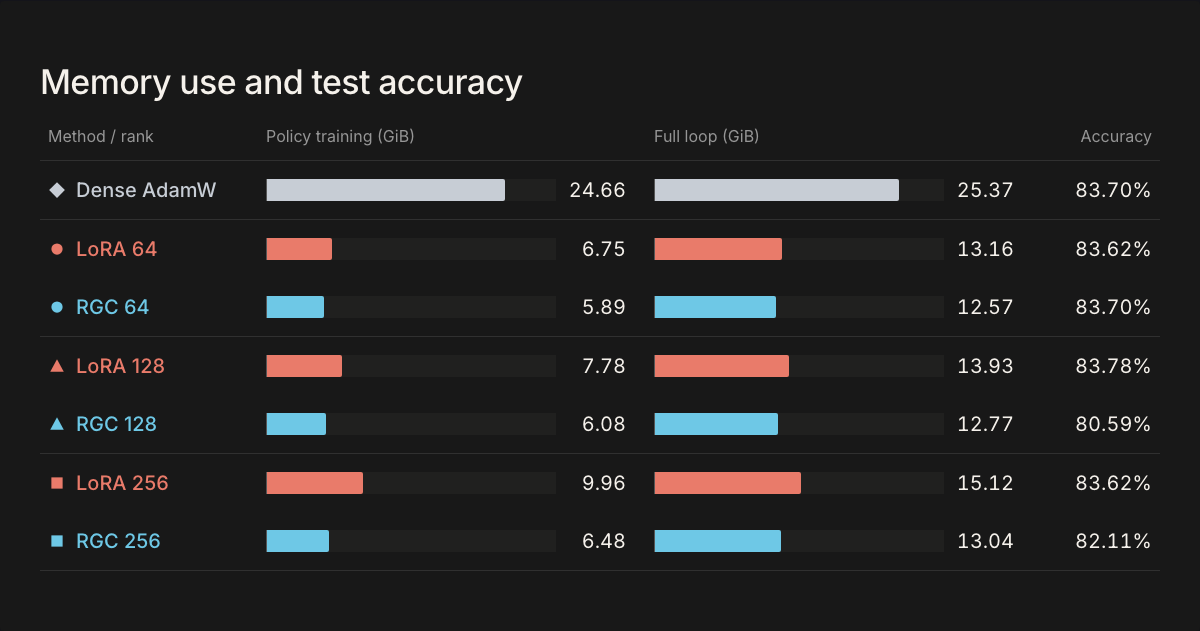
On Qwen3-1.7B-Base trained with GRPO on GSM8K, RGC uses 13-35% less policy-training memory than LoRA across ranks 64, 128 and 256, with lower whole-loop memory at every rank. At rank 64, it matches dense AdamW’s 83.70% test accuracy using 5.89 GiB instead of 24.66 GiB, a 76% reduction.
How it works #
For a linear layer with input X and output derivative D, the weight gradient is D.T X. RGC never forms it. Each selected layer holds a random projection P with r columns and accumulates a narrow matrix instead:
C += D.T (X P)
The layer saves X P, not X, for backpropagation. After the 64 responses of a training step, RGC rebuilds the update H = C P.T 128 rows at a time and applies it to the original weights, so no dense gradient or dense update is ever held in memory. A new random projection is drawn after every update.1
Normalized SGD moves each weight matrix by the same fraction of its own norm, with no momentum:
W <- W - tau * norm(W) * H / norm(H)
The weights stay in BF16 without an FP32 copy. Ordinary rounding would erase most updates this small, so RGC uses stochastic rounding: a weight that should move 1% of the gap between adjacent BF16 values moves the whole gap 1% of the time. The stored update is correct on average, without the memory cost of FP32 weights.
We calibrated the step size to match a first AdamW step at learning rate 1e-6 on the untrained model, then tried that step and three times it on the 1.7B model.
Results #
We trained each configuration for 200 GRPO steps with one training seed and selected the step size on development accuracy before any test evaluation. Training peak covers the policy update; whole-loop peak includes generating responses. Both columns report peak allocated GPU memory.
| Method | Test acc. | Training peak | Whole-loop peak |
|---|---|---|---|
| Untrained base | 64.90% | - | - |
| Dense AdamW | 83.70% | 24.66 GiB | 25.37 GiB |
| LoRA, rank 64 | 83.62% | 6.75 GiB | 13.16 GiB |
| LoRA, rank 128 | 83.78% | 7.78 GiB | 13.93 GiB |
| LoRA, rank 256 | 83.62% | 9.96 GiB | 15.12 GiB |
| RGC, rank 64 | 83.70% | 5.89 GiB | 12.57 GiB |
| RGC, rank 128 | 80.59% | 6.08 GiB | 12.77 GiB |
| RGC, rank 256 | 82.11% | 6.48 GiB | 13.04 GiB |
RGC’s training peak stays between 5.89 and 6.48 GiB as rank increases from 64 to 256, while LoRA’s rises from 6.75 to 9.96 GiB. At rank 64, RGC answers as many test questions correctly as dense AdamW and one more than LoRA.2
On Qwen3-8B-Base, RGC reaches 92.34% accuracy with an 18.45 GiB training peak and 27.95 GiB over the full loop. LoRA reaches 93.78%, using 20.57 GiB and 29.24 GiB respectively. Dense AdamW runs out of memory during its first optimizer step on the same 96 GB GPU.
Memory you can predict #
Above the BF16 model, RGC keeps only its compressed state, about a fifth the size of LoRA’s adapters and Adam state at the same rank. That puts RGC below LoRA at every rank, with savings that grow as rank increases.
Before training, we predicted savings of 0.84, 1.68 and 3.36 GiB over LoRA at ranks 64, 128 and 256; we measured 0.86, 1.69 and 3.48 GiB. On the 8B model, we predicted 2.11 GiB and measured 2.12 GiB. Every prediction was within 0.12 GiB of the measured gap.
What’s next #
We’re building RGC into Actuator and plan to release it soon, so you can use it in your own RL training runs.
The full method, calibration, grid, paired comparisons and every candidate’s development trajectory are in the paper (PDF).
P is a random orthonormal frame, obtained by QR factorization of a Gaussian matrix with the standard sign correction and scaled bysqrt(input width / rank) . GoLore samples its low-rank gradient projections from the same distribution, unscaled. In exact arithmetic, RGC’s scale makesH an unbiased gradient estimate and attains the smallest worst-case error among unbiased reconstructions of the formG P P.T . The paper gives the derivation.↩
2.
Across 1,319 test questions, RGC differs from same-rank LoRA by +0.08, -3.18 and -1.52 percentage points at ranks 64, 128 and 256, and by -1.44 points at 8B. The paired 95% intervals exclude zero for 1.7B rank 128 and 8B. These intervals hold the selected checkpoints fixed; they do not measure variation across training seeds. ↩