I bought a 1966 Ford Thunderbird about a year ago, and I do most of the work on it myself. While working on the car, I often gave AI tools the manuals and parts catalogs and asked questions. They frequently had trouble understanding the diagrams.
I built this benchmark to find out what they could and couldn’t do, and to track whether they get better over time.
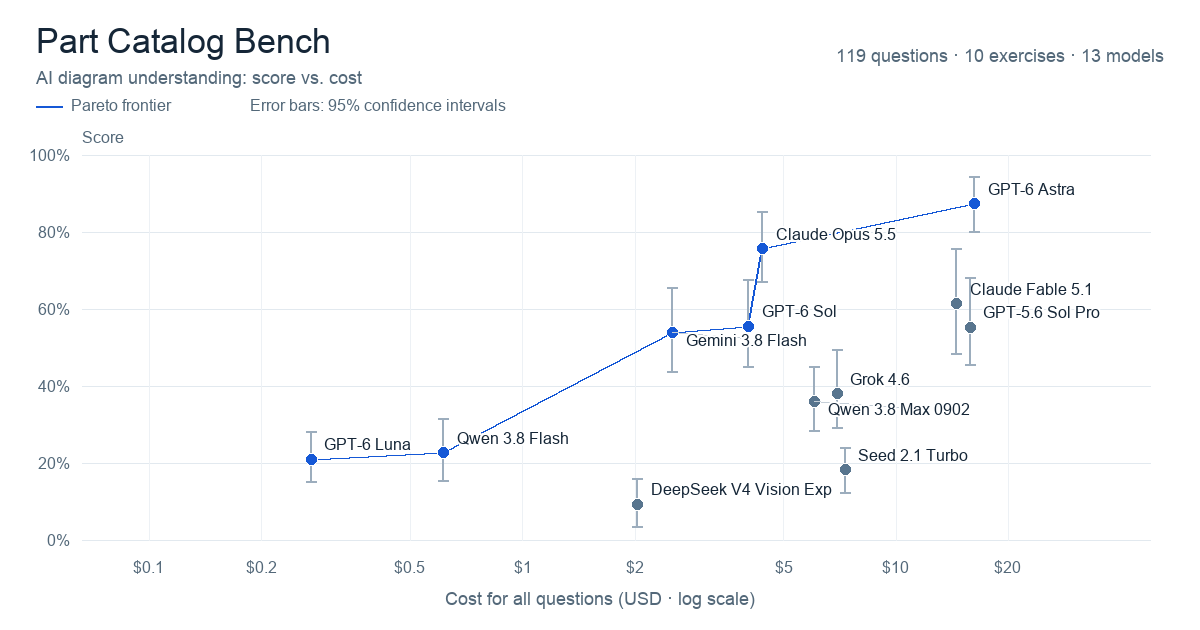
GPT-6 Astra has the highest score at 87.4%, followed by Claude Opus 5.5 at 75.6% and Claude Fable 5.1 at 61.3%. Opus costs about $4.39 for the full set of questions, compared with $16.22 for Astra.
Updated Sept 23, 2026
Me and my son in my 1966 Ford Thunderbird, the car that inspired me to create this benchmark. I used ChatGPT to remove a car and house in the background. The removal of my eyes was unsolicited.
Observed Pareto frontier 95% confidence intervalHigher and further left is better
Click a model to jump to its breakdown below.
Updates
September 23, 2026 — Three new models
I added Claude Opus 5.5, GPT-6 Sol, and GPT-6 Luna. They scored 75.6%, 55.5%, and 21.0%, respectively, on the same 119 questions with the same run settings. All three returned an answer to every question.
Opus 5.5 moves into second place behind GPT-6 Astra. The table, chart, downloads, and example answer pages now include all 13 models.
September 8, 2026 — First release
I published the benchmark with 119 questions across 10 exercises, and results for these ten models:
This is the front suspension diagram for the 1966–67 Ford Falcon and Ford Fairlane, with variations for the 1967 Ford Mustang. One exercise contains several questions about the same page. Here are three from this exercise, exactly as written in the benchmark.
Ford Car Master Parts and Accessories Catalog, illustration 30–18. Reproduced from the Forel edition. Click the image to open it at full size.
Easy · Part connections
Bolt 380571-S is used to attach part 3468 to what part?
Part 5495 passes through a series of other parts. List all the part numbers for these parts, in order from top to bottom as installed on the vehicle. Do not include 5495 itself.
Each model gets the image and one question at a time, along with instructions for reading the catalog and formatting its answer. It doesn’t see the other questions or their answers.
All the exercises use diagrams from the Ford 1960–68 Car Master Parts and Accessories Catalog, a 5,445-page reference Ford dealerships used to look up parts before computerized parts systems. I wrote the questions and answers myself.
To run the benchmark yourself, you’ll need your own PDF copy of the catalog. You can purchase it from Forel (product D10063).
What the model sees
A question, the relevant page images, and instructions on how to use the catalog. Images are rendered at 300 DPI, with any crops or highlights specified for that question. The PDF’s OCR text isn’t sent. None of the current questions requires looking something up in the text catalog.
Scoring
Every question has the same weight, regardless of difficulty. Part numbers, lists, and other structured answers are checked against the answer key. Free-text answers are graded against a rubric and can earn partial credit. Partial credit for incomplete lists is reported separately from the main score.
Run settings
These models were accessed through OpenRouter.
run settings…
Each score uses one answer per question. Some answers are reused from earlier runs when the question, image, and settings match. The assembly date is when those results were combined, not necessarily when every answer was generated.
Error bars
Several questions share each diagram, so the confidence intervals resample whole exercises rather than treating every question as independent. With only ten exercises, the intervals are still wide. They don’t capture how answers might change on a second run, or errors made by the grader.
Failed answers
A model gets zero if it runs out of output tokens or returns no final answer. Service errors can be retried. Models with unfinished runs or unresolved grading errors aren’t listed yet. A service failure doesn’t tell us how the model would have answered.
Cost and time
Cost is what the provider reported for the saved answers, including reused ones. Grading costs are listed separately. Paid retries that weren’t recorded may be missing, so these figures won’t necessarily match the bill. Response times also depend on provider load and how much reasoning the model does.