OpenAI's Decisions API brings a big-lab competitor to Jev. How do their contracts, limits, accuracy, latency, and costs compare on BANKING77?
Jev: AI Decisions as a Typed Function Call 2. 2. Jev at the Branches: The State Machine Is the Agent 3. 3. Jev: Attack of the Classifiers 4. 4. DSPy ♥ Jev: Typed Decisions, One Program, and ReAnchor 5. 5. OpenAI Decisions API: How Does Jev's Big-Lab Competitor Fare?
OpenAI’s new Decisions API, powered by gpt-6-luna, gives Jev a big-lab competitor. Instead of generating a text response, it answers bounded questions with choices, probabilities, and scores.
If you’ve used Jev, this will look familiar: give it context, ask a bounded question, and get probabilities back. The APIs work similarly; we don’t know whether the models behind them do.
In Attack of the Classifiers, I compared Jev with local classifiers and an LLM. Here I use the same BANKING77 sample to see how Decisions fares, both with just intent definitions and with two training examples per intent.
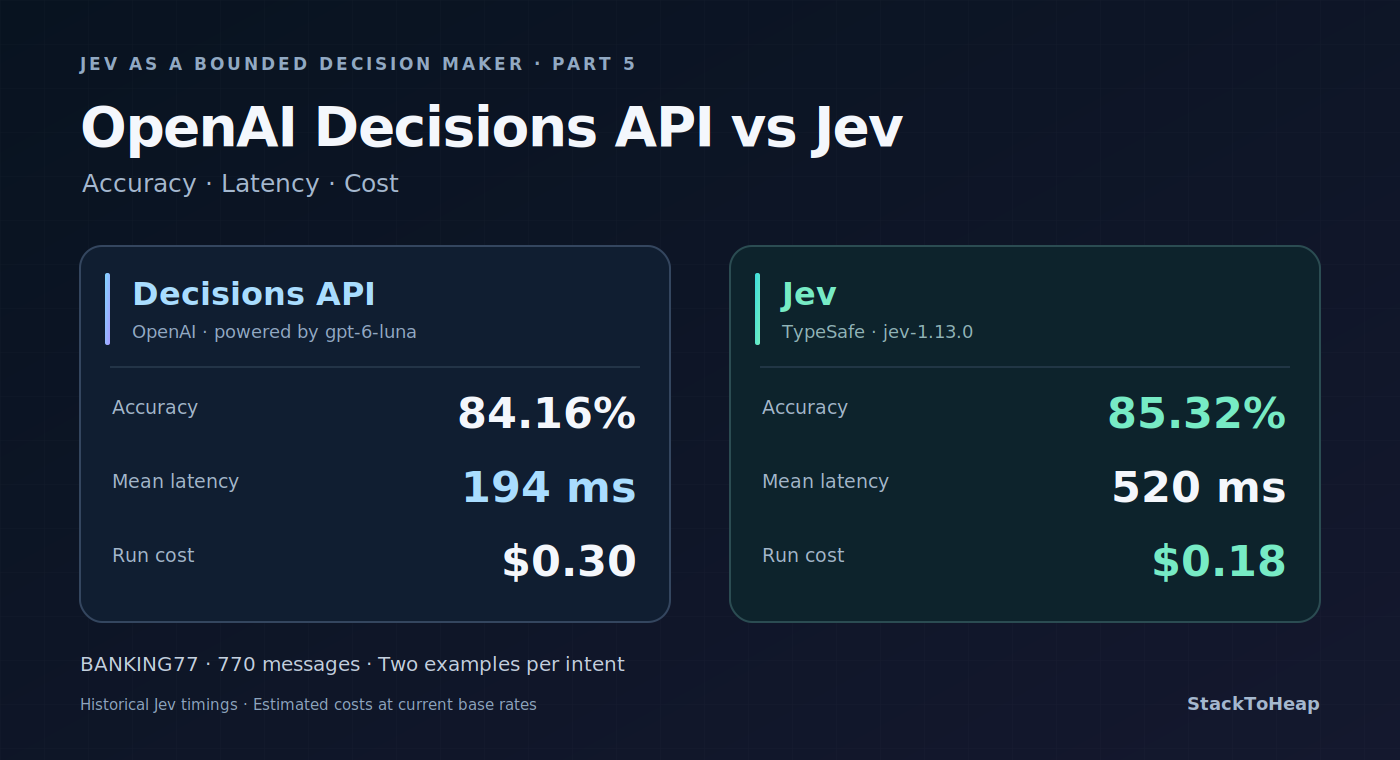
The short version: examples lifted Decisions from 78.96% to 84.16% accuracy, close to Jev’s 85.32% with the same examples. With examples, Decisions averaged 194 ms per request versus Jev’s 520 ms, but the run cost about $0.30 versus $0.18. Decisions also accepts much larger context, but refused a few classification requests.
As of October 8, 2026, Decisions is in public beta, with gpt-6-luna as its documented supported model. OpenAI says it returns typed answers about 10× faster than its Responses API.
The question types line up closely with Jev’s:
| Judgment | OpenAI Decisions | Jev |
|---|---|---|
| Does a condition hold? | predicate |
noul |
| Which option fits? | choice |
choice |
| Where does it sit on an ordered rubric? | score |
score |
For a single intent, use a choice. For multiple independent tags, use predicates or Nouls: a choice makes the options compete for probability mass.
Here is a small Decisions request to POST /v1/decisions:
{
  "model": "gpt-6-luna",
  "input": "The ATM charged me an extra fee.",
  "questions": [{
    "type": "choice",
    "name": "intent",
    "instructions": "Which intent best describes this message?",
    "choices": [
      {"value": "cash_withdrawal_charge", "description": "An extra fee for withdrawing cash."},
      {"value": "card_payment_fee_charged", "description": "An extra fee for a card purchase."}
    ]
  }]
}
The equivalent Jev request to POST /v1/systemone looks like this:
{
  "model": "jev-1.13.0",
  "state": "The ATM charged me an extra fee.",
  "questions": {
    "intent": {
      "type": "choice",
      "instructions": "Which intent best describes this message?",
      "criteria": {
        "cash_withdrawal_charge": "An extra fee for withdrawing cash.",
        "card_payment_fee_charged": "An extra fee for a card purchase."
      }
    }
  }
}
Decisions returns an answers array with named entries; Jev returns answers.intent. Both return the selected choice and probabilities, but Decisions uses an array of {value, probability} entries while Jev uses a map. Switching providers needs a small adapter, not just a new endpoint URL.
Two other differences matter:
- Evidence: Decisions accepts text and inline base64 images. Jev 1.13 is text-only, including text-valued JSON objects and arrays.
- Guidance: Jev supports structured instructions and criteria, such as
what,not_for, andexamples. Decisions uses instruction and description strings; I appended the training examples to each choice description.
Both support several questions over shared evidence. This benchmark used one customer message and one choice question per request.
Decisions can return HTTP 200 without answering the question:
{"type": "refusal", "name": "intent"}
It refused two requests with definitions only and five with examples. The original two were “Why do you need to know so much about me” and “what is my card PIN”. The example-guided run also refused queries about logging in, finding a card PIN, and buying cryptocurrency.
No reasons or probabilities were returned. These were requests to classify the messages, not answer them, so even a bounded classification task needs refusal handling.
Options and context #
Both APIs have a 255-option limit per choice question. Decisions accepted 255 options; 256 returned HTTP 400 with array_above_max_length, explicitly stating a maximum of 255.
Decisions may also expose Luna’s normal input budget. OpenAI documents a 1.05M-token context window with a 922K-token input limit. Expanded example payloads worked at 692,197 input tokens; roughly 1.08M triggered an explicit token-limit rejection. Requests around 700K–900K timed out or returned service errors, so the full 922K budget remains unconfirmed.
That is still substantially more context than Jev 1.13’s documented 64K total / 32K state-plus-question budgets. The large payloads used repeated training examples to test capacity, not accuracy.
I used the same 770 BANKING77 test rows as the earlier comparison: the first ten official test examples for each of 77 banking intents. Both APIs received the same definitions. The example-guided runs added the same two training examples per intent, 154 total, with no test examples included.
Each Decisions run made 770 fresh requests. The Jev figures come from the earlier matched runs, using pinned jev-1.13.0. Refusals count as incorrect in the main results.
| API | Guidance | Accuracy | Macro-F1 |
|---|---|---|---|
| Decisions | Definitions only | 78.96% | 78.17% |
| Jev | Definitions only | 81.17% | 80.37% |
| Decisions | Two examples per intent | 84.16% | 83.96% |
| Jev | Two examples per intent | 85.32% | 84.99% |
Examples improved Decisions by 5.19 percentage points, from 608 to 648 correct classifications. They fixed 63 mistakes but introduced 23 new ones: a net gain of 40. Jev improved too, leaving a smaller gap—** nine correct predictions**—between the example-guided runs.
Excluding refusals, Decisions reached 79.17% with definitions and 84.71% with examples. That changes the denominator, not the number of correct classifications.
For perspective, the trained MiniLM classifier from the earlier post scored 89.87% on this sample. Neither hosted API displaced it on this fixed taxonomy.
How useful are the probabilities? #
I compared native selected-label probabilities, not the separate confidence field, using the same ten-bin calibration analysis as the earlier Jev study. Refusals are excluded because they have no probabilities.
| API and guidance | Calibration error (ECE) ↓ | Brier score ↓ |
|---|---|---|
| Decisions, definitions | 4.35% | 0.3163 |
| Jev, definitions | 9.33% | 0.3078 |
| Decisions, examples | 4.63% | 0.2472 |
| Jev, examples | 6.50% | 0.2206 |
Decisions had lower binned calibration error in both comparisons. Jev had better Brier scores, which assess the full probability distribution. Adding examples improved both APIs’ Brier scores, but did not improve Decisions’ ECE. Better accuracy and better calibration are not the same thing.
The current base input rates are $0.10 per million tokens for Decisions and $0.042 for Jev, with no output charge for these decision calls. Using each run’s reported input usage:
| API and guidance | Mean latency | Estimated run cost |
|---|---|---|
| Decisions, definitions | 143.88 ms | $0.1057 |
| Jev, definitions | 298.39 ms | $0.0690 |
| Decisions, examples | 194.41 ms | $0.3024 |
| Jev, examples | 520.03 ms | $0.1831 |
Two examples per intent increased Decisions’ mean latency by 35% and its token bill by 2.86×. Its p95 latency rose from 229.67 ms to 287.42 ms.
Decisions was about 2.1× faster without examples and 2.7× faster with them than the historical Jev runs. These hosted measurements were taken on different dates, not under identical service load. Decisions made 770 live calls per run; each historical Jev run reused one duplicate response and made 769.
The cost estimates use today’s base rates, excluding regional premiums. The benchmark requests were short enough to avoid Decisions’ long-context multiplier. Jev was cheaper in both comparisons despite reporting more input tokens.
Decisions is a credible alternative to Jev: a similar decision interface, image support, substantially larger context, and lower latency in these runs. Two examples per intent brought its accuracy close to Jev’s.
Jev retained the accuracy and cost advantage on BANKING77, along with a more flexible structured-guidance contract. Decisions had lower binned calibration error, but its refusals are another case application code must handle.
For this workload, the trade-off is straightforward: Decisions for speed and larger inputs; Jev for cheaper, slightly more accurate classification. A few relevant examples helped both more than switching between their definition-only runs.