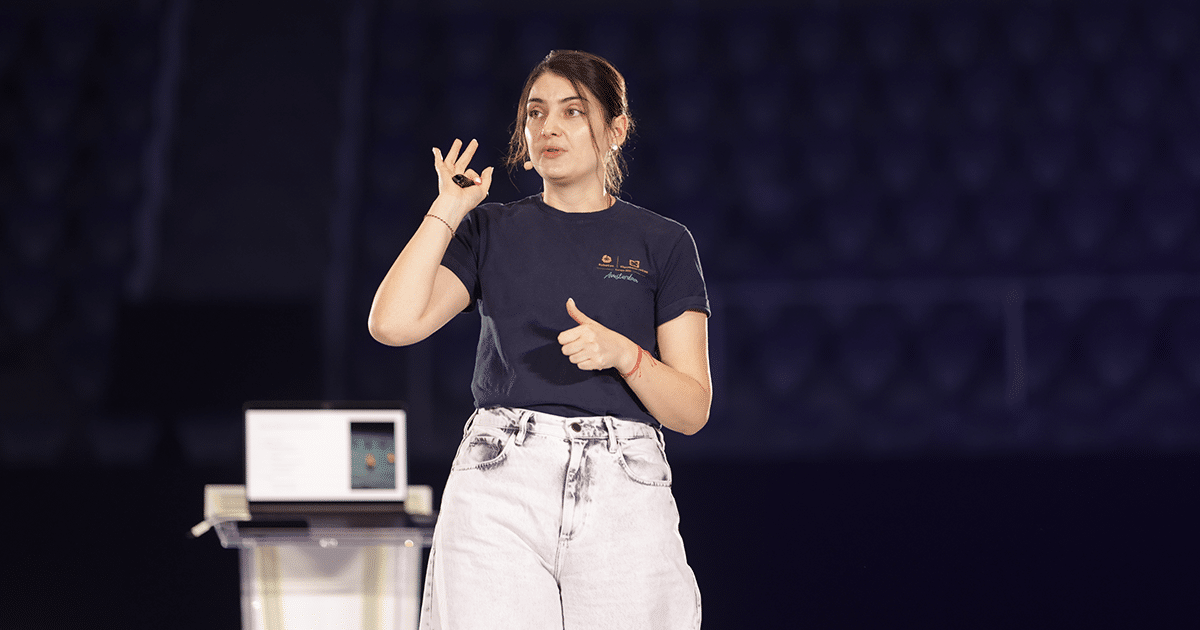
Yesterday at Infobip Shift 2026, I listened to Apple Principal Engineer and CNCF Technical Oversight Committee member Katie Gamanji talk about the state of cloud native and its slow turn towards AI.
She said cloud native spent years becoming stable and unexciting, and AI teams now need that stability more than new tools. The big question is whether the people around that infrastructure can move as fast as the platform itself.
For teams already using Kubernetes in production, the next change is very concrete, Katie said: Dynamic Resource Allocation, or DRA, reached general availability in Kubernetes 1.34, adding a native way to request GPU and TPU capacity for AI workloads.
Kubernetes is now officially boring #
Katie started with a number that captures how far Kubernetes has come: “98% of organizations in the CNCF’s annual report said they had adopted cloud native technologies.” After a decade of development, Kubernetes has become mainstream:
Kubernetes is now described as being boring, and I think this is a wonderful achievement.
The problem appears when AI workloads enter that mature infrastructure. According to the figures Katie presented, 66% of organizations are already deploying AI workloads on Kubernetes. But only 7% are doing it daily, while 47% deploy them occasionally. Of the organizations using Kubernetes for AI, 23% have fully adopted the Kubernetes stack and 43% have partially adopted it.
That 67 to 7 gap points to one likeliest cause. The talk did not name the cause directly, but the pattern Katie described points to operational immaturity as the likeliest one:
Teams fine-tune an existing model rather than build one, deploy it once to prove it works, and lack the automated retraining pipelines that would treat the model as a dynamic component.
The 7% deploying daily, she noted, “most likely implemented an automated retraining pipeline that treats the model as a dynamic component rather than a static element.” Running an AI workload is not as simple as putting another application into a container. Teams need model artifacts, rollback strategies, and training pipelines. Kubernetes is being positioned as the shared platform, though whether teams adopt it that way is another question.
DRA and AI Conformance are making Kubernetes the AI platform #
Katie compared this to DevOps: Kubernetes once brought developers and operations together, and now it could do the same for infrastructure teams and data scientists. But the analogy has limits – DevOps took years to work, and it is still not fully settled everywhere.
Data scientists, for their part, rarely want to operate Kubernetes; they want a model served. Still, a platform that can run both traditional workloads and training or inference jobs reduces the need for separate AI infrastructure.
Kubernetes is also adapting for this: DRA in 1.34 gives teams a more reliable way to allocate accelerators, which matters most for teams deploying daily.
The AI Conformance Working Group defines what a platform must support to run AI workloads reliably, with portability as the goal as Katie said:
If you have two conformant platforms, it’s going to be easy to lift and shift one product to the next platform. Other initiatives target batch workloads, inference performance, and AI integration, and an Agent Sandbox effort is designing stateful, isolated runtimes for AI agents. The Serving Working Group completed its milestones and archived itself in February, continuing as a SIG on inference performance.
The list is still changing quickly. Katie expects much of this landscape to look different within six months to a year.
The cloud native playbook AI can borrow #
Katie divided the emerging open source AI ecosystem into three areas: training, inference, and agents. Training turns data into a model. Inference serves it. Agents connect it to the outside world.
For platform leads, maturity matters. Training is led by the PyTorch Foundation, inference has many options, and agents are still young under the Agentic AI Foundation. Cloud native experience can help AI tools mature faster. Security, observability, and identity were already solved in cloud native, and the CNCF project pipeline shows that kind of progress at scale.e.
It also prunes: 28 archived projects. For anyone choosing a stack, the archive list is a practical filter, and Katie argued archival is a healthy sign, letting maintainers redirect energy toward projects that earn adoption.
Teams that engage now will shape the patterns everyone else follows #
For Katie, the next phase of cloud native is about whether the people building and maintaining the ecosystem can keep pace. She pointed out that contributing also means production feedback, feature requests, documentation, and white papers all shape projects. But in the end Katie’s talk left the hard questions unanswered, but the data shows why:
98% of organizations trust Kubernetes with their infrastructure, two thirds have tried running AI on it, and almost nobody operates it continuously.
The specific bottlenecks, daily operational maturity, DRA adoption, and the conformance baseline, are still being defined, which means teams deploying AI on Kubernetes today are writing the patterns everyone else will copy:
All of the working groups’ meeting notes, invites, and repositories are public on GitHub. The teams that engage now, before the patterns harden, will not have to retrofit someone else’s choices in two years.