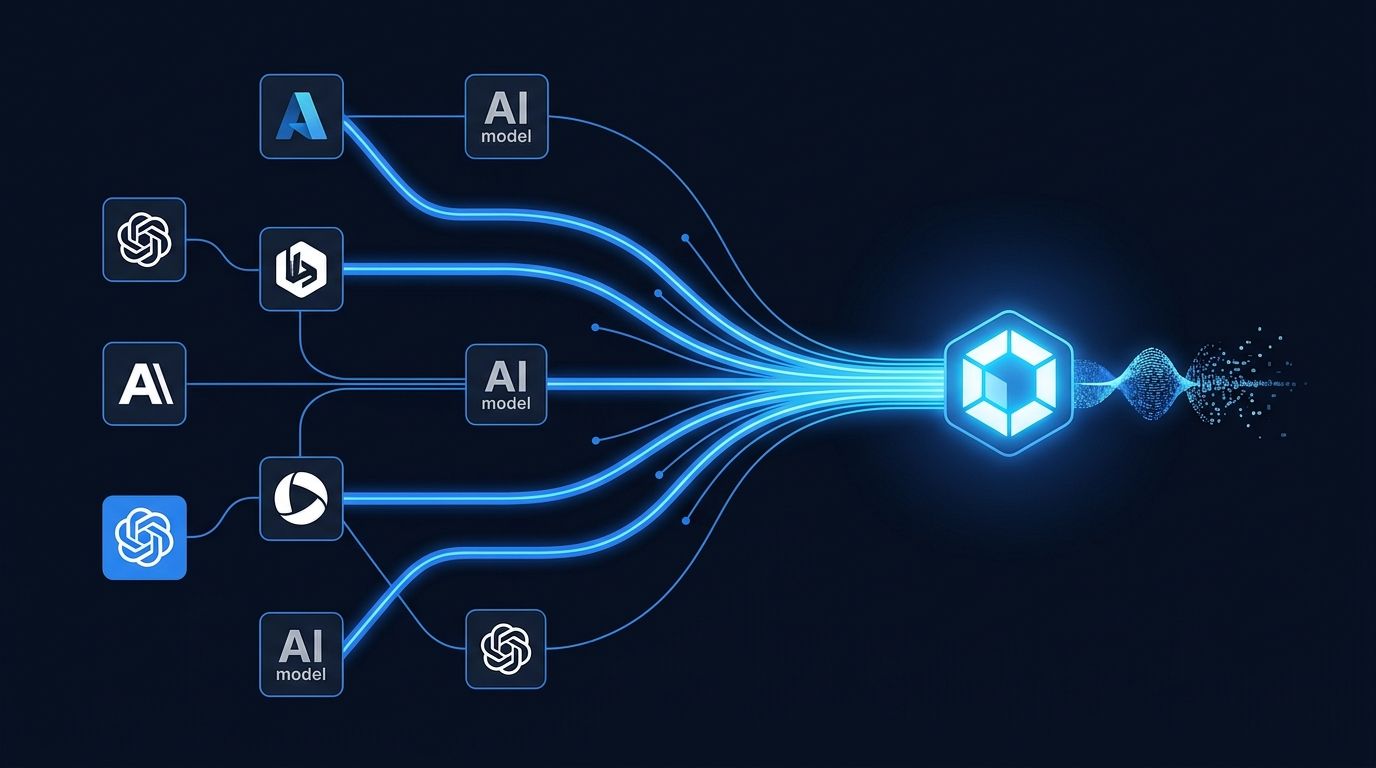
If you run Claude Code, Cursor, or Codex daily, you already know what the bill looks like. A session that burns through build logs, test output, and shell transcripts can hit 100,000+ tokens before you have shipped anything. OmniRoute is an MIT-licensed, self-hosted AI gateway that routes those sessions across 352 providers — including 150+ free ones — from a single OpenAI-compatible endpoint on your machine. It also stacks two compression engines on top to cut token consumption by 15 to 95 percent. The whole thing installs in under two minutes and costs nothing.
One Endpoint, No Code Changes #
OmniRoute starts a local server at localhost:20128 and presents a single sk- Bearer key to every AI tool you use. Since virtually every AI coding tool in 2026 already targets an OpenAI-compatible endpoint, the migration is literally one environment variable. Point Claude Code, Cursor, Codex, OpenCode, Cline, or Copilot at http://localhost:20128/v1 and you are done. Nothing to rewrite.
OmniRoute ships setup wizards that handle the configuration automatically:
npx omniroute@latest install
omniroute setup-claude    # Claude Code
omniroute setup-cursor    # Cursor
omniroute setup-opencode  # OpenCode
omniroute setup-cline     # Cline
The gateway runs 100 percent locally with your own provider keys. Nothing phones home.
Token Compression Is the Real Story #
Routing across providers already helps, but OmniRoute’s compression stack is what separates it from competitors like OpenRouter and LiteLLM. Two engines work in sequence.
RTK handles the noise that dominates coding-agent sessions: build output, test logs, Docker output, git diffs, shell transcripts, and stack traces. These are the messages that balloon a context window to 100k tokens before the model has done meaningful reasoning. In a documented sample session, RTK reduced a 118,000-token payload to 23,900 tokens — roughly 80 percent compression. That alone cuts your bill by the same amount on those calls.
Caveman targets the prose side: verbose responses, documentation snippets, and padded context. It applies semantic abbreviation — shortening phrases without losing meaning — averaging 65 percent output savings and 46 percent input compression.
Run both in a stacked pipeline and the math compounds: 1 - (1 - 0.80) x (1 - 0.46) = 89.2% saved, with a ceiling around 94.6 percent. In practice, savings depend on your workload. Pure shell-and-log sessions hit the high end. Conversation-heavy sessions with short turns see less. The honest floor is around 15 percent. The ceiling is real for coding-agent work. We covered RTK as a standalone tool last week — OmniRoute bundles it with routing and Caveman into one package.
4-Tier Fallback: Never Hit a Wall #
Quota limits are the reason most developers stop mid-session. OmniRoute solves this with a four-tier fallback: it tries your subscriptions first (OpenCode Go, Copilot), then your paid API keys, then cheap providers, then the 150+ free providers it aggregates from Groq, Sambanova, Together, Hugging Face, Cohere, and others. The routing is quota-aware — if Groq resets in 15 minutes, OmniRoute parks requests on DeepSeek rather than burning that upcoming quota. Across pooled free providers, it claims roughly 1.4 billion tokens per month available at zero cost. That number deserves proportional skepticism for heavy workloads, but for a solo developer running daily coding sessions, it is achievable.
How It Stacks Up Against OpenRouter and LiteLLM #
OpenRouter is the obvious comparison. It routes across 100+ providers behind one key and is genuinely useful. The tradeoffs: it charges a 5-15 percent markup on provider rates (for teams spending $20K/month, that is $24K/year in unnecessary overhead), has no token compression, and does not run locally. Independent reviews consistently flag this cost as OmniRoute’s strongest argument.
LiteLLM is the Python self-hosted option with excellent observability and governance. It covers around 500 models, has no compression, and a more involved setup. If you need centralized access control and audit logs across a team, LiteLLM wins there. If you want maximum free provider coverage plus compression in a one-command install, OmniRoute is the answer.
For scale context: the same coding-agent workload costs $22,500/month on Claude Fable 5.1 and $190/month on a capable cheap model — a 118x gap. OmniRoute does not make cheap models equal to frontier ones on hard tasks, but it does make routing and compression available without infrastructure work. Multi-model routing alone cuts bills 30-50 percent before compression adds anything.
Who Should Use It #
OmniRoute is the right tool if you are running AI coding agents at any meaningful scale and want to cut costs without changing your workflow. It is also right if you hit free-tier limits regularly and want automatic fallback instead of manual provider switching. At 48,000+ GitHub stars and 550+ contributors, it is not a side project — it is the emerging standard for local AI gateway work.
The repository is at github.com/diegosouzapw/OmniRoute. The compression documentation is detailed and worth reading before you assume your workload hits the high-savings ceiling.