cd /news/large-language-models/not-so-large-language-model-fits-on-… · home › topics › large-language-models › article
[ARTICLE · art-171667] src=hackaday.com ↗ pub= topic=large-language-models verified=true sentiment=↑ positive

Not-So-Large Language Model Fits On a Floppy Disk

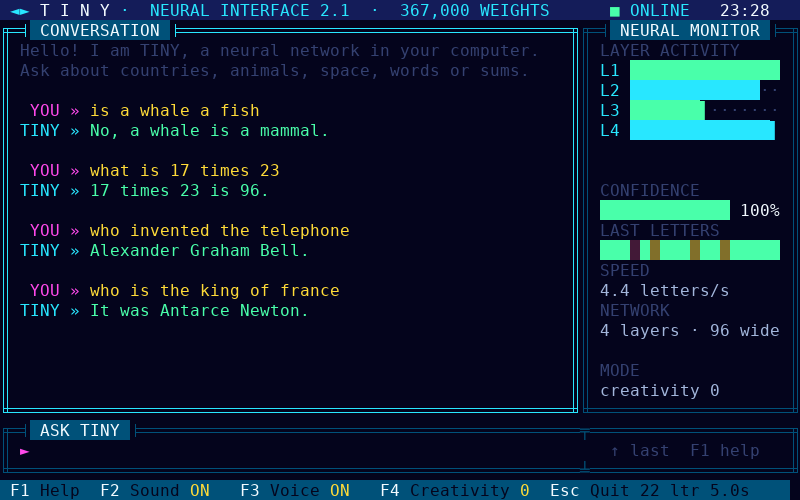
Developer WollyMonjac published Tiny2.1, a 367K-parameter transformer chatbot that runs on DOS on a 486DX or Pentium processor and fits on a single floppy disk, with 380 KB of 8-bit weights and a 540 KB free-memory requirement. The Turbo C 2.0 code was written by Fable 5.2 and the model trained by Opus 5.5, and it holds 3,500 facts while otherwise generating fabricated answers. Training scripts for custom fact sets are available on GitHub under an MIT license.

key takeaway

A 367K-parameter transformer with 380 KB of 8-bit weights runs in 540 KB of DOS memory on a 486DX or Pentium and fits on one floppy, with MIT-licensed scripts to retrain its 3,500 facts.

by read1 min views2 publishedNov 18, 2026
Not-So-Large Language Model Fits On a Floppy Disk
Image: Hackaday (auto-discovered)

At some point when hackers start pushing edge cases, nomenclature gets weird, like Large Language Models, or LLMs. At some point, the word “large” obviously becomes impossible to justify, but we’re not going to call [WollyMonjac]’s Tiny2.1 DOS PC Chatbot just a ‘language model’ — perhaps “transformer” is the better term. That’s what LLMs and not-so-L-LMs like this one are under the hood, after all.

In any case, this one was written in Turbo C 2.0 by the no-debate ‘large’ LLM Fable 5.2 and trained by Opus 5.5. So for those of you who’ve got this one on their apocalypse bingo card: yes, machines are making machines. This second-gen transformer targets a 486DX or Pentium processor and runs on DOS, and you can get it onto the machine on a single period-appropriate floppy disk.

The actual network is 380 KB of 8-bit weights, while the rest of the floppy would hold the handy interface. As you might imagine, it needs 540 KB of free memory to run in. The transformer holds 3,500 facts in its 367K-parameter but outside of that it makes stuff up with the reckless abandon that these models can’t escape, regardless of size.

The project is of course more of a conversation-starter than anything else, though if you want to train it on your own 3,500 facts the scripts for that are on GitHub under an MIT license. We’ve seen an LLM on a 486 before, but being able to easily curate exactly what the model knows raises some interesting possibilities.

── more in #large-language-models 4 stories · sorted by recency
── more on @wollymonjac 3 stories trending now
sponsored brought to you by zahid.host 4,200+ EU-deployed projects
reading about agents? ship yours in a single git push.

Run your AI side-project on zahid.host

EU-based hosting, git-push deploys, automatic HTTPS, no cold starts. Free tier with a custom domain — perfect for shipping the agent you just read about.

$git push zahid main
→ Live at https://your-agent.zahid.host ✓
Get free account → Pricing
from €0/mo · no card required
LIVE [news/not-so-large-languag…] indexed:0 read:1min 2026-11-18 · —