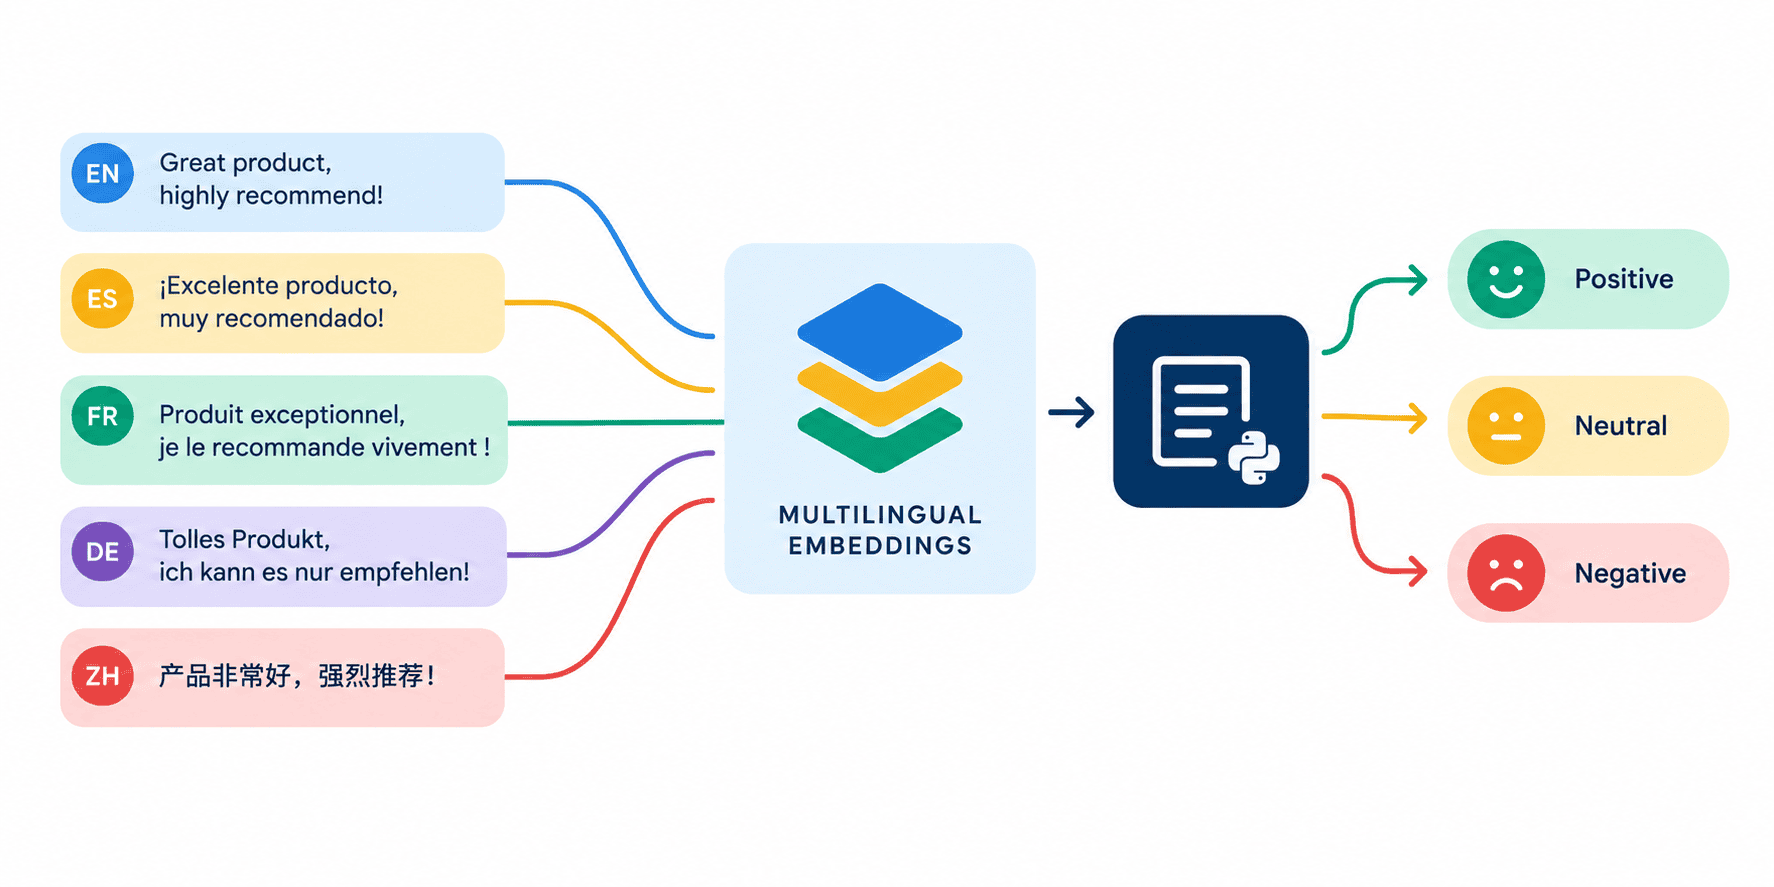
In this article, you will learn how to build a multilingual text classification pipeline using multilingual large language model (LLM) embeddings and Scikit-learn, without training separate models for each language.
Topics we will cover include:
- What multilingual LLM embeddings are and why they eliminate the need for language-specific models.
- How to set up a free, local embedding pipeline using Ollama, BGE-M3, and Scikit-LLM.
- How to train and evaluate a logistic regression classifier on top of multilingual embeddings using a real-world review dataset.
Introduction #
Building machine learning models for a global audience, such as text classifiers based on multilingual data, traditionally required training a separate model for each language. Thus, the process could easily become unmanageable. Thankfully, progress in LLMs also extends to scenarios like this! Multilingual LLM embeddings are numerical representations of text produced by a model that maps text from different languages into a common vector space. With these “barrier-free” embeddings, all it takes thereafter is training a downstream, lightweight classifier on top of them. Let’s uncover how to do this step-by-step, aided by Scikit-LLM.
Initial Setup #
In the sequel, we will construct a multilingual text classification pipeline aided by Scikit-LLM and scikit-learn.
pip install scikit-llm "datasets==2.19.1" -q

apt-get update -qq && apt-get install -y -qq zstd

curl -fsSL https://ollama.com/install.sh | sh

12345678
Ensuring a 100% free and runnable solution in a variety of running environments, including notebooks, requires bypassing paid APIs like OpenAI. That’s why, instead, we have installed an Ollama distribution offering a variety of free LLMs. Accordingly, in the next steps we will configure Scikit-LLM to speak to a local Ollama server running BGE-M3, which is a state-of-the-art, open-source model supporting multilingual information in the embedding generation process.
Next, we start the Ollama server as a background process —this is the most hassle-free way to use Ollama in a cloud-based notebook, but not mandatory if working with your own IDE and local Ollama distribution. We also pull the aforementioned multilingual model for embedding generation, BGE-M3 (more information about this model on its official website).
import subprocess
import time

subprocess.Popen(["ollama", "serve"])
time.sleep(5) # Give the server a few seconds to initialize

ollama pull bge-m3

123456789

import subprocessimport time # Starting the Ollama server in the backgroundsubprocess.Popen(["ollama", "serve"])time.sleep(5) # Give the server a few seconds to initialize # Pulling the multilingual embedding modelollama pull bge-m3
The last configuration step is to use Scikit-LLM’s configuration module to point it to our Ollama instance. The configuration approach we are using does not require an actual key, but a dummy one, as shown below:
from skllm.config import SKLLMConfig

SKLLMConfig.set_gpt_url("http://localhost:11434/v1/")

SKLLMConfig.set_openai_key("free-friendly-dummy-key")

1234567

from skllm.config import SKLLMConfig # Point Scikit-LLM to our local Ollama instanceSKLLMConfig.set_gpt_url("http://localhost:11434/v1/") # Provide a dummy key (required by the internal client, but safely ignored by Ollama)SKLLMConfig.set_openai_key("free-friendly-dummy-key")
Building the Pipeline #
The first major step in building our multilingual classification pipeline is, of course, getting the data. We will consider the Amazon Multi-language Reviews dataset, which has labeled customer reviews on a 5-star rating scale (internally encoded with labels 0 to 4). To avoid an overly time-consuming execution — especially regarding the embedding generation process later on — we will load a total of 2000 reviews in both English and Spanish. Feel free to select a larger sample if you’d like to, but try to keep it language-balanced and ensure random shuffling of your data before applying further steps like a training-test split.
from datasets import load_dataset
import pandas as pd

print(" and shuffling data to ensure class diversity...")

data_en = (load_dataset("mteb/amazon_reviews_multi", "en", split="train", trust_remote_code=True)
           .shuffle(seed=42)
           .select(range(1000)))

data_es = (load_dataset("mteb/amazon_reviews_multi", "es", split="train", trust_remote_code=True)
           .shuffle(seed=42)
           .select(range(1000)))

df = pd.concat([pd.DataFrame(data_en), pd.DataFrame(data_es)], ignore_index=True)

df = df.sample(frac=1, random_state=42).reset_index(drop=True)

X = df['text']
y = df['label']

print(f"Total samples: {len(X)}")
print("\n--- Class Verification (should have samples from 0 to 4) ---")
print(y.value_counts())

1234567891011121314151617181920212223242526272829

from datasets import load_datasetimport pandas as pd print(" and shuffling data to ensure class diversity...") # 1.  the complete split# 2. Shuffling it randomly with shuffle()# 3. Extracting 1000 varied samples with select(range(1000))data_en = (load_dataset("mteb/amazon_reviews_multi", "en", split="train", trust_remote_code=True)           .shuffle(seed=42)           .select(range(1000))) data_es = (load_dataset("mteb/amazon_reviews_multi", "es", split="train", trust_remote_code=True)           .shuffle(seed=42)           .select(range(1000))) # Combining into a single DataFramedf = pd.concat([pd.DataFrame(data_en), pd.DataFrame(data_es)], ignore_index=True) # Shuffling bilingual datadf = df.sample(frac=1, random_state=42).reset_index(drop=True) # Features and LabelsX = df['text']y = df['label'] print(f"Total samples: {len(X)}")print("\n--- Class Verification (should have samples from 0 to 4) ---")print(y.value_counts())
Output:
 and shuffling data to ensure class diversity...
Total samples: 2000

--- Class Verification (should have samples from 0 to 4) ---
label
0    444
3    410
2    404
4    380
1    362
Name: count, dtype: int64

1234567891011

 and shuffling data to ensure class diversity...Total samples: 2000 --- Class Verification (should have samples from 0 to 4) ---label0    4443    4102    4044    3801    362Name: count, dtype: int64
The magic happens next. We define a scikit-learn pipeline consisting of two major stages:
- Using a GPTVectorizer from Scikit-LLM and having it set up to utilize our previously loaded BGE-M3 model for building embeddings.
- Feeding the embeddings to train a classifier based on a LogisticRegression model type.
from skllm.models.gpt.vectorization import GPTVectorizer
from sklearn.pipeline import Pipeline
from sklearn.linear_model import LogisticRegression
from sklearn.model_selection import train_test_split
from sklearn.metrics import classification_report

X_train, X_test, y_train, y_test = train_test_split(X, y, test_size=0.2, random_state=42)

pipeline = Pipeline([
    ("vectorizer", GPTVectorizer(model="bge-m3", batch_size=32)),
    ("classifier", LogisticRegression(max_iter=1000, random_state=42))
])

print("Extracting embeddings and training classifier...")
pipeline.fit(X_train, y_train)

123456789101112131415161718

from skllm.models.gpt.vectorization import GPTVectorizerfrom sklearn.pipeline import Pipelinefrom sklearn.linear_model import LogisticRegressionfrom sklearn.model_selection import train_test_splitfrom sklearn.metrics import classification_report # Splitting into 80% training and 20% testingX_train, X_test, y_train, y_test = train_test_split(X, y, test_size=0.2, random_state=42) # Defining the Pipelinepipeline = Pipeline([    ("vectorizer", GPTVectorizer(model="bge-m3", batch_size=32)),    ("classifier", LogisticRegression(max_iter=1000, random_state=42))]) # Training the pipelineprint("Extracting embeddings and training classifier...")pipeline.fit(X_train, y_train)
Why did I say the magic takes place here? Let’s look more closely:
BGE-M3 is a multilingual embedding model that has been pre-trained on massive data spanning over 100 languages. Put another way, it is capable of internally mapping both our English and Spanish reviews into a common dimensional (embedding) space: not based on their concrete vocabulary, but based on the meaning behind it. Thus, language barriers disappear during the process of generating embeddings, with LLM outputs for “This product is fantastic!” and “¡Este producto es fantástico!” being nearly identical.
As a result, by the time the embeddings arrive at the logistic regression model for training and inference, the classifier doesn’t actually care about the language anymore. It has the information it needs to perform rating classifications on product reviews.
print("Evaluating on the test set...")
y_pred = pipeline.predict(X_test)

print("\n--- Classification Report ---")
print(classification_report(y_test, y_pred))

12345

print("Evaluating on the test set...")y_pred = pipeline.predict(X_test) print("\n--- Classification Report ---")print(classification_report(y_test, y_pred))
Results:
--- Classification Report ---
              precision    recall  f1-score   support

           0       0.66      0.78      0.72        82
           1       0.40      0.30      0.34        64
           2       0.46      0.46      0.46        91
           3       0.56      0.54      0.55        84
           4       0.71      0.73      0.72        79

    accuracy                           0.57       400
   macro avg       0.56      0.56      0.56       400
weighted avg       0.56      0.57      0.56       400

123456789101112

--- Classification Report ---              precision    recall  f1-score   support            0       0.66      0.78      0.72        82           1       0.40      0.30      0.34        64           2       0.46      0.46      0.46        91           3       0.56      0.54      0.55        84           4       0.71      0.73      0.72        79     accuracy                           0.57       400   macro avg       0.56      0.56      0.56       400weighted avg       0.56      0.57      0.56       400
The results are just okay, but not great. There is significantly better performance in correctly predicting extreme ratings (0 for 1-star, 4 for 5-star) than for predicting intermediate ratings. Don’t panic; there are at least two reasons for this:
- The classification task at hand is inherently challenging: distinguishing between a 3-star and a 4-star review is intuitively harder than discerning, for instance, between positive, negative, and neutral reviews.
- More importantly, we have used just 2000 samples (80% of them for model training), but these samples are embeddings with 1024 features each. Feeding such a small amount of high-dimensional data to a classifier is most likely the perfect recipe for overfitting your model. If you have the time to run the code for longer, try using a few thousand more examples instead.
Wrapping Up #
In traditional natural language processing, we were often faced with two far-from-ideal options when handling multilingual data for predictive tasks like text classification: translate all your data into a base language — a slow, expensive process with frequent loss of nuance — or train separate models: one for every language. In the pipeline we just built, the heavy burden is assumed by the multilingual embedding model (BGE-M3) leveraged through Scikit-LLM, which is capable of transparently mapping text across a variety of languages into a uniform embedding space.