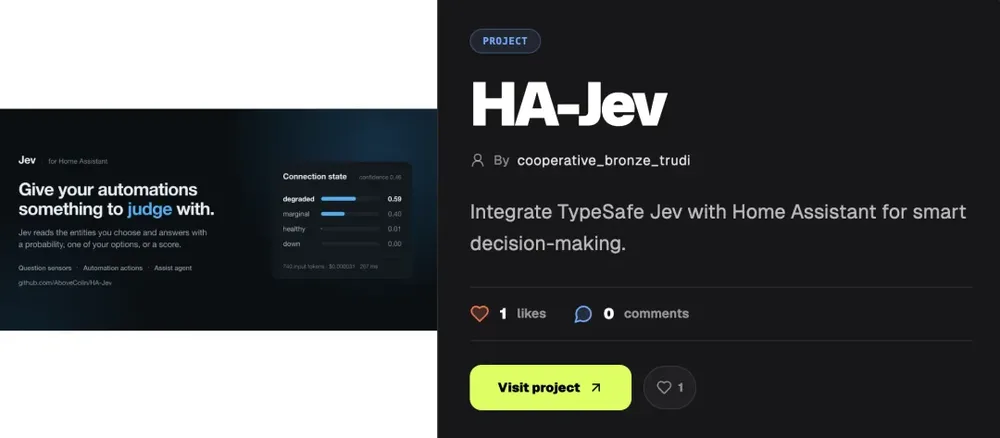
I've been seeing a lot of noise about HA-Jev, a plugin for Home Assistant. The logic is dead simple: it monitors a washing machine's power draw and the laundry room door status. Instead of writing a paragraph, the model just outputs a probability value. If the confidence hits 0.8, you get a notification asking if you forgot your clothes. A single check takes a few milliseconds and costs $0.000015.
The dev's point is spot on—why use a massive LLM to write an essay when you just need a yes/no judgment? We've spent years optimizing for "human-like" fluency, but for actual system engineering, that fluff is just overhead.
Enter Jev, a "System One" model from former OpenAI researcher Diogo Almeida. It doesn't generate text at all; it only outputs probability judgments. Within days of launch, developers have already built nearly 500 open-source projects around it. It's basically the opposite of a chatbot.
Using Jev as a high-speed filter #
The real power here is treating Jev like a cheap, fast neuron rather than a philosopher. I'm seeing some wild use cases for context compression. One dev, Tamara Tran, used a Jev plugin to scrub Claude Code contexts. Instead of summarizing (which is expensive and slow), Jev scores the relevance of historical tool calls. Anything below a certain threshold gets deleted. In one case, a bloated 1 million token context was slashed to 86k tokens in one second without the model generating a single word of text.
Real-world speed and cost benchmarks #
The performance gap between generative models and "judgment" models is staggering:
- Mobile Automation: The Droidrun team built mobile-jev. In a demo, it navigated an Android phone to a Uber payment screen in 9 steps over 21 seconds. It didn't "generate" instructions; it just used Jev for rapid probability matching on where to click or swipe.
- Data Cleaning: One dev had 9,081 product matching records. Using top-tier LLMs was too expensive, but with a 150-line script and Jev, the whole task finished in 13 minutes for exactly $0.32.
- SEO Mapping: Distribb's founder scanned 600 pages and restructured internal links (8,790 decisions) in 45 seconds for $0.21.
- Gaming: People are using it for Super Mario, Doom, and even StarCraft combat missions because it can make decisions in milliseconds.
The economics of the "Jevons Paradox" #
The pricing is the kicker: $0.042 per million input tokens, and output is free. If you're making 10,000 business decisions a day, you're looking at about $120 a month. Doing the same with a top-tier reasoning model could easily blow out to $35,000.
This is a classic Jevons Paradox—when efficiency makes a resource cheaper, we don't use less of it; we use way more. We're moving from "can I afford to run this check?" to "I can run a semantic filter on every single database row."
Shifting to a distributed AI architecture #
We're finally seeing a split between "judgment" and "generation." For the last few years, we treated intelligence as one big block. Jev proves that binding reasoning and expression together is a waste of resources.
The community is moving fast. vLLM contributors already used Google's DiffusionGemma to create an open-source version with accuracy close to the official one.
The future architecture isn't one giant brain. It's a system where cheap, "intuitive" models handle the millions of millisecond-level judgments, and the expensive generative models only wake up when you actually need a human-readable report or a complex piece of writing.
Next Vidu S2 actually lets you edit video in real-time →
All Replies (3) #
I want to try this tonight. I've spent hours fighting with 15 different automation triggers just to get a simple alert.
Curiosity is peaking. Does this work with the 2024.1 update, or is it only for the legacy version of the plugin?
This burned me during my last setup. Does the prompt need a specific temperature setting to avoid looping the power check?