Key takeaways #
- Each generation of Amazon's custom silicon began with a customer workload that needed something better.
- Amazon designs its chips using data from real workloads, its own and its customers', rather than benchmarks.
- Because the hardware is delivered through the cloud, customers get the benefits by simply launching an instance.
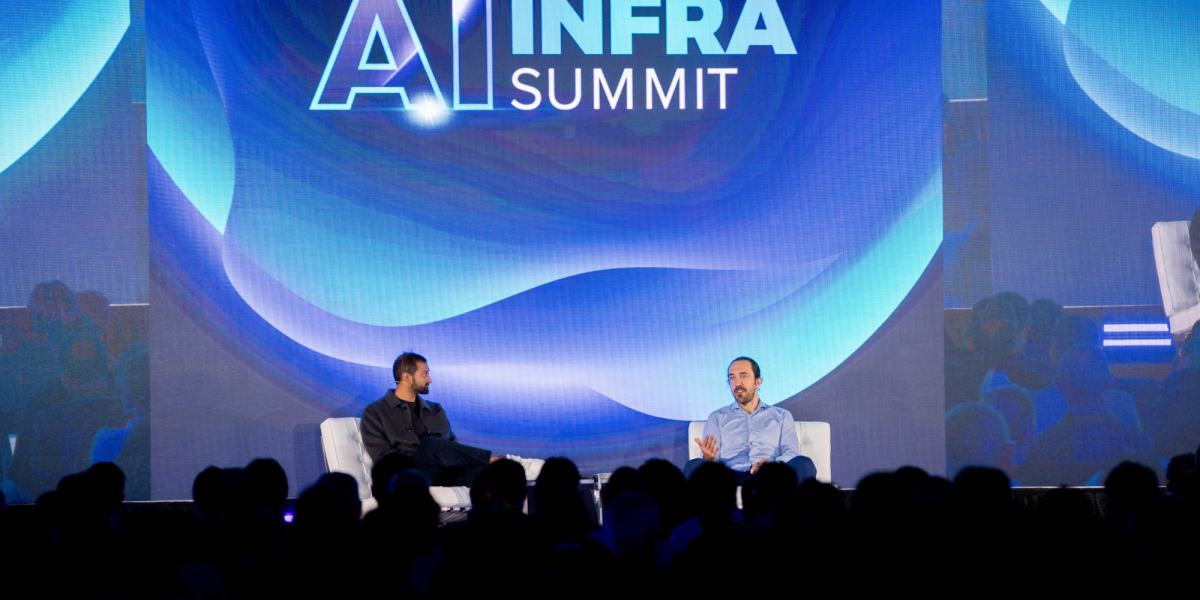
Amazon now designs chipsfor networking, general-purpose computing, and AI. But the company didn't set out to be a chip designer. As Peter DeSantistold the audience at AI Infra Summit on September 16, each step came from trying to solve a problem customers brought to
AWS. “When you're building hardware and building complex systems, understanding the workload deeply is a huge asset,” said DeSantis, Amazon's senior vice president of foundational AI models and custom silicon, in a fireside chat with SemiAnalysis founder Dylan Patel.
A request that led to Nitro #
DeSantis has been at Amazon for 28 years and has worked on
AWS since EC2launched 20 years ago. The original idea, he said, came from recognizing that access to compute was a constraint for startups and enterprises alike. Most workloads ran well on early EC2, but some customers kept asking for bare metal performance. The requests pointed to a real issue: virtualized workloads share resources like chip caches and I/O buses, and no system shares them perfectly. To serve every workload, the team concluded, it would have to innovate at the hardware level.
The result was the
Nitro System, which moves the virtualization stack onto dedicated hardware. That work brought Amazon together withAnnapurna Labs, and with it a shared belief that the cloud would change how specialized hardware reaches people. “You don't have to build a server and build a supply chain,” DeSantis said. Customers just launch an instance.
Why Amazon designed Graviton from real workloads, not benchmarks #
Around 2016, with the year-over-year gains of Moore's Law slowing, Amazon turned to the general-purpose processor. The team had an unusual resource: years of data from running Amazon's own web services and databases, plus everything it had learned helping customers tune their applications.
“All these workloads, all these profiles—that's the right way to optimize a chip and a system, not microbenchmarks,” DeSantis said.
That approach produced
Graviton. Today, DeSantis noted, the vast majority of workloads on AWS run both faster and more cost-effectively on it. The team has also focused on specific workloads that matter to customers, such as databases and chip design software. And as Amazon's scale has taken cost out of the infrastructure, he said, those savings have gone back to customers as lower prices.
How customers shaped Amazon's AI chip roadmap #
The same principle has guided Amazon's AI chips. Its first, Inferentia, was well suited to the AI workloads of 2018 — 2021. When large language models emerged, they demanded something different, and DeSantis said working closely with leading AI customers, along with expanded internal research, helped the team understand what those workloads need and where they're headed. That learning shaped Trainium2 and Trainium3, and the roadmap to Trainium4.
Amazon is also giving customers more ways to tune for their own workloads. Trainium's hardware-enabled profiler collects fine-grained telemetry from production workloads without interfering with them, and the Neuron toolchain gives developers access to the chip's full instruction set.
Designing for where workloads get stuck #
AI workloads, DeSantis said, stress a system in every direction. “One workload is power-bound. The next workload is memory-bandwidth-bound. The next is memory-bound,” he said. “It's one of the most interesting hardware design problems that we've seen in ages.”
Memory is a good example. Memory bandwidth, or how quickly a chip can move data between its memory and its processors, often determines how fast a model can generate responses. Patel described it as the biggest bottleneck in AI today. DeSantis said Amazon has invested heavily in Trainium's memory stack, focusing on both overall memory bandwidth and memory bandwidth per dollar. That mirrors the two things he said have always guided the team: absolute performance and price performance. For customers, it shows up as token throughput, meaning how much a model can produce and at what cost.
That will matter more as inference grows. DeSantis expects the majority of AI compute to go toward inference, whether that's serving end users or generating the rollouts used in reinforcement learning. “Inference is going to be a massive workload,” he said.
He expects hardware to keep adapting to it, while still supporting large training jobs. “I still don't think we're going to want to have a chip for every workload,” DeSantis said, “but I think we're going to see more chips that are better suited to specific workloads.”
Trending news and stories
- Prime Big Deal Days is back October 6-7: Here’s what to expect
- Amazon invests $20 million in the Colorado River as part of a coalition to mobilize $100 million for water conservation
- Amazon is giving every US employee a discount on groceries
- Amazon raises minimum starting pay for full-time core operations employees to $20/hour, with average pay reaching nearly $24/hour