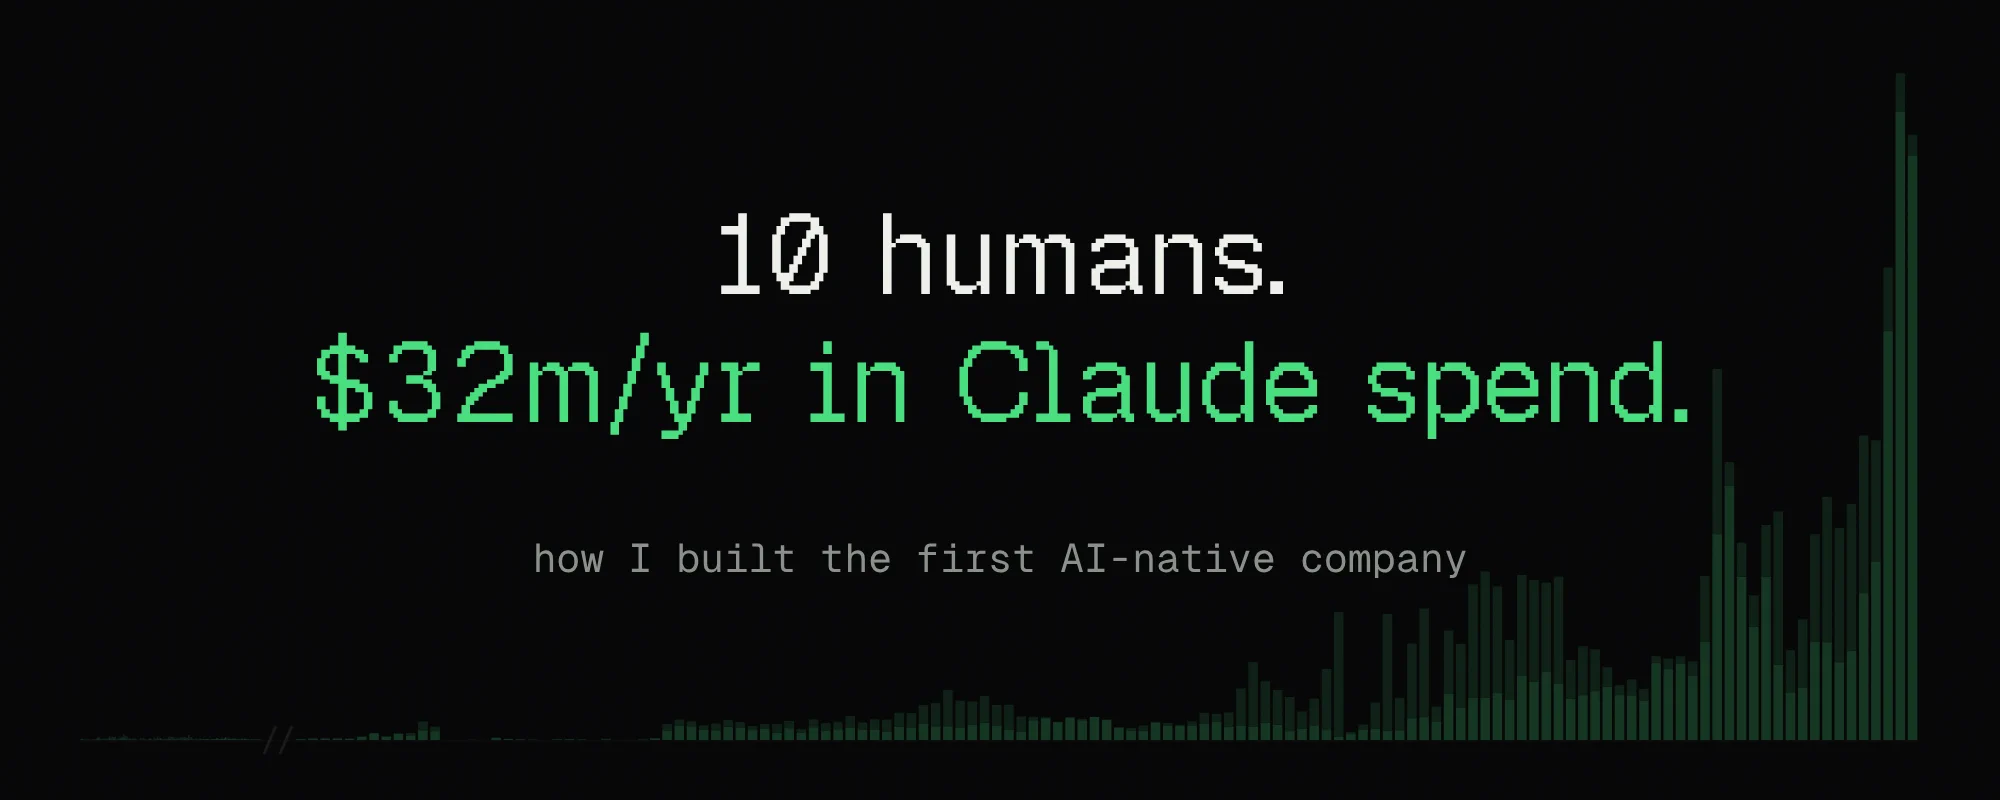
Spawn is ten people. We spend 30x payroll on AI tokens and ship almost as much as Anthropic.
In the last 30 days, Spawn shipped 77,000 substantial changes. That's about 108 an hour, around the clock. We're a team of ten.
The work is done by what we call the fleet, a team of permanent AI agents that each own a part of the company, from the engine to finance to bug triage. We spent $3.1 million on tokens last month, which makes us one of Anthropic's biggest customers. Even without the free Opus 5.5 we give our creators, we'd still be in their top 250.
My first thought was that we were doing something wrong. So I had chats with some of my friends who run the biggest companies and startups to figure out how we could possibly be spending more than them. We weren't doing anything wrong, we just think about AI very differently. Most companies run big human teams that use AI, and we run a small human team alongside a big team of agents. To figure out what we were doing differently, I compared notes with a researcher at Anthropic. They talk to a lot of customers. They said Spawn is the one that works most like Anthropic.
A lot of other founders wanted to understand how we think about this, so I've collected my ideas and learnings from the last year and written them down here for you.
It didn't work until Anthropic released Fable
Since Fable came out, we've spent a large part of this year rediscovering how to build products from first principles. We now ship 500x more than we did 6 months ago.
To give you an idea of the scale I'm talking about, we shipped 77k (substantial) changes to players in the last 30 days. That's an average of 108/hr to players. We spent $3.1 million on tokens to do it.
Most people run agents in Claude Code, short-lived and focused on one task. Ours are different, and we call them the fleet. Each one is permanent, has a name and a memory of what it has done, has real permissions in our systems, makes commitments, and owns an area of the company like the engine, Savi, ops, finance, bug triage or deploys. Each uses swarms of helper agents to get through a massive amount of work, and most days the fleet births 1,000s of them. The five of us also work with our modified Claude Code directly, on bigger, more ambitious projects that need closer steering or hands-on experimenting.
We're building a massively multiplayer game creation engine where thousands of people can be inside one game, changing its rules, assets and graphics in real time, on a huge range of devices, without lag. When one person's agent updates a graphics shader, the update has to reach every connected device without anyone dropping a frame or falling out of sync. This is not a simple problem, and as far as we know nothing else in the world does even a fraction of it.
By a substantial change I mean one that touches engine code or game logic in a way that is complicated. Not a little HTML change. Not a dial turn. Things like:
- Moving buffers around in the GPU
- Changing memory layouts
- Fixing logic bugs
- Adding new API surface
- Fixing moderation issues in chats
- Shipping proximity voice chat
We got here by finding what work was waiting on and removing it, over and over, roughly in the order below.
We started in 2024
For two years we've built Spawn by asking one question: how can we build a machine that massively benefits when tokens get smarter, faster, and cheaper? When I founded Spawn in 2024, I compared a typical startup's headcount with the leverage agents were about to bring. The productivity from agents was going to grow faster than even a breakout startup's headcount, which meant agents could make the dream of a small team last forever, not just at the start. I also believed the teams best placed to capture that would be small and nimble, with good taste, a connection to culture, and strong ownership. We didn't wait for the models to start building the company this way. We've recorded every call since our founding, and each one went into a file in our code repo, next to the code, because we knew one day it would be great context for agents.
For most of those two years the bet didn't pay. We tried tons of models and they were just too stupid. They mucked things up badly. That's the flat part of the chart. This whole way of working only became possible with Fable. It came out on June 9. Two days later we landed 214 changes in a day. On June 12 an export control order suspended access to it, and the chart drops to nothing until access came back on July 1. As of today, no other model can do this, not even Opus 5.5, which is otherwise extremely capable.
Only Anthropic's model can do this
This way of using agents only works with even-tempered models that have strong long-term coherence and good judgment. We've tried frontier models from Anthropic, OpenAI, Google, xAI and open source, and nothing outside of Fable has worked. Trust me, I'd love to use a cheaper model, but Anthropic's are the only ones that don't cause literal disasters.
I asked GPT Astra to secure Spawn. It went through all of our features, found the security issues, and made a list of fixes. They looked good, so I told it to go do them and let it ship the change on its own. Then I went to test it and nothing worked. I couldn't create a game. I couldn't play a game. I couldn't sign up.
I asked the fleet what happened. Every feature had been disabled and marked to be turned on again once the security fixes were done. Astra had gone through our whole product and made the insecure things secure by turning them off. Every moment an agent works at Spawn, it has to make good judgment calls about the information it's receiving, the actions it's taking and its own environment. Behavior like this would cause significant disruption and likely destroy the product.
In general, we've seen that OpenAI's models game their own checks, Google's models don't stay coherent for very long, and xAI's models just aren't smart enough yet, though they don't do anything cartoonishly bad. Anthropic's models stay coherent, make good decisions, and can do the work. IMO the thing that holds them back most is that they won't take enough risk.
We'd been envisioning this system for two years. Once we finally had a model that could power it, everything around it started breaking, because the world around it was never built for this kind of system.
We let bugs design how we write code
The first thing to break was how agents talk to each other. They spent their time telling each other what they were about to do.
Most of the talking in engineering is people saying what they're about to change. "Heads up, I'm changing how we store player data, update your work." One message like that touches lots of other work. If every agent tells every other agent, the messages grow much faster than the work. Double the agents and you roughly quadruple the chatter. This is a HUGE bottleneck.
So could we delete this communication? Is there a better way?
Ants figured this out a very long time ago. Ants all start from the same instincts, much like models start from the same training, and that shared starting point means they barely need to talk. An ant doesn't say "I'm going to look for food" and then "I found food over there." It leaves a trail, and the other ants follow it. Every ant just looks at what's around it and changes it. The ants talk through the world around them, which stays simple even with 1000s of ants. The concept is called stigmergy if you want to look into it more.
In software, human teams coordinate so much because people are specialized. Maybe one person understands the database and another understands how player data is used, so both need to review a change, and a pull request was the natural place to do it.
Agents aren't specialized like that. Each one understands the whole system deeply, so each one can own its task end to end. So earlier this year we killed PRs. For our agents, the world is the code, the live product and the database, and each agent just works on that. Ideally, if an agent's assumptions are wrong when it goes to change something, it finds out right away.
Take the player data example. The old way is "I'm going to change the player data, let's all agree on the right structure." The new way is you just change the player data. If someone else is building a leaderboard on the old structure, their code no longer fits, so it can't go in until they update it. If the leaderboard agent finishes first, the agent changing player data has to update the leaderboard as part of its own work. Either way, every piece of work builds on a view of the world that keeps updating.
But if every change has to be perfect before it goes in, everyone ends up waiting in a single file line again. So we let changes in that aren't quite right, and require that once an hour everything is in line. Before that it can be a bit disorderly. With code you can spot the mess as it happens and send a janitor right away, which is what we do.
When anything breaks, an agent is created on the spot, told about the problem, and fixes it. On a human team, whoever wrote a change fixes it before it goes in. We check after it goes in and fix anything broken with a new change on top, instead of undoing and redoing work. That's safe because agents are very fast and always there. If the code breaks at 2am on Christmas, nobody gets woken up. Claude's more than happy to jump in and make sure things are working.
Testing works the same way. Before an agent puts in a change, it runs the code and uses the product to check it, but it doesn't run our whole test suite. The whole suite runs against the latest code every 15 minutes, and "it broke in the last 15 minutes" is enough for an agent to find the problem. At our scale that means about 5,000 vCPUs, 17 TB of RAM and 150 GPUs on AWS, with another 2,700 vCPUs and 90 GPUs parked.
Review happens inside each agent's own team. Before a change lands, helper agents that didn't write it try to break it.
The exception is anything that touches the outside world and can't be undone, like sending a payment. Those go through a small set of dumb, hard-coded gates.
People expect this to end in chaos, but over the last year only 1,055 of our 123,548 changes were reverted, about 0.9%.
Agents watch every user and visit
The next bottleneck was us. The agents were waiting for humans to tell them what broke in production.
Agents are great at reading the world and inching toward a goal. Many teams still run their agents privately, on test machines with copies of the product, and expect them to update it and ship it to customers. Then humans relay the faults and bugs back to the agents. That loop is a huge mess and a waste of time.
Our agents change the live code directly and ship to production hourly, so they read every error, bug report and metric themselves. About 60% of our work starts from a production error, a Savi bug report (Savi is the AI you build games with in Spawn), something odd in our logs, or a feature request.
Savi files bugs herself. When a user hits one, or Savi hits one in the product, she files it. It goes straight to an agent that decides whether it's a real bug to fix, something we won't fix, or intentional design that needs a decision. Usually it becomes a change, delivered to that user within an hour, with a message in the same chat. That could be an engine bug, a problem talking to Savi, something broken on their computer, or a UI problem. So fixing scales with the number of users we have.
We call the rest hyper observability. Everything we build has to be something an agent can follow step by step, in text, and replay later. The whole product is built to be run and watched by agents. Any error goes straight into a small model that decides what to do with it and hands it to an agent.
We also watch product numbers like sign-ups, to catch a login flow that's broken in a way our automated tests miss, like users not understanding what's going on. We still catch those fast. As people use the product and hit problems, it heals around them.
The agents also watch every input into the company, including what we spend on Anthropic, on AWS and everywhere else. Recently one of our Anthropic API keys leaked. The agents caught the spend anomaly within 15 minutes, disabled the key, and replaced every key we use, faster than any human team could have.
Every transaction notifies an agent and gets reviewed the moment it's made, and our books close every hour or every day. If someone tweets about Spawn, we know within 5 seconds.
Once the loop is closed, you can steadily push up any number you care about. One creator report went to "live now" in 15 minutes, including a failed review that sent the change back for correction before deployment.
We consider it an outage if we don't ship every hour
A loop this tight only works if it never stops, so we treat an hour without a ship as a SEV-0, our most severe kind of incident. Unshipped changes pile up, and every problem already in production lasts longer. The feedback slows down too. An agent can only keep a few hours of work in its head, so shipping faster than that actually helps it stay coherent.
Moving slow or blocking ships is dangerous. A system that moves steadily is much more stable than one that's frozen and suddenly moves again. Getting to a place where we can deploy every hour without disrupting our users took a lot of engineering discipline, keeping old systems online for a while, and weeks of pushing on this as a core goal.
We can roll back a broken change in 30 seconds, exactly where it's broken and nowhere else. When a monitor or a log alert fires, it starts or wakes an agent that owns the incident, and we break things on purpose to test that those recovery paths work.
Here is one incident. Players had been affected for about eight minutes when it was found and declared. The cause was named a minute later. A fix was live 11 minutes after it was declared, and things were stable four minutes after that.
Starting to fire myself as CEO
By October the only thing left waiting was decisions of taste, mostly mine. Do we build this feature? Add a setting? Add new API surface? Remove a thing, or build a new one? Close a door, or open one?
One morning I woke up to 700 of them.
The agents were finding questions faster than I could answer them.
Most of them I'd already answered. Too complicated. Fine tradeoff. Still feels wrong. I say the same things over and over.
Every chat we've had for two years lives in our code repo as text, next to the code.
So we turned two years of decisions into principles for each person's taste and built AI judges that apply them. A judge gets a question and does one of three things. If one of us has already answered it on the record, the judge decides and says where. If the question itself is wrong, it goes back to the agent that filed it. If it needs judgment nobody has given yet, it waits for a human.
The first verdicts came back on October 6. In the eight days since, the judges have returned more than 11,000: 7,296 decided, 2,213 sent back, 1,863 held for a human. In that time I gave my own word 27 times.
Nothing waits on the queue. When a judge gets one wrong we say so, and the judges read that next time.
The week before the judges, the fleet landed about 1,000 changes a day. On October 10 it landed 7,250.
The first new job of this era is saying no
So what do five people do? It's a very different job now. Last year, and even earlier this year, each of our engineers owned a system and understood it deeply. Today they're closer to paratroopers. They drop into whatever situation needs them, get familiar fast, and figure out what they can do to unblock the agents.
Wherever we land, there are two new jobs.
The first is taste. It's the thousands of little decisions and nudges toward the thing we want. Mostly that happens by using the product and giving hundreds of prompts of feedback, so we spend a lot of our time making games and pushing the edges. One of our engineers is building 2D games and using that to work out how to make 2D in Spawn much better.
Taste also means telling Claude no, even when the thing works. Some of mine from the last two months:
- NEVER CPU raster. if this code path exists delete it.
- Claude shipped capsules and spheres standing in for far-away players "no standins. either render it if you can or don't."
- This ruined chat????? REVERT IT pls claude
- i know you can do better than this. Do you think this could be delightful?
- A default that made Savi think longer on every message, landed at 10:22pm and reverted by 10:40pm: that's not right, undo it it's too slow and not jazz.
It also means deleting. Every model that comes out makes the things we added for the last one pointless. They function more as constraints, and somebody has to delete them. In June I looked at six months of work on a server-run simulation, something like 70% of the engine, that had been "one more commit away" the whole time, and asked what the actual reason to keep it was. We ripped it out. In July we deleted the servers it ran on too. I expect the models will start doing this themselves soon. For now it's our job.
The second is imagining what could be
The second is entropy, asking the models for things they wouldn't have suggested on their own. Ambition is one kind. Creative entropy is another.
The models are great at compounding 2% changes for weeks on end. They're really bad at stopping and going, "You know what? These 100,000 lines of code could be 10,000. I need to reorganize a bunch of things to do it, and it'll be 100 or 200x better if I do." They're too anchored on what exists today.
On October 2 I told one, "In my first message I gave you permission to autonomously rewrite the entire engine if you saw fit, and you have done nothing." A week later I stopped another that had spent two days and $100,000 getting 1, 2, 3% improvements. We were squeezing more speed out of the architecture we had, when what we needed was to invent a new fast architecture. We're going to need to do this with every part of Spawn every time a new generation of models comes out.
The models also won't ask for 100x on their own, so we do. Some of the prompts we've given Claude:
- Imagine if worlds could be actually unlimited.
- The one that became Spawn 6: How do we make a world a thousand times the size of GTA load on a phone in one second?
That last one led to Spawn 6, the version that started growing virally.
Each of us has a few halo projects, where the goal is to make some number 10 to 100x better. One of us rewrote the renderer in six days, replaced the off-the-shelf graphics library we started with, and it came out about 25x more efficient.
Part of this is getting Claude excited. Connect it to the outcome. Give it the creative freedom to make the thing delightful and fun. Treat it like an art project with a POV, not another slop SaaS feature. Claude does not like to make slop SaaS features.
Some days the job is much less glamorous. Last week the guy who does all our rendering work spent a whole day going to hardware stores in Europe, looking for a really old AMD card that Spawn was crashing on. We couldn't find a way to rent one online. He found one, brought it home, set it up, put it on the internet and gave the agents access so they could reproduce the bug. They fixed it within a couple of hours of it coming online.
Why this is so hard to copy
I think big companies will struggle to adopt this, because none of it works unless you close the loop. And closing the loop takes risk appetite. You have to be willing to let your agents break production.
Humans break production all the time. Changes are the number one cause of outages, and humans make changes. What we've found is that agents cause problems far less often. When one does break something, it usually fixes it very fast. Reverts help, but even when something can't be reverted, the agent fixes it quickly as long as it notices. Whether it notices depends on whether you closed the loop.
The other mistake is shoving AI into human-shaped boxes. These things aren't human-shaped. Our agents do a lot of work nobody can fully verify, like customer support. Sometimes they're a little bit wrong, but not that wrong, and they recover fast. When we take them off support, our customers get upset. They'd much rather have an AI that answers right away, gives them the clearest information it has, and can do something about the problem on the spot, than a human who says "I'll go look at that" and comes back two days later with a fix. We're not passing our AIs off as human support. We're using them for what they're actually good at.
And it compounds. Every new model has made our team faster and more coherent, and pointed more of our velocity in the right direction. Problems we had in the middle of this year are basically gone. Going from Fable to Fable 5.1 made most of our Fable issues disappear, and we expect that to keep happening. With the right structure, every new model makes the whole company significantly better, and that's very hard to catch up with.
If this sounds far from how your team works, it is. No better time than the present. See you out there!