Get the best of each week in your inbox, free → Adding new data to an AI model usually means weeks of trial and error. Google's patent application describes hiding each piece of data in turn and ranking which ones the model can't live without.
What Google's missing-data test actually does #
You're on a team that runs a spam filter, and someone hands you a list of new clues the filter could use: the sender's country, the time of day, how long the message is. Which ones would actually make it better? Today, finding out can eat weeks of an engineer's time.
Google's patent application describes a shortcut. Instead of building a fresh model for every combination of clues, it takes one model and hides one clue at a time, then watches how much worse the answers get. The clue whose absence hurts the most is the one that matters most.
It also groups clues that say nearly the same thing, so you don't pay twice for the same information. What comes back is a ranked list, so your team can decide where to spend its effort.
How Google ranks data by what the model misses #
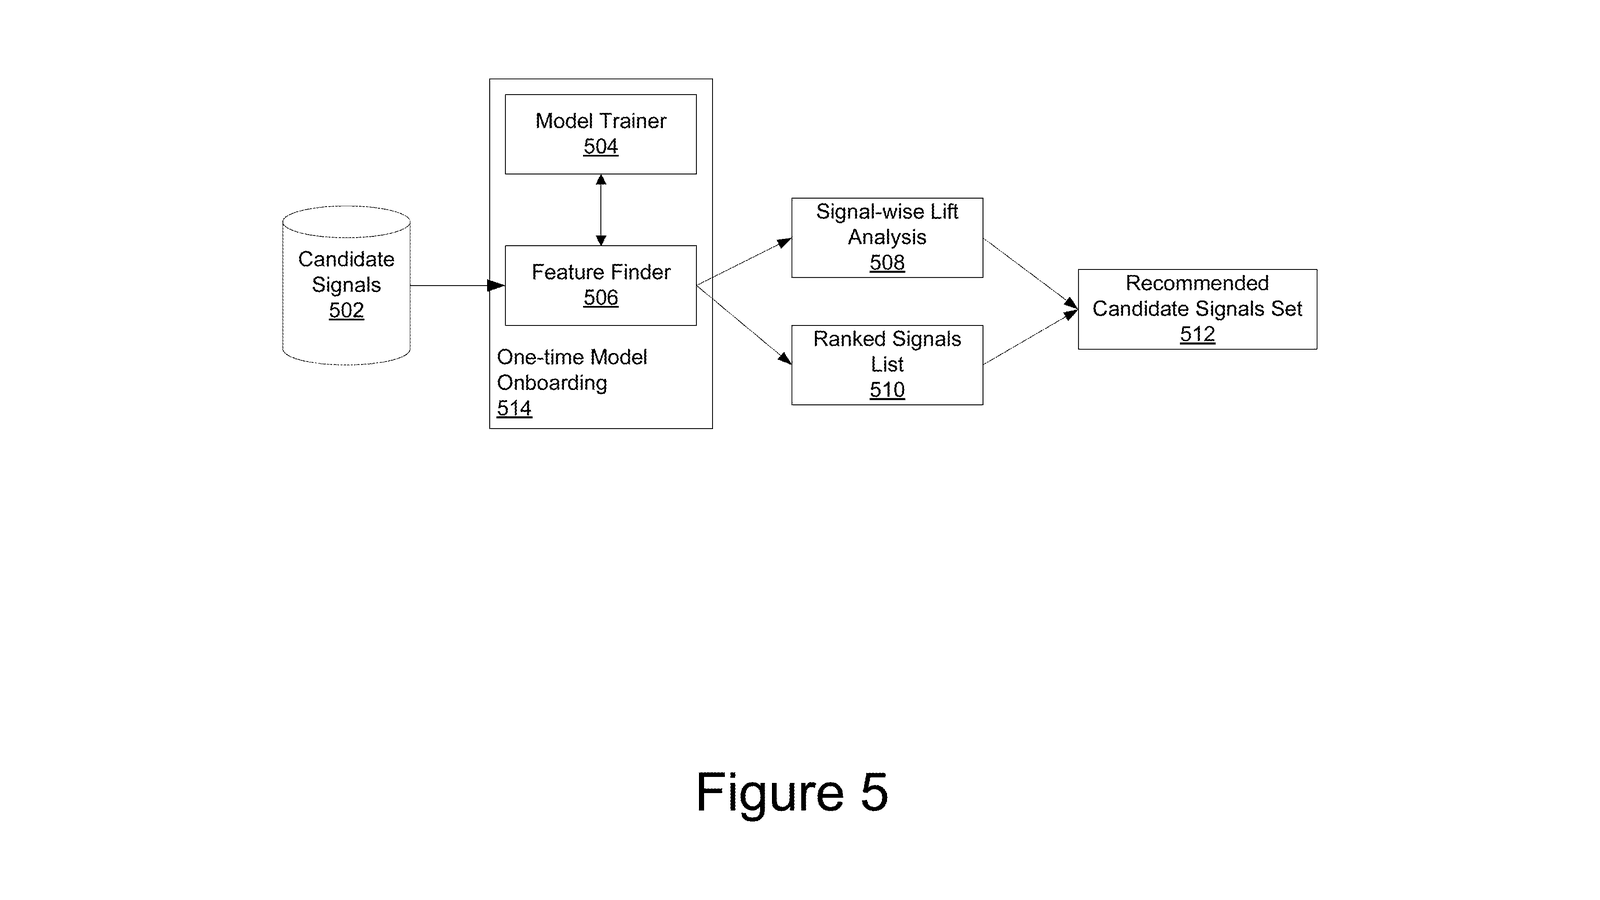
The claims cover a loop that works signal by signal. A signal is one column of input data, such as a user's country or a message's length. For each signal, the system gives an attention-based model (the type of AI behind large language models, which weighs which parts of its input matter most) a text version of the data with that signal removed. Removal means replacing every value with a null marker, a blank.
The system compares the model's output with a baseline, the output from the full, untouched input. The gap is the performance lift: how much that signal was helping. The filing lists several ways to measure it, including precision, recall, and semantic similarity (how close two answers are in meaning). Signals are then ranked by lift. One variation uses a pre-trained large language model with no retraining or fine-tuning for any signal.
To handle overlap, the filing also describes grouping signals by how closely they track each other. Signals become dots in a graph, and the strength of their relationship becomes the weight on the line between them. Tightly linked signals land in one cluster, which gets its own score. As a double-check, a separate model can be trained on the top picks to catch false alarms.
The filing says the old method needs 16 models to test just four new signals.
Why this could speed up Google's AI testing #
For anyone building AI products, the practical gain is time. The filing says an experiment that would take an engineer weeks can shrink to hours, and it can use far fewer computers because the model is trained once instead of once per combination of new data. It also opens testing to people who don't know a model's inner workings. A newer developer could hand over a dataset and get a ranked list back, without touching the model's plumbing. For you, the effect would show up indirectly: faster tests could mean quicker improvements to the apps and services built on these models.
Google's 25th filing in the AI recommendation patents we've tracked since May follows one on generating ad scenes from photos and one on forecasting sales at scale.
Hiding a clue and watching what breaks is a cheap test, and the price is accuracy. A model that has never seen a blank in that spot may stumble for reasons that have nothing to do with how useful the clue is. The filing seems aware of this: it adds a check that trains a separate model on the top picks to catch false alarms.
Overlapping clues are the other weak spot. If two columns say nearly the same thing, hiding one barely moves the score, so a valuable clue can look useless. Grouping similar clues into clusters patches that, though the result depends on where you set the line for similar.
The ranking also looks only at how much the model improves. It ignores how hard each clue is to collect. That is a fair trade for a first screening, since people can weigh the cost afterward. For teams buried in candidate data, giving up some precision to save weeks reads as a good deal.
Get our take in your Top Stories
Liked this breakdown? Add Patentlyze as a preferred source on Google, and our plain-English take shows up more often in your Top Stories the next time Google patent news breaks.
Add Patentlyze on GoogleOne click.
There are more where this came from
We read every patent application Big Tech publishes and send you the ones worth knowing. Plain English, free, every week.
The drawings #
10 drawing sheets from US 2026/0350475 A1 · click any drawing to enlarge
Show the other 2 sheets #
[Browse all the drawings 10 drawing sheets](#all-drawings)

    Want this weekly breakdown for a company we don't cover?
    [Patentlyze Pro →](https://patentlyze.com/pro/?src=post)
Source. Full patent text and figures from the
official USPTO publication PDF.