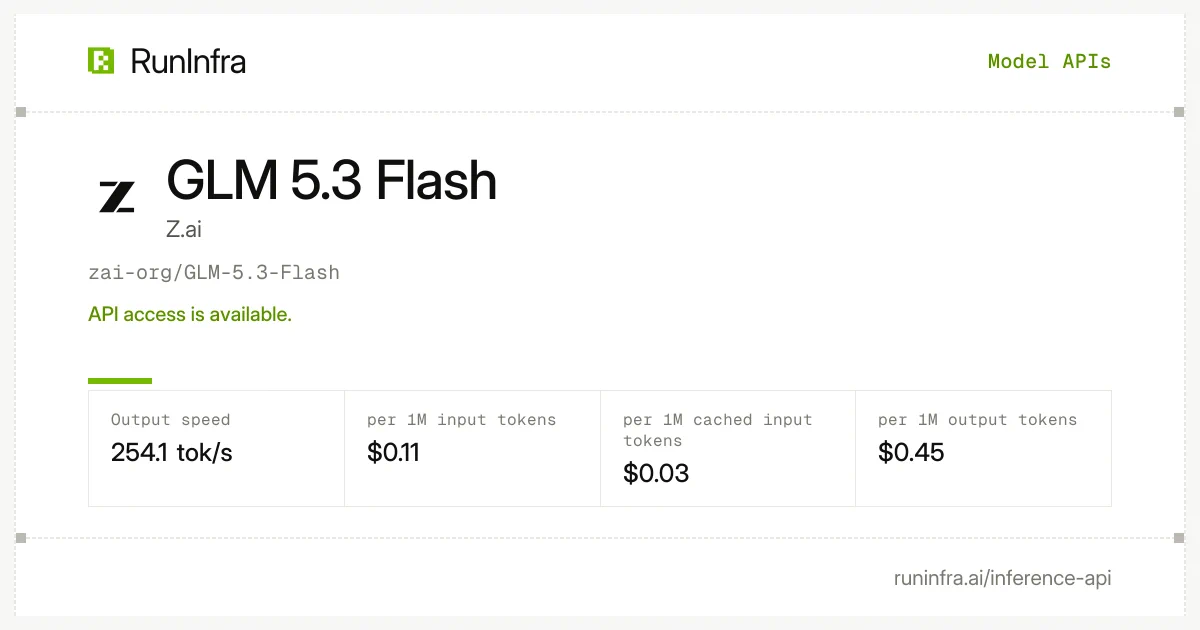
we spent september rewriting the kernels behind GLM 5.3 Flash. major release is live on RunInfra today 670 tok/s on Vercel AI Gateway $0.11 per 1M input, $0.45 per 1M output, $0.03 per 1M cached. 1M token context. FP8, vendor-native release it now runs on AMD. same model, same API, more capacity behind it 99.7% cache hit rate over the last 24 hours. every hit and miss shows up in your dashboard, so you can track the cache logs yourself OpenAI-compatible chat completions and Anthropic-compatible /v1/messages. text and image input, tool calling, JSON mode, streaming zero data retention. never used for training
GLM 5.3 flash on AMD GPUs 670 tok/s
GLM 5.3 Flash is now live on RunInfra running on AMD GPUs, delivering 670 tokens per second on the Vercel AI Gateway at $0.11 per 1M input tokens, $0.45 per 1M output tokens and $0.03 per 1M cached tokens with a 1M token context window. The vendor-native FP8 release keeps the same model and API while adding capacity, and reports a 99.7% cache hit rate over the last 24 hours with cache logs visible in the dashboard. The model supports OpenAI-compatible chat completions and Anthropic-compatible /v1/messages endpoints, text and image input, tool calling, JSON mode and streaming, with zero data retention and no training on customer data.
Run your AI side-project on zahid.host
EU-based hosting, git-push deploys, automatic HTTPS, no cold starts. Free tier with a custom domain — perfect for shipping the agent you just read about.