cd /news/large-language-models/giraffebench-1-0-the-quality-of-loca… · home › topics › large-language-models › article
[ARTICLE · art-173008] src=keno303.github.io ↗ pub= topic=large-language-models verified=true sentiment=· neutral

Giraffebench 1.0 – The quality of local and cloud LLMs in a way you can see

Giraffebench 1.0 published benchmark runs of Qwen4 Max, a 2400B mixture-of-experts model released November 16, 2026 and served closed-weight through OpenRouter by Alibaba, showing the model completing a coding task in 25 minutes at 26.4 tokens per second for $0.371 under the pi 1.5.0 harness and in 20 minutes at 24.7 tokens per second for $0.549 under OpenCode 2.2.5. The pi run used 39 requests and 1,411,522 tokens (75,942 new input, 1,295,616 cached, 39,964 output) with 19,240 reasoning tokens billed, while the OpenCode run used 49 requests and 2,358,792 tokens (100,580 new input, 2,228,736 cached, 29,476 output) with 28,161 reasoning tokens billed. Both runs were billed at OpenRouter list prices of $1.50 per million input tokens, $0.075 per million cached tokens and $4.50 per million output tokens, with no thinking setting sent so the model default applied.

recommendation

Route heavy agent runs through harnesses that maximize cached input: Qwen4 Max billed cached tokens at $0.075 versus $1.50 per million new input, and the pi run's 1,295,616 cached tokens held total cost to $0.371.

more in playbook: Controlling LLM cost
read1 min views5 publishedNov 20, 2026
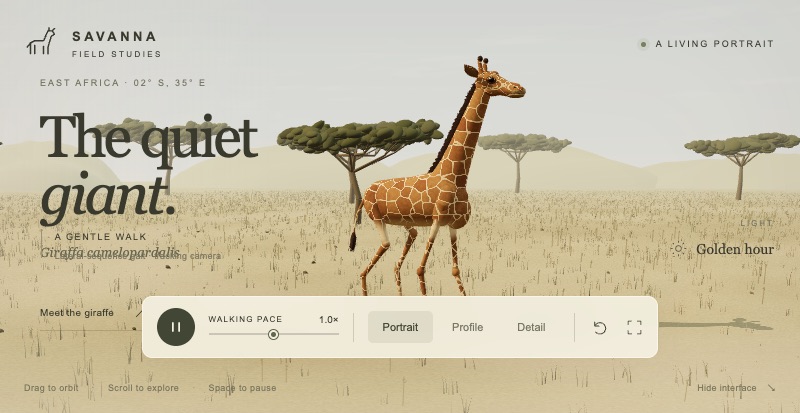
Giraffebench 1.0 – The quality of local and cloud LLMs in a way you can see
Image: source

Run the giraffe

Qwen4 Max

Qwen · OpenRouter · 2400 B MoE

Released November 16, 2026

25 min

26.4 tok/s

$0.371

Details #

  • Model on OpenRouter
  • qwen/qwen4-max
  • Weights
  • Closed model, weights not published
  • Released
  • November 16, 2026 (date the model was added to OpenRouter)
  • Hardware
  • Cloud via OpenRouter, served by Alibaba
  • Harness
  • pi 1.5.0
  • Thinking
  • Model default (pi and OpenCode sent no thinking setting to OpenRouter, so the model default applied) 19,240 reasoning tokens billed
  • Coding time
  • 25 min, 39 requests
  • Tokens
  • 1,411,522 (75,942 new input, 1,295,616 cached, 39,964 output)
  • OpenRouter cost (real, via API)
  • $0.371 (list price per million tokens: $1.50 input, $0.075 cached, $4.50 output)

Run the giraffe

Qwen4 Max

Qwen · OpenRouter · 2400 B MoE

Released November 16, 2026

20 min

24.7 tok/s

$0.549

Details #

  • Model on OpenRouter
  • qwen/qwen4-max
  • Weights
  • Closed model, weights not published
  • Released
  • November 16, 2026 (date the model was added to OpenRouter)
  • Hardware
  • Cloud via OpenRouter, served by Alibaba
  • Harness
  • OpenCode 2.2.5
  • Thinking
  • Model default (pi and OpenCode sent no thinking setting to OpenRouter, so the model default applied) 28,161 reasoning tokens billed
  • Coding time
  • 20 min, 49 requests
  • Tokens
  • 2,358,792 (100,580 new input, 2,228,736 cached, 29,476 output)
  • OpenRouter cost (real, via API)
  • $0.549 (list price per million tokens: $1.50 input, $0.075 cached, $4.50 output)
── more in #large-language-models 4 stories · sorted by recency
── more on @giraffebench 3 stories trending now
sponsored brought to you by zahid.host 4,200+ EU-deployed projects
reading about agents? ship yours in a single git push.

Run your AI side-project on zahid.host

EU-based hosting, git-push deploys, automatic HTTPS, no cold starts. Free tier with a custom domain — perfect for shipping the agent you just read about.

$git push zahid main
→ Live at https://your-agent.zahid.host ✓
Get free account → Pricing
from €0/mo · no card required
LIVE [news/giraffebench-1-0-the…] indexed:0 read:1min 2026-11-20 · —