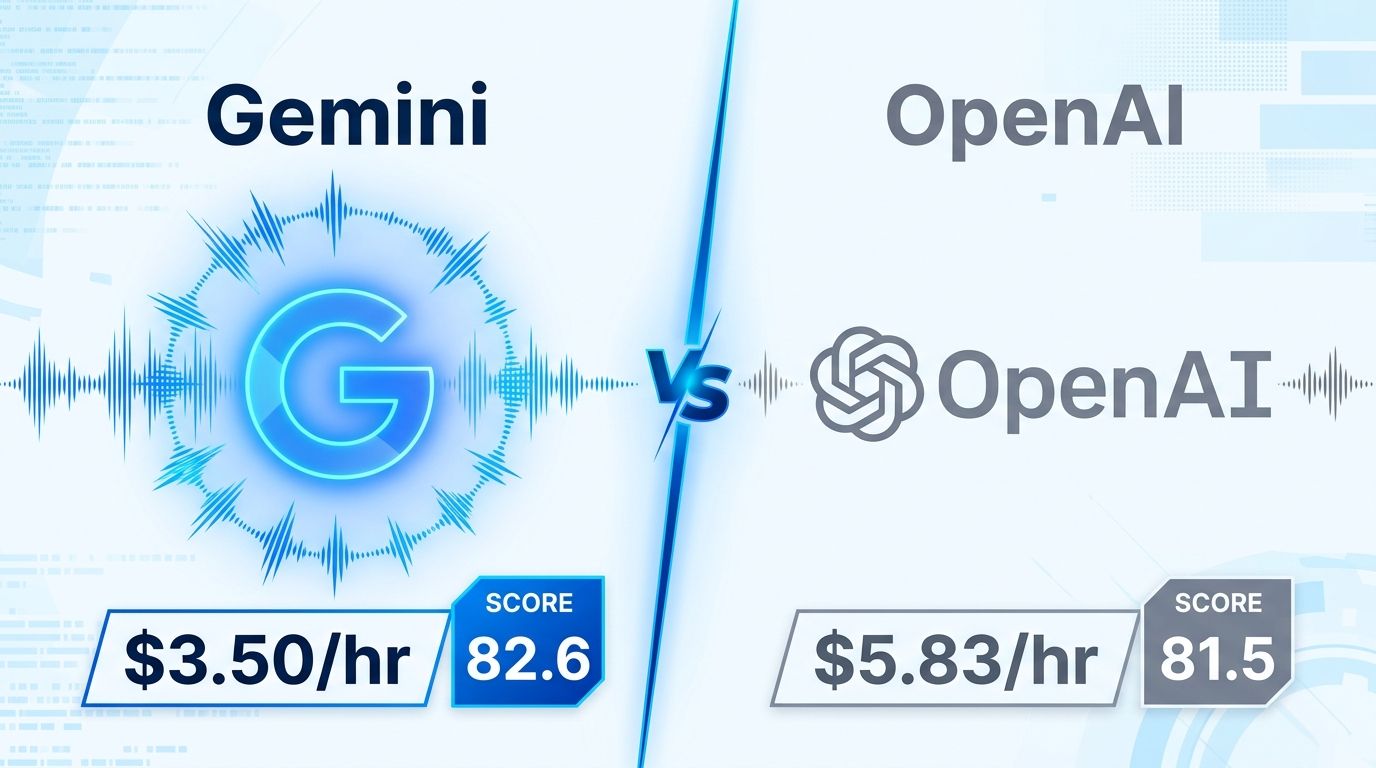
Google shipped two native speech-to-speech models yesterday, September 15, that are available now in the Gemini API and Google AI Studio: Gemini 3.8 Live and Gemini 3.8 Live Extended Thinking. The benchmarks make the case plainly — Extended Thinking scores 82.6 on Artificial Analysis’ Speech to Speech Quality Index, edging GPT-Live-1 Astra’s 81.5, and does it at $3.50 per hour versus $5.83 for OpenAI’s model. For developers running voice agents, that’s a 40% cost reduction with a better benchmark score. The math is not complicated.
Gemini 3.8 Live Extended Thinking: What It Actually Delivers #
The phrase “extended thinking” sounds like marketing, but here it describes something technically specific: the model can reason and speak at the same time, without creating conversational dead air. When Gemini 3.8 Live Extended Thinking executes a tool call — checking a database, querying an API, running a calculation — it narrates live progress while the background call runs. “Let me pull that up for you…” is not a canned phrase triggering a wait loop. It’s the model tracking what it’s doing and reporting it in real time.
This matters because the alternative is silence, hold music, or an obvious stall — and users interpret dead air as failure. The Extended Thinking model solves this architecturally through NON_BLOCKING async tool execution, not with UX workarounds. According to the Live API capabilities documentation, Extended Thinking only supports async mode, which means background tool calls run concurrently with speech output by design. On the τ-Voice agentic benchmark, Extended Thinking scores 68.6% versus GPT-Live-1 Astra’s 67.9%, and on τ³-Banking — tasks like working through a support case or processing a refund — it leads 35.1% to 32.0%.
Related: VoiceStudio: Local Voice Cloning With a Drop-In OpenAI API
Why the Cascade Pipeline Is Now a Legacy Choice for Voice #
Traditional voice agents chain three separate models: a speech-to-text model transcribes the audio, an LLM processes the text, then a text-to-speech model converts the response back to audio. Each handoff adds latency. Combined, a realistic cascade pipeline introduces 450 to 1,000ms of processing delay, and the transcription step strips out prosodic context — tone, emphasis, hesitation — that helps the model understand what the user actually meant.
Gemini 3.8 Live processes audio end-to-end in a single model, targeting sub-200ms end-to-end latency and preserving acoustic context across the full pipeline. That’s not a minor optimization — it’s the difference between a voice agent that sounds like an IVR menu and one that sounds like it’s listening. The official Google announcement positions these models specifically as replacements for cascaded architectures at scale. If you’re still running a cascade pipeline for voice in 2026, it’s not because there’s no better option.
Pricing That Forces the Comparison #
The base Gemini 3.8 Live model costs $0.84 per hour on Artificial Analysis’ input audio measure — roughly one-seventh the cost of GPT-Live-1 Astra. Even the Extended Thinking variant at $3.50 per hour comes in 40% cheaper than OpenAI’s model, while outperforming it on every agentic benchmark cited. Grok Voice Think Fast 2.0 sits at $4.80 per hour with an 81.3 Speech-to-Speech Quality Index score, placing third on both quality and price.
This is a concrete disruption for teams running voice agents at scale. Voice API costs accumulate fast — a customer support bot handling 10,000 hours monthly moves from a $58,300 bill with GPT-Live-1 to $35,000 with Extended Thinking, or $8,400 with the base model for simpler workflows. The full benchmark and pricing comparison breaks down the numbers for all competitors side by side.
What Developers Get Right Now #
Both models are available today through the Gemini API and Google AI Studio. The model IDs are gemini-3.8-live and gemini-3.8-live-extended-thinking. The API uses stateful WebSocket connections with 16-bit PCM audio input at 16kHz and 24kHz audio output, with a 128k token context window. Session limits are 15 minutes for audio-only and 2 minutes for audio plus video — design session resumption logic for workflows that run longer. Additionally, both models support 97 languages with automatic mid-conversation detection.
Moreover, LangChain, LiveKit, Pipecat, Agora, and Vercel all have native integrations available at launch. That means existing voice agent infrastructure on any of these platforms can adopt Gemini 3.8 Live without replacing the orchestration layer. Enterprise customers deploying at launch include Salesforce and ServiceNow, both using the Extended Thinking model for complex customer interaction workflows. For high-volume simpler flows where reasoning overhead is unnecessary, the base Gemini 3.8 Live at $0.84 per hour keeps unit economics clean.
Key Takeaways #
- Gemini 3.8 Live Extended Thinking scores #1 on Artificial Analysis’ Speech to Speech Quality Index (82.6) at $3.50/hour — versus GPT-Live-1 Astra at $5.83/hour
- Extended Thinking enables live narration during background tool calls through NON_BLOCKING async execution, eliminating the dead-air problem in complex agentic workflows
- Native speech-to-speech architecture replaces the cascade pipeline (ASR + LLM + TTS), cutting latency from 450-1,000ms to sub-200ms and preserving prosodic context
- Both models are in the Gemini API and Google AI Studio now, with day-one integrations for LangChain, LiveKit, and Pipecat
- Session limits (15 min audio-only, 2 min audio+video) require session resumption planning for longer workflows