Full speed ahead: Despite calls to slow AI down, its support structure is on the fast track
While tech titans at Salesforce Inc.’s Dreamforce event in San Francisco this week engaged in a spirited debate over whether the pace of deployment for artificial intelligence should be slowed, a group of high-powered tech experts were meeting at the same time about an hour’s drive south to describe how they were building AI’s infrastructure as fast as possible. At the AI Infra Summit in Santa Clara, technologists from companies such as Amazon Web Services, Oracle, Broadcom, Qualcomm and d-Matrix, outlined how they were hard at work to optimize infrastructure for the ever-increasing demands of AI. The challenges surrounding the technology are becoming clearer with every passing day. AI is power-hungry and a voracious memory consumer, and the cost of tokens is currently spiraling out of control for many enterprises.
“Tokens per watt has become the new key metric in this AI war,” Tony Pialis, executive vice president and general manager of datacenter and AI at Qualcomm, said during a presentation at the conference on Wednesday. “We clearly cannot stay on this trend. We on the infrastructure side need to do better.”
Building for inference demand
Exponential demand for AI has generated a diversity of compute in a remarkably short period of time. Though training AI models required significant amounts of graphics processing unit power for much of 2025, a focus on inference this year had resulted in skyrocketing token usage and the need for a more heterogeneous infrastructure that brings central processing units into the mix.
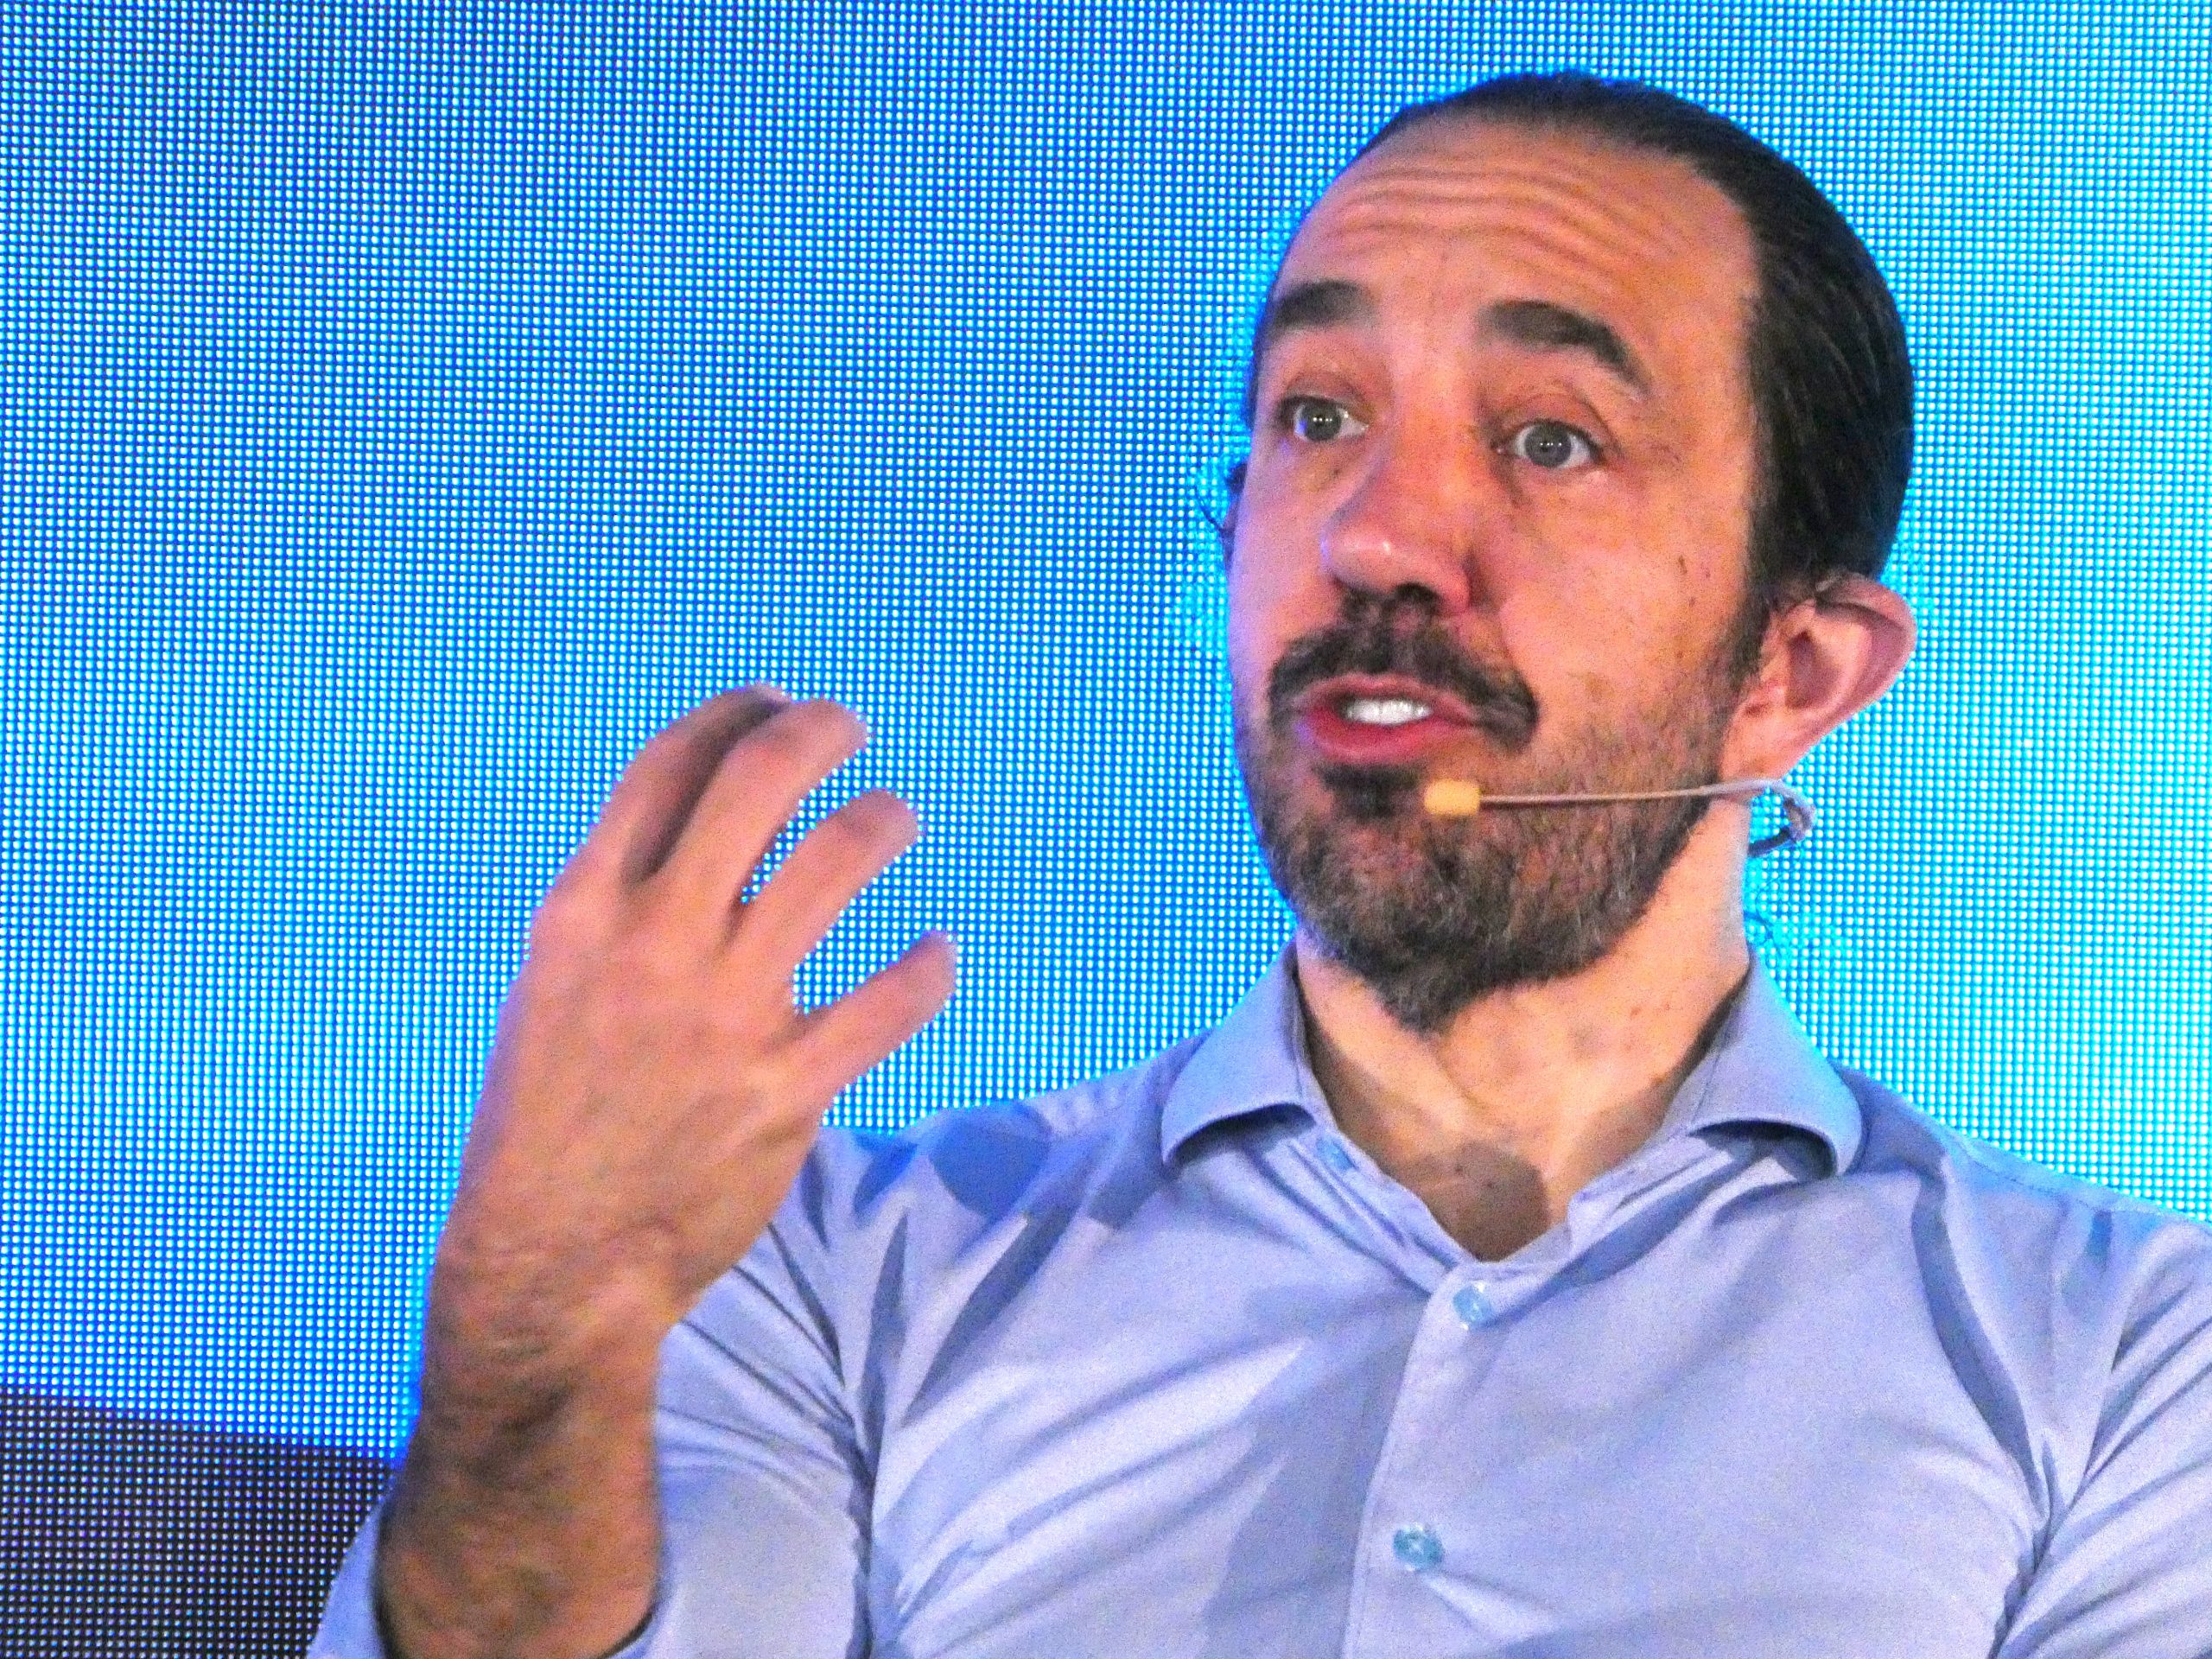
For industry hyperscaler Amazon Web Services Inc., which has built its own CPU portfolio over the years, this represents a prime opportunity to shape future infrastructure for AI. “The majority of compute is going to be serving inference,” said Peter DeSantis (pictured), a senior vice president at Amazon. “Inference is going to be a massive workload.” Central to AWS’ strategy is Graviton, the company’s family of 64-bit Arm-based CPUs developed to provide energy efficiency in powering applications for the cloud. In June, AWS launched the Gaviton5 CPU to support real-time AI reasoning and multistep task orchestration.
“Today, the vast majority of workloads on AWS run cost effectively and faster on Graviton,” said DeSantis, who noted that AI was poised to unlock more specialization in software. “I think there’s a whole wave of general-purpose workloads that’s going to come from that.”
Breaking through the memory wall
In addition to the balancing act surrounding GPUs and CPUs, there is the increasingly critical role of memory for AI processing. As documented by SiliconANGLE’s analysts, a typical AI server uses roughly eight times more memory than a traditional server, and AI server memory spend is projected to jump from $35 billion in 2025 to between $175 billion and $190 billion by 2027, roughly a fivefold increase.
This accelerated growth has led to a divergence of opinion around the optimal solutions for meeting AI’s substantial memory needs. Over the past year, Qualcomm has shifted its focus from traditional high-bandwidth eemory or HBM to a new proprietary architecture called high-bandwidth compute or HBC.
Qualcomm Inc. estimates that its HBC provides six times the bandwidth per watt versus HBM for large batch sizes, and 200 times the capacity per watt versus Static Random-Access Memory or SRAM solutions. The company sees HBC has a way to overcome the memory wall, where compute has exceeded both memory and bandwidth, according to Qualcomm’s Pialis.
“The bottleneck is data movement, not arithmetic,” he said. “The way to solve that is to bring the compute even closer to the memory. We’ve effectively moved the data into the same condo where the compute is. Everybody now has the same elevator, up and down. HBC delivers the benefit that the industry needs.”
Raptor DRAM solution with Nvidia
There’s another sector in the enterprise tech community that has been pursuing a different solution for the memory wall, one that relies on Dynamic Random Access Memory or DRAM instead. Computing startup d-Matrix Corp. has integrated higher-throughput 3D DRAM into its next-generation chip architecture called Raptor. The solution stacks multiple layers of memory cells vertically, allowing for higher storage density and improved performance.
“We are much better than SRAM,” d-Matrix founder and CEO Sid Sheth explained in his AI Infra presentation. “We actually do much better than HBM. We’ve been preparing for a world of infinite inference for a long time.”
Last week, Sheth’s company unveiled a collaboration with Nvidia Corp. to incorporate Raptor into the AI chip giant’s rack reference architecture, NVLink Fusion. The solution is designed for AI labs, hyperscalers and neoclouds to deploy ultra-low-latency premium-level token services.
“We decided to just ride on that infrastructure,” Sheth said. “We go from a Vera Rubin rack to a Vera Raptor rack with this approach.”
Networking for scalability
In the quest to shape millions of GPUs, CPUs, storage systems, memory and software into a productive machine, networking has become a central part of the AI infrastructure story.
Networking is becoming essential in the success equation for enterprise AI for better performance, scalability and cost. One example of this focus on networking is Oracle Corp.’s Acceleron, a high-performance network virtualization architecture and converged SmartNIC technology designed for Oracle Cloud.
Oracle’s alliances with Nvidia and Advanced Micro Devices Inc. resulted in a networking technology called Acceleron RoCE that boosted performance and bypassed routing of data through the central processing units of servers that host GPUs.
“We really have to optimize every part of the stack,” said Karan Batta, senior vice president of Oracle Cloud Infrastructure. “Networking is becoming just as important as the compute itself.”
Broadcom Inc. has also been a major influence in the shaping of networking tech to support AI deployment. In a historical twist, the company built its network architecture for AI around Ethernet, a technology developed in the 1970s.
Ethernet is known for high speeds and low latency. Broadcom has developed its networking portfolio for AI by leveraging Ethernet fabric in AI clusters.
Broadcom’s Tomahawk 6 networking chip, introduced last year, was optimized to power Ethernet switches in data centers. Tomahawk 6 optimizes network speeds using a set of AI features known as Cognitive Routing 2.0, which avoids performance bottlenecks by detecting network congestion and rerouting data to other connections.
“There is unanimous industry consensus that the largest clusters on the planet are using Ethernet for scale up,” said Hasan Siraj, vice president of products at Broadcom. “The network is the computer.”
As demonstrated during the presentations at the AI Infra Summit in Silicon Valley this week, a lot of work is going into building the infrastructure to support AI. A simple reason for this is emerging: AI is now being deployed in the enterprise and customers need to make it better.
During one panel session, several speakers mentioned big bills from token spending in one breath, and then shrugged off the cost in the next.
“We’ve actually let the meter run,” said Arun Nandi, chief data and AI officer for Carrier Global Corp., which has seen an eight-fold increase in token spend this year. “That is the bill for discovery. For us, it’s less about the cost per token and more about the value per task.”
Featured photo: Robert Hof/SiliconANGLE
Support our mission to keep content open and free by engaging with theCUBE community. Join theCUBE’s Alumni Trust Network, where technology leaders connect, share intelligence and create opportunities.
- 15M+ viewers of theCUBE videos , powering conversations across AI, cloud, cybersecurity and more
- 11.4k+ theCUBE alumni — Connect with more than 11,400 tech and business leaders shaping the future through a unique trusted-based network
Are you an AWS customer? Support SiliconANGLE financially by buying your AWS services from our Marketplace portal page and links: https://siliconangle.com/aws-marketplace/
About SiliconANGLE Media
theCUBE AIand theCUBE SuperStudios — with flagship locations in Silicon Valley and the New York Stock Exchange — SiliconANGLE Media operates at the intersection of media, technology and AI.
Founded by tech visionaries John Furrier and Dave Vellante, SiliconANGLE Media has built a dynamic ecosystem of industry-leading digital media brands that reach 15+ million elite tech professionals. Our new proprietary theCUBE AI Video Cloud is breaking ground in audience interaction, leveraging theCUBEai.com neural network to help technology companies make data-driven decisions and stay at the forefront of industry conversations.