Aug 26, 2026
Written By:
Douglas Orr and Luka Ribar
We're Hiring
Join us and build the next generation AI stack - including silicon, hardware and software - the worldwide standard for AI compute
It’s great to have a vision-language model (VLM) in your pocket. The combination of textual and visual intelligence is a perfect fit for personal devices like phones, laptops and wearables. However, such models can be memory-intensive and challenging to deploy on low-power devices. While demand continues to grow for large frontier models running in the cloud, AI for power constrained mobile devices and robotics is also growing fast.
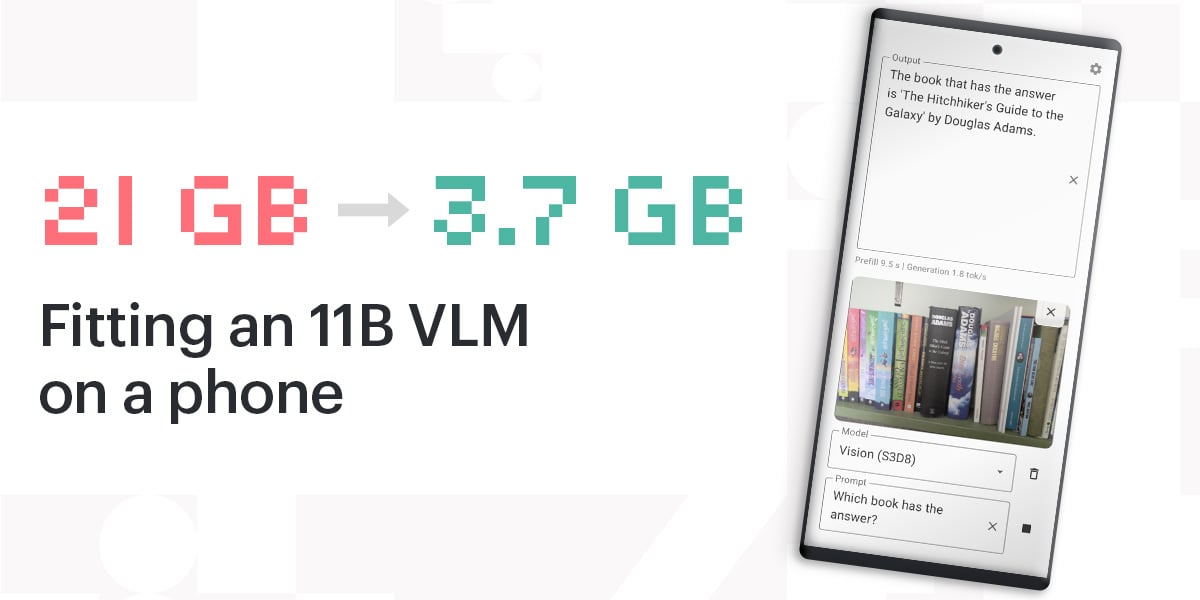
A team of Graphcore and Arm researchers recently took on a deliberately ambitious challenge: to fit a large 11B VLM, originally requiring more than 21 GB for its weights, into a storage budget of roughly 4 GB, to fit on an Android phone.
The result was a 3.7 GB implementation of Llama 3.2 Vision Instruct, which we achieved using a novel format codesigned with Arm CPUs in mind and a quantisation-aware training procedure that samples diverse prompts to retain the capabilities of the original model.
Getting there required solving three connected problems:
An effective weight quantisation format must balance three competing requirements. It should be:
Taking inspiration from the instruction set of our target platform, we developed a format called S3D8, a highly compact 2.7 bit/weight format that balances speed and fidelity in this regime. The core idea is to store the absolute value of 3 weights as a 5-bit index, and then to store 3 separate sign selection bits to recover the decoded weights.
Using 3D vector quantisation provides substantial fidelity benefits over 1D formats (see paper), and the use of a small lookup table allows fast in-register table lookup for decoding. For example, our benchmarks show a matrix-vector product between a 4096-element INT8 activation vector and a 4096 x 14336 matrix achieving 26.5 GMAC/s for an INT8 matrix, but 33.8 GMAC/s for S3D8, running on an Android phone. This speedup is possible since the additional decompression work of S3D8 is outweighed by the bandwidth saving for the weights from memory. Simple “direct cast” quantisation of each weight tensor to the nearest S3D8 value completely breaks the model, achieving zero accuracy across 4 downstream tasks. This is because quantisation down to 2.7 bits/param is too aggressive for the model to handle without a chance to adjust the weights and recover performance.
We therefore employed quantisation-aware training (QAT) to recover performance in the quantised model. QAT quantises the model in the forward pass and passes gradients through the quantisation operation in the backward pass to adjust the weights, training them to reproduce the outputs of the original unquantised model. While this technique is highly effective, we found it to be very sensitive to the distribution of inputs used during training.
We developed a sampling procedure which first samples user prompts as a combination of three components: template, optional instruction and question. It then samples a completion from the unquantised teacher model. This improves performance on downstream tasks substantially versus a more basic procedure (see paper).
Putting it together, our method outperformed alternative formats and quantisation procedures considerably:
As we wanted a proof-of-concept demo running on a phone CPU, our task was not yet complete. We also designed and built:
We release our implementation to support future development using these ideas. We were pleased, and perhaps a little relieved, to see the complete method running on a phone. It’s not ready for mainstream use on mobile phones quite yet – the 11B model is a bit too heavy, and our implementation would benefit from Vulkan kernels to improve prefill time. But we hope this format and training recipe prove to be useful tools for compression of VLMs/LLMs, pushing more intelligence into our devices.
If you’re interested to learn more, check out our technical blog, where you can also access the installable demo. Or dive straight into the paper for a complete explanation of the work and results. Sign up for Graphcore updates: