cd /news/large-language-models/font-where-each-token-is-equal-width · home › topics › large-language-models › article
[ARTICLE · art-140182] src=twitter.com ↗ pub= topic=large-language-models verified=true sentiment=↑ positive

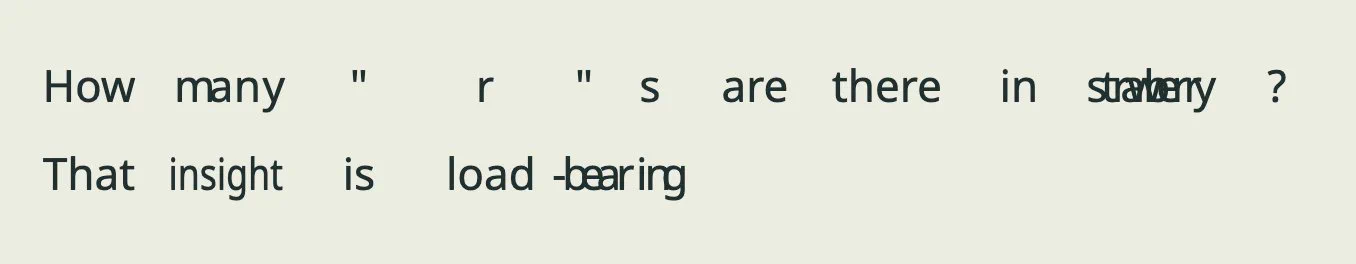
Font where each token is equal-width

Developer "&." released an early-prototype webpage at ampdot.mesh.host that generates a token-space font by combining a base font with a user-selected tokenizer, giving every token equal width so AI outputs can be read as the model wrote them. The tool ships with install instructions for Discord and Slack, and the Claude variant uses dynamic-programming and shortest-paths search inside the font to find the most compact tokenizer representation, implemented via GSUB and cmap because OpenType caps ligatures at 65,536. The author reports GLM-5 and LLaMa 3 remain "very unreliable," while other listed tokenizers are accurate 99%+ of the time, with rare edge cases around merge rules, text wrapping, Unicode support and kerning; Poolside Laguna and Arcee AI Trinity score 97% on the Project Gutenberg subset used for testing.

read1 min views1 publishedSep 26, 2026
Font where each token is equal-width
Image: source

&. on X: "working with Astra to make a font where each token has equal width (early prototype) maybe this will make it easier to understand why models have the quirks they do"

working with Astra to make a font where each token has equal width (early prototype) maybe this will make it easier to understand why models have the quirks they do

working with Astra to make a font where each token has equal width (early prototype) maybe this will make it easier to understand why models have the quirks they do

I did not expect this post to get as much attention as it did... Anyway! With this webpage, you can make your own token-space font by combining a base font with a tokenizer of your choice

ampdot.mesh.host/token-space-fo… Disclaimer: GLM-5 & LLaMa 3 are still very unreliable. The other listed ones are accurate 99%+ of the time but there are still rare edge cases around merge rules, text wrapping, Unicode support, and kerning.

If you care about those things, please come back tomorrow The compiler page has instructions on how to install the font into Discord and Slack, so you can read AI outputs the way the AI wrote it (@poolside Laguna and @Arceeai Trinity are merely 97% on the subset of Project Gutenberg books used to test, so they also need fixes- come

OpenType has a 65,536 ligature limit and tokenizers are fucked up so this had to be implemented using GSUB and cmap The Claude one uses dynamic-programming and shortest-paths search inside the font to search for the most compact possible representation inside the tokenizer

── more in #large-language-models 4 stories · sorted by recency
── more on @&. 3 stories trending now
sponsored brought to you by zahid.host 4,200+ EU-deployed projects
reading about agents? ship yours in a single git push.

Run your AI side-project on zahid.host

EU-based hosting, git-push deploys, automatic HTTPS, no cold starts. Free tier with a custom domain — perfect for shipping the agent you just read about.

$git push zahid main
→ Live at https://your-agent.zahid.host ✓
Get free account → Pricing
from €0/mo · no card required
LIVE [news/font-where-each-toke…] indexed:0 read:1min 2026-09-26 · —