#
Floating point subnormal values can impact the performance of certain mathematical operations on GPU because they require additional handling by the instructions on the hardware. This impact can be more pronounced in workloads that are bottlenecked by instruction throughput.
If some operations are not sensitive to subnormal values, using flush-to-zero (FTZ) instructions or other mathematical approximations can improve performance by treating subnormal values as zero, thereby reducing the instruction overhead associated with handling them. Sigmoid is one such operation where FTZ can be applied effectively.
In this blog post, I would like to quickly discuss how approximation techniques can be applied to the sigmoid function in CUDA to improve performance in instruction-throughput-bound workloads.
#
We have two implementations of the approximated sigmoid function in CUDA. The first one is FTZ based and it results in four instructions per element, which is much fewer than the native non-FTZ reference implementation. The second one is even more efficient but comes at the cost of slightly reduced numerical accuracy.
The first implementation changes the sigmoid computation formula mathematically to make it more amenable to FTZ optimizations. Specifically, it rewrites the sigmoid function as:
$$
\begin{align}
\text{sigmoid}(x)
&= \frac{1}{1 + e^{-x}} \
&= \frac{1}{1 + 2^{-x \cdot \log_2 e}} \
\end{align}
$$
This allows the use of FTZ-friendly instructions for the exponential and reciprocal operations, including ex2.approx.ftz.f32 for the base-2 exponential and rcp.approx.ftz.f32 for the reciprocal.
The second implementation approximates the sigmoid function using tanh, leveraging the mathematical identity:
$$
\begin{align}
\text{sigmoid}(x) &= \frac{1}{2} \left(1 + \tanh\left(\frac{x}{2}\right)\right)
\end{align}
$$
There is tanh.approx.f32 instruction in CUDA that provides an approximate computation of the hyperbolic tangent function, which can results in more efficient instructions as we will see later.
The implementations of the sigmoid functions using the native tl.sigmoid, the FTZ-based approach, and the tanh approximation in Triton are provided below. We will measure their numerical parities, benchmark their performances, and examine their PTX and SASS code after compilation.
|
123456789101112131415161718192021222324252627282930313233343536373839404142434445464748495051525354555657585960616263646566676869707172737475767778798081828384858687888990919293949596979899100101102103104105106107108109110111112113114115116117118119120121122123124125126127128129130131132133134135136137138139140141142143144145146147148149150151152153154155156157158159160161162163164165166167168169170171172173174175176177178179180181182183184185186187188189190191192193194195196197198199200201202203204205206207208209210211212213214215216217218219220221222223224225226227228229230231232233234235236237238239240241242243244245246247248249250251252253254255256257258259260261262263264265266267268269270271272273274275276277278279280281282283284285286287288289290291292293294295296297298299300301302303304305306307308309310311312313314315316317318319320321322323324325326327328329330331332333334335336337338339340341342343344345346347
|
#!/usr/bin/env python3"""Compare Triton sigmoid implementations in an instruction-throughput-bound workload.Run with the NVIDIA PyTorch container:docker run --rm --gpus all -v "$(pwd)":/mnt -w /mnt \ nvcr.io/nvidia/pytorch:26.08-py3 python triton_sigmoid.py"""import argparsefrom collections.abc import Callablefrom dataclasses import dataclassfrom pathlib import Pathimport torchimport tritonimport triton.language as tlBLOCK_SIZE = 256NUM_WARPS = 4@triton.jitdef sigmoid_tl_kernel( x_ptr, y_ptr, n_elements, repetitions_ptr, block_size: tl.constexpr,): offsets = tl.program_id(0) * block_size + tl.arange(0, block_size) mask = offsets < n_elements value = tl.load(x_ptr + offsets, mask=mask) repetitions = tl.load(repetitions_ptr) for _ in tl.range(0, repetitions, loop_unroll_factor=1): value = tl.sigmoid(value) tl.store(y_ptr + offsets, value, mask=mask)@triton.jitdef sigmoid_ptx_ftz(value): # sigmoid(x) = 1 / (1 + 2**(-x * log2(e))). # # The FTZ modifiers intentionally flush subnormal intermediate values # to zero. ex2.approx and rcp.approx also make this an approximation. return tl.inline_asm_elementwise( asm=""" { // A float32 temporary holding -x * log2(e), then 1 + exp(-x). .reg .f32 exponent; // Round x * -log2(e) to nearest-even. The hexadecimal literal // is -log2(e). ".ftz" flushes subnormal operands/results to zero. mul.rn.ftz.f32 exponent, $1, 0fBFB8AA3B; // Compute an approximate base-2 exponential: 2**exponent, // which is exp(-x). ".ftz" flushes subnormal values to zero. ex2.approx.ftz.f32 exponent, exponent; // Form the sigmoid denominator, 1 + exp(-x), with // round-to-nearest-even and flush-to-zero behavior. add.rn.ftz.f32 exponent, exponent, 1.0; // Compute an approximate reciprocal, 1 / (1 + exp(-x)), and // flush subnormal inputs/results to zero. rcp.approx.ftz.f32 $0, exponent; } """, constraints="=f,f", args=[value], dtype=tl.float32, is_pure=True, pack=1, )@triton.jitdef sigmoid_ptx_ftz_kernel( x_ptr, y_ptr, n_elements, repetitions_ptr, block_size: tl.constexpr,): offsets = tl.program_id(0) * block_size + tl.arange(0, block_size) mask = offsets < n_elements value = tl.load(x_ptr + offsets, mask=mask) repetitions = tl.load(repetitions_ptr) for _ in tl.range(0, repetitions, loop_unroll_factor=1): value = sigmoid_ptx_ftz(value) tl.store(y_ptr + offsets, value, mask=mask)@triton.jitdef sigmoid_tanh_approx(value): # sigmoid(x) = 0.5 * (tanh(x / 2) + 1). return tl.inline_asm_elementwise( asm=""" { .reg .f32 tanh_value; // Scale the sigmoid input to tanh's x / 2 argument. mul.rn.f32 tanh_value, $1, 0f3F000000; // Evaluate the hardware's native approximate float32 tanh. // tanh.approx.f32 does not provide an FTZ modifier. tanh.approx.f32 tanh_value, tanh_value; // Convert tanh(x / 2) to sigmoid(x): (tanh_value + 1) / 2. add.rn.f32 tanh_value, tanh_value, 1.0; mul.rn.f32 $0, tanh_value, 0f3F000000; } """, constraints="=f,f", args=[value], dtype=tl.float32, is_pure=True, pack=1, )@triton.jitdef sigmoid_tanh_kernel( x_ptr, y_ptr, n_elements, repetitions_ptr, block_size: tl.constexpr,): offsets = tl.program_id(0) * block_size + tl.arange(0, block_size) mask = offsets < n_elements value = tl.load(x_ptr + offsets, mask=mask) repetitions = tl.load(repetitions_ptr) for _ in tl.range(0, repetitions, loop_unroll_factor=1): value = sigmoid_tanh_approx(value) tl.store(y_ptr + offsets, value, mask=mask)Kernel = Callable[..., None]@dataclass(frozen=True)class KernelVariant: name: str kernel: Kernel required_ptx: tuple[str, ...] required_sass: tuple[str, ...] key_sass: tuple[str, ...]SIGMOID_VARIANTS: tuple[KernelVariant, ...] = ( KernelVariant( name="tl.sigmoid", kernel=sigmoid_tl_kernel, required_ptx=("ex2.approx.f32", ), required_sass=("MUFU.EX2", "MUFU.RCP"), key_sass=("MUFU.EX2", "FADD", "MUFU.RCP"), ), KernelVariant( name="PTX FTZ", kernel=sigmoid_ptx_ftz_kernel, required_ptx=( "ex2.approx.ftz.f32 exponent, exponent;", "rcp.approx.ftz.f32", ), required_sass=("MUFU.EX2", "MUFU.RCP"), key_sass=("FMUL.FTZ", "MUFU.EX2", "FADD.FTZ", "MUFU.RCP"), ), KernelVariant( name="PTX tanh approx", kernel=sigmoid_tanh_kernel, required_ptx=("tanh.approx.f32 tanh_value, tanh_value;", ), required_sass=("MUFU.TANH", ), key_sass=("FMUL", "MUFU.TANH", "FADD"), ),)def launch(kernel: Kernel, x: torch.Tensor, repetitions: torch.Tensor) -> torch.Tensor: output = torch.empty_like(x) grid = (triton.cdiv(x.numel(), BLOCK_SIZE), ) kernel[grid]( x, output, x.numel(), repetitions, block_size=BLOCK_SIZE, num_warps=NUM_WARPS, ) return outputdef error_summary(actual: torch.Tensor, expected: torch.Tensor) -> tuple[float, float]: difference = (actual - expected).abs() return difference.max().item(), difference.mean().item()def check_parity(size: int) -> None: # Include normal, large, and subnormal-adjacent sigmoid outputs. x = torch.cat(( torch.linspace(-100.0, 100.0, size - 8, device="cuda"), torch.tensor( [-104.0, -100.0, -90.0, -20.0, 0.0, 20.0, 90.0, 100.0], device="cuda", ), )) expected = torch.sigmoid(x) repetitions = torch.ones(1, device="cuda", dtype=torch.int32) print("Numerical parity against torch.sigmoid (one application, float32):") print( f"{'implementation':<16} {'max abs error':>16} {'mean abs error':>16}") for variant in SIGMOID_VARIANTS: actual = launch(variant.kernel, x, repetitions) max_error, mean_error = error_summary(actual, expected) print(f"{variant.name:<16} {max_error:16.8e} {mean_error:16.8e}")def benchmark(size: int, repetitions: int) -> None: x = torch.randn(size, device="cuda", dtype=torch.float32) repetition_count = torch.tensor([repetitions], device="cuda", dtype=torch.int32) # With one input load and one output store per element, increasing # repetitions raises arithmetic intensity without increasing global traffic. bytes_per_element = 2 * x.element_size() print( "\nInstruction-throughput-bound benchmark " f"(elements={size:,}, repetitions={repetitions}, " f"global traffic={bytes_per_element * size / 2**20:.1f} MiB/kernel):") print(f"{'implementation':<16} {'median (ms)':>14} {'G elements/s':>16}") for variant in SIGMOID_VARIANTS: launch(variant.kernel, x, repetition_count) milliseconds = triton.testing.do_bench( lambda: launch(variant.kernel, x, repetition_count)) gigaelements_per_second = size / (milliseconds * 1e6) print( f"{variant.name:<16} {milliseconds:14.4f} {gigaelements_per_second:16.2f}" )def inspect_generated_assembly(asm_output_dir: Path) -> None: device = torch.cuda.current_device() asm_output_dir.mkdir(parents=True, exist_ok=True) assembly_rows: list[tuple[str, int, int, str, tuple[str, ...]]] = [] for variant in SIGMOID_VARIANTS: try: compiled_kernels = variant.kernel.device_caches[device][0].values() except (IndexError, KeyError) as error: raise RuntimeError( f"No compiled artifacts found for {variant.name}.") from error variant_count = len(compiled_kernels) for specialization, compiled_kernel in enumerate(compiled_kernels, start=1): ptx = compiled_kernel.asm["ptx"] sass = compiled_kernel.asm["sass"] if not ptx or not sass: raise RuntimeError( f"{variant.name} specialization {specialization} has an empty assembly artifact." ) for marker in variant.required_ptx: if marker not in ptx: raise RuntimeError( f"{variant.name} PTX is missing expected instruction: {marker}" ) for marker in variant.required_sass: if marker not in sass: raise RuntimeError( f"{variant.name} SASS is missing expected instruction: {marker}" ) key_sass_lines = tuple( next(line.strip() for line in sass.splitlines() if marker in line) for marker in variant.key_sass) file_stem = f"{variant.kernel.__name__}.runtime-repetitions" if variant_count > 1: file_stem += f".variant-{specialization}" ptx_path = asm_output_dir / f"{file_stem}.ptx" sass_path = asm_output_dir / f"{file_stem}.sass" ptx_path.write_text(ptx, encoding="utf-8") sass_path.write_text(sass, encoding="utf-8") variant_name = (variant.name if variant_count == 1 else f"{variant.name} variant {specialization}") assembly_rows.append( (variant_name, len(ptx), len(sass), file_stem, key_sass_lines)) print( f"\nGenerated assembly validation (files saved to {asm_output_dir}):") print( f"{'implementation':<18} {'PTX bytes':>10} {'SASS bytes':>11} {'checks':>8} artifact stem" ) for name, ptx_bytes, sass_bytes, file_stem, _ in assembly_rows: print( f"{name:<18} {ptx_bytes:10,} {sass_bytes:11,} {'PASS':>8} {file_stem}" ) print("\nKey SASS instructions:") for name, _, _, _, key_sass_lines in assembly_rows: print(f"{name:<18} {' | '.join(key_sass_lines)}")def parse_args() -> argparse.Namespace: parser = argparse.ArgumentParser(description=__doc__) parser.add_argument("--size", type=int, default=1 << 20) parser.add_argument( "--repetitions", type=int, default=128, help="Dependent sigmoid evaluations per element during benchmarking.", ) parser.add_argument( "--parity-size", type=int, default=1 << 20, help="Number of values used for the one-application parity check.", ) parser.add_argument( "--asm-output-dir", type=Path, default=Path("generated_asm"), help= "Directory where complete human-readable PTX and SASS files are written.", ) args = parser.parse_args() if args.size <= 0 or args.parity_size < 8 or args.repetitions <= 0: parser.error( "--size and --repetitions must be positive; --parity-size must be at least 8" ) return argsdef main() -> None: if not torch.cuda.is_available(): raise RuntimeError("A CUDA-capable GPU is required.") args = parse_args() print(f"GPU: {torch.cuda.get_device_name()}") print(f"PyTorch: {torch.__version__}; Triton: {triton.__version__}") check_parity(args.parity_size) benchmark(args.size, args.repetitions) inspect_generated_assembly(args.asm_output_dir)if __name__ == "__main__": main()
|
I run the Triton sigmoid comparison script in an NVIDIA PyTorch container nvcr.io/nvidia/pytorch:26.08-py3 on my local machine that has an NVIDIA GeForce RTX 5080 GPU (SM120).
|
12345678910111213141516171819202122232425
|
$ python triton_sigmoid.pyGPU: NVIDIA GeForce RTX 5080PyTorch: 2.14.0a0+4fdf77b940.nv26.08; Triton: 3.8.0Numerical parity against torch.sigmoid (one application, float32):implementation max abs error mean abs errortl.sigmoid 1.78813934e-07 7.29984739e-10PTX FTZ 1.78813934e-07 7.29984739e-10PTX tanh approx 3.87430191e-06 6.78930903e-08Instruction-throughput-bound benchmark (elements=1,048,576, repetitions=128, global traffic=8.0 MiB/kernel):implementation median (ms) G elements/stl.sigmoid 0.0832 12.60PTX FTZ 0.0790 13.28PTX tanh approx 0.0428 24.50Generated assembly validation (files saved to generated_asm):implementation PTX bytes SASS bytes checks artifact stemtl.sigmoid 9,406 2,160 PASS sigmoid_tl_kernel.runtime-repetitionsPTX FTZ 11,645 4,187 PASS sigmoid_ptx_ftz_kernel.runtime-repetitionsPTX tanh approx 10,900 3,780 PASS sigmoid_tanh_kernel.runtime-repetitionsKey SASS instructions:tl.sigmoid --:-:0:-:1 MUFU.EX2 R2, R4; | --:-:-:-:1 FADD R2, R2, 1; | --:-:0:-:1 MUFU.RCP R2, R2;PTX FTZ 33:-:-:-:1 FMUL.FTZ R6, R4, -1.4426950216293334961; | --:-:0:-:1 MUFU.EX2 R6, R6; | 01:-:-:Y:6 FADD.FTZ R4, R6, 1; | --:-:2:-:1 MUFU.RCP R4, R4;PTX tanh approx 33:-:-:-:1 FMUL R6, R4, 0.5; | --:-:0:-:1 MUFU.TANH R6, R6; | 01:-:-:Y:4 FADD R4, R6, 1;
|
In the performance benchmarks, we could see that the PTX tanh approximation achieves the highest instruction throughput, followed by the FTZ-based implementation, and finally the native tl.sigmoid. The PTX FTZ implementation is about 5% faster than the native tl.sigmoid, whereas the PTX tanh approximation is nearly twice as fast as the native tl.sigmoid.
In the numerical parity checks, we could see that the native tl.sigmoid and the PTX FTZ implementation have exactly the same numerical errors, this is because the difference in the subnormal values for sigmoid is too small to be meaningful in practice. The PTX tanh approximation, on the other hand, introduces a slightly larger numerical error. Whether it is acceptable depends on the specific application and the tolerance for numerical inaccuracies.
By examining the SASS instructions generated for each variant, we can understand how the high-level PTX or Triton code maps to the underlying hardware execution resources. This helps explain the observed performance differences in the benchmarks. In addition to a bunch of FADD and FMUL instructions handled by the FP32 ALU pipeline, the presence of MUFU.EX2, MUFU.RCP, and MUFU.TANH instructions indicates the utilization of the special-function pipeline (SFU) for transcendental operations.
| Variant | PTX Intent | Generated SASS SFU Operations | Main Conclusion |
|---|---|---|---|
tl.sigmoid |
Triton’s built-in sigmoid lowering | MUFU.EX2 +MUFU.RCP |
Compiler-generated implementation, including extra numerical handling |
| PTX FTZ | Explicit ex2.approx.ftz +rcp.approx.ftz |
MUFU.EX2 +MUFU.RCP |
The requested FTZ instruction sequence survived lowering |
| PTX tanh approx | Explicit tanh.approx.f32 |
MUFU.TANH |
Native approximate hardware tanh survived lowering |
Specifically, the major difference between the variants is that there are 2 MUFU instructions in the tl.sigmoid and PTX FTZ variants, whereas the PTX tanh approximation only has 1 MUFU instruction. This has a strong correlation with the observed performance differences, as the PTX tanh approximation can utilize the special-function pipeline more efficiently, leading to higher instruction throughput.
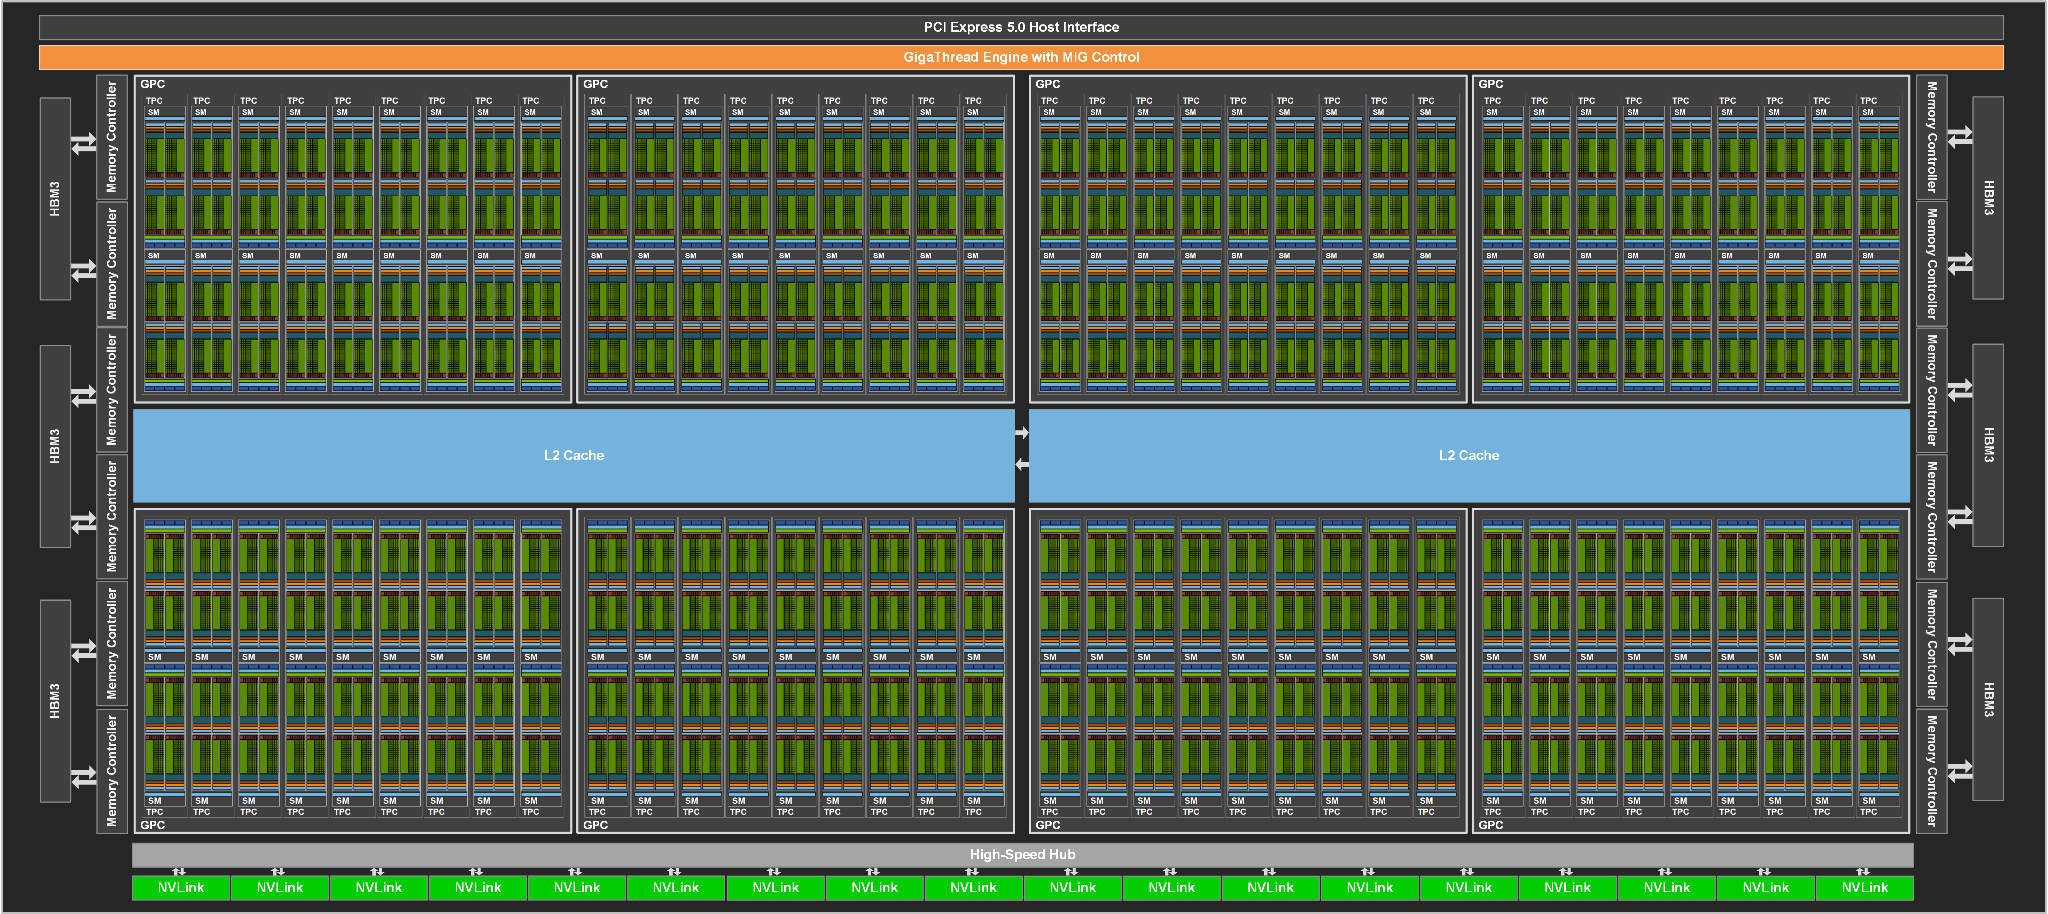
In GPU microarchitecture, different types of instructions are handled by different execution pipelines. For example, the following figure illustrates the NVIDIA GH100 architecture, GH100 SM microarchitecture, and its various execution pipelines on the chip.
Understanding which pipeline an instruction uses can help explain the observed performance characteristics of various implementations. Some of the common SASS instructions and their typical execution resources are summarized in the following table.
| SASS Instruction | Typical Execution Resource |
|---|---|
MUFU.EX2 ,MUFU.RCP ,MUFU.TANH |
Special-function pipeline / SFU |
FADD ,FMUL ,FFMA |
FP32 ALU pipeline / CUDA cores |
IADD ,IMAD ,ISETP |
Integer ALU pipeline |
FSETP ,FSEL |
FP32 compare/select logic or associated execution pipeline |
LDG ,STG |
Load/store pipeline and memory hierarchy |
Our benchmarking results with the SASS instruction analysis indicate that the performance of the sigmoid implementation variants is bottlenecked by the utilization of the special-function (SFU) pipeline, particularly the number of MUFU instructions and their impact on instruction throughput.
#
The performance difference between the various sigmoid implementation variants can vary depending on the GPU architecture and the Triton compiler translation decisions. On some GPU architectures, such as A100 (SM80), the PTX FTZ variant might perform better than the tl.sigmoid variant for about 10%. With different Triton versions, the translation of tl.sigmoid might change, potentially affecting the performance comparison between the variants.
#
CUDA Approximate Sigmoid