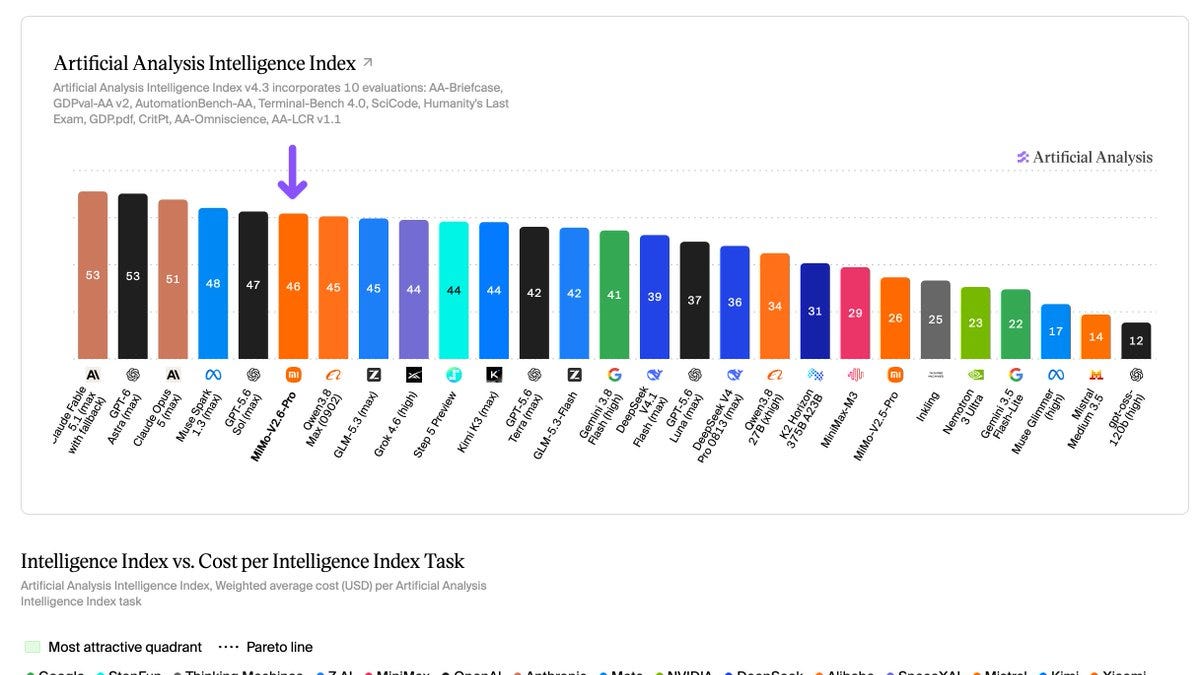
Meet Xiaomi and other top Chinese frontier labs at AIE Shanghai! This is a first for the “Apple of China” phone maker-turned-frontier lab: “The MiMo-V2.6 series includes two natively omnimodal models: MiMo-V2.6-Pro is our most capable model to date, while MiMo-V2.6-Flash strikes the best balance between intelligence, efficiency, and cost. We are also rolling-out MiMo-V2.6-Pro-UltraSpeed, delivering up to 20x faster output speed at the same quality, for users who require extreme generation speed.”
Xiaomi is not traditionally considered one of the six Chinese AI Tigers, so it is very surprising to the established order of names you have come to know and love. And… it is natively omnimodal!
Xiaomi made news a few days ago when Fuli Luo, a former DeepSeek star engineer now at Xiaomi, started publishing their final RL training runs live, which showed an abnormal amount of transparency in their internal metrics.
As they note in their technical report, they scaled RL compute along three axes:
- Larger batches and higher throughput : large batches on a fully asynchronous architecture, with 1,568 samples per update, training at up to 1M context length, and 3.5 to 3.7B tokens per step.
- More tasks and richer environments : a multi-task training suite spanning coding, general agents, visual and cyber, mixed across several harnesses so that gains in one capability reinforce the others.
- More grader compute : relative comparison within each group gives long-horizon RL tasks more precise and more diverse reward signals, closes a self-improvement loop, and steers the model toward shorter paths and fewer tokens per task.
ALL of this tooling, including the environments, will be open sourced.- the environment code and training recipes, but the complete 7k+ task datasets have not yet been released.
- **Coding / software engineering:**[Code recipes, dataset  and rewards](https://github.com/XiaomiMiMo/verl/tree/mimo-oss/recipes/code)
- **Cyber / vulnerability reproduction:**[ARVO environment and training recipe](https://github.com/XiaomiMiMo/verl/tree/mimo-oss/recipes/arvo)
- **General / knowledge work:**[General environment, tools and training recipe](https://github.com/XiaomiMiMo/verl/tree/mimo-oss/recipes/general)
- **Visual / web development:**[Web-development environment and grading](https://github.com/XiaomiMiMo/verl/tree/mimo-oss/recipes/design/webdev)
- **Music generation:**[Data preparation and music scorer](https://github.com/XiaomiMiMo/verl/tree/mimo-oss/recipes/design/music)
- **Composable mini-harnesses:**[Agent configurations](https://github.com/XiaomiMiMo/verl/tree/mimo-oss/config/agent)
- **Shared environment adapters:**[mimoagent environments](https://github.com/XiaomiMiMo/mimoagent/tree/mimo-oss/src/mimoagent/environments)
AI News for 9/19/2026-9/21/2026. We checked 12 subreddits, 544 Twitters and no further Discords. AINews’ website lets you search all past issues. As a reminder, AINews is now a section of Latent Space. You can opt in/out of email frequencies!
Open Models, Competition, and the China Gap
- Open models remain the central policy and market story :Nathan Lambert shared a congressional briefing on open-model performance, adoption, and U.S.-China competition, followed by apublic summary . The broader argument resurfaced elsewhere:@Yuchenj_UW claims frontier coding capability has plateaued sinceOpus 4.8 , while open-source models keep closing the gap at10–50x lower cost ;@ClementDelangue similarly argues APIs are overkill for many real-world use cases and that specialized models will take share. Counterpoint:@teortaxesTex argues frontier has actually split into new higher tiers, with internal models and top closed models still well ahead.
- The release cadence from Chinese labs is now difficult to dismiss :@Thom_Wolf compiled an unusually dense**~10-week run** of open releases includingKimi K3, Qwen3.8-Max, DeepSeek V4-Pro, GLM-5.3, Hy4 Preview, Atria Dawn , and more. This is reinforced by a Bloomberg-sourced note via@Polymarket that startups are increasingly building custom models on open weights to cut cost and reduce dependence on OpenAI/Anthropic. The subtext across several tweets: open-weight capability is no longer confined to midsized models; multiple teams are shippingfrontier-scale MoEs with credible cost-performance stories.
Xiaomi MiMo-V2.6 and RL as the New Scaling Lever
- MiMo-V2.6 is the biggest open-model release in the set :@XiaomiMiMo launchedMiMo-V2.6 Pro and Flash , described as open omnimodal models with weights, technical report, RL environments, and training code.Artificial Analysis saysMiMo-V2.6-Pro debuts as the top open-weights model on itsIntelligence Index (46) , with1.02T total / 42B active parameters and strong cost efficiency at**$0.435/M input** and**$0.87/M output** tokens.@victormustar notes the models are underMIT license .
- What stood out technically was not just the model, but the RL stack :@eliebakouch highlighted Xiaomi’s environment/data-factory paper for generating RL tasks from open repositories with “agents in the loop” for robustness and anti-cheating. Later commentary points to a second paper and unusually high transparency:@xeophon notes Xiaomi wants to release**~7K RL environments** , and@eliebakouch emphasizes the team shipped model + tech reportless than a week after the final RL run . A recurring interpretation, from@bertgodel and@Thom_Wolf , is thathigh-quality open RL environments may now be as strategically important as pretraining corpora were in the last cycle.
- RL cost/throughput details drew attention because they compress timelines :@zephyr_z9 cites130 hours ,75B tokens , and**$2.6M** for the RL run behind the result;@tianjun_zhang says the MiMo family scales RL onJAX + TPU , where scaling is “mostly a config change, not a code rewrite.” If these numbers hold up, the implication is that post-training/RL is becoming a far cheaper route to frontier-adjacent gains than many assumed.
Decision Models, Jev, and the Return of Specialized Inference
- Jev was the dominant product/theme discussion : Multiple posts converged on the same framing: this is “just” classification/routing, but with modern model intelligence and much better latency/cost.@karpathy calls it a point on the Pareto frontier for**“no thinking, single token, low latency acceptable intelligence”** .@willdepue describes it as azero-shot classifier with frontier-ish intelligence , while@ClementDelangue argues the excitement shows there is large latent demand for specialized models rather than ever-larger generalists.
- The ecosystem around Jev expanded quickly :@sarah_edo built a Chrome extension that uses Jev to select and fill relevant WebMCP tools per keystroke.LangChain addedJev-as-a-judge to LangSmith;@hwchase17 and@Hacubu pushedSemIf , an open-source decision model, through the LangSmith Gateway.@omarsar0 reports using Jev to retag**~2.3K papers** in83 seconds for $0.14 , with579 high-confidence changes and manual validation of disagreements.
- The more durable takeaway is architectural :DSPyOSS argues that asking frontier agents is like managing people, while hand-writing decision-model programs is analogous to writing assembly; both extremes are useful, but brittle if overused. Several posts emphasized where these models fit best: routing, approval gates, trace scoring, tool selection, discrete document decisions, and low-cost supervision inside larger agent loops rather than as standalone “smart agents.”
Inference, Tooling, and Systems Optimizations
- Tokenizer and post-training infra both got substantive upgrades : Hugging Face’stokenizers v1 RC claimsup to 30x faster tokenization , improved multithread scaling, lower memory use, and much smaller package size;@art_zucker framed it as a new SOTA tokenization library. Separately,Halo launched as a post-training framework claimingup to 2.8x throughput over stock TRL while keeping models in native Hugging Face format.
- Inference-side engineering remains a major lever :@RisingSayak showed how KV caching is incorporated intoQwenImage 2.1 , separating fixed context from changing image positions and yielding a2.55x speedup ; the thread cites50.57s → 19.86s DiT time on a warmed A100 with moderate memory overhead.vLLM published tuned serving configs forQwen3.8-2.4T onGB300 NVL72 , showing a Pareto frontier from5K total tok/s/GPU at high throughput to180 output tok/s/user at low latency. In video workloads,vLLM also integratedPyNvVideoCodec/NVDEC , removing CPU decode bottlenecks and reporting2x+ throughput at8×H100 .
- Compression/quantization is still moving fast :@ZhihuFrontier summarized Tencent Hunyuan’s engineering behind packingHy4 Preview (770B) into214 GiB via mixed-precision quantization averaging**~2.38 bits/weight** , including custom CUDA kernels in patched llama.cpp. On the edge/local side,@vikhyatk releasedParakeet Redux , compressing NVIDIA’s speech model from1.2GB to 178MB , running at113x realtime on CPU , while beating the base model on25-language FLEURS and staying within0.3 WER on English.
Agents, Security, and Human-in-the-Loop Control
- Computer-use systems are becoming more productionized, but security is now central :Patrick Wardle reported a serious local-hijack flaw inMuse , arguing broad OS access makes such assistants a high-value attack surface. In contrast,DeepLearningAI highlighted Meta’s design philosophy for Muse-like agents: assume prompt injection will happen, keep real credentials away from the model, isolate tools in containers, and use an independent outbound-call gatekeeper.
- Commercial agents are also being pushed deeper into workflows :Cognition introducedDevin Cloud in Terminal anddevin ssh , making the model’s VM directly accessible from the CLI and allowing handoff between Devin and the user’s machine.GitHub Copilot teasededitable diffs in the desktop app, while@pierceboggan showed a Sentry-integrated canvas for moving from crash report to fix.
- A recurring systems point: inference and agent infra are shifting toward test-time compute :@sarahookr predicts compute moving from pretraining—where marginal FLOPs yield less—totest-time compute , requiring “very different infrastructure.” That theme also showed up in persistent-cache discussions for local serving, e.g.@TheZachMueller on SGLang’s multi-levelhiCache (GPU/RAM/disk) for preserving KV cache across model swaps and restarts.
Top tweets (by engagement)
- Grok 4.7 release :SpaceXAI announcedGrok 4.7 , described as a notable improvement over 4.6 at the same price/speed. Follow-on evals were mixed:Artificial Analysis reported56 on its Coding Agent Index with gains on DeepSWE/Terminal-Bench/SWE-Atlas-QnA, whileVals saw it rank**#24** on its Vals Index,down 5 points from Grok 4.6 despite gains in legal/medical.
- OpenAI’s automated model-training workflow : A widely shared summary from@wallstengine reports that OpenAI has largely automated parts of training experimental models, including GPU kernel writing and code optimization, with internal agents collaborating and compressing some experiments from years to about a week.
- OpenAI mathematics advisory group and claims of solved open problems :OpenAI announced an independent advisory group of mathematicians to guide assessment and communication of AI advances in mathematics. Attention then shifted to the stronger claim, amplified by@AndrewCurran_ and others, that an internal OpenAI model has resolved100+ long-standing open problems across mathematics. This was among the most consequential but least independently evaluated items in the set.
- Open-sourcing of valuable data assets :@ClementDelangue highlightedEidon AI open-sourcing1,274 hours of egocentric robotics data (13,451 recordings ) as a rare case of a startup preserving impact for the community after shutdown.
/r/LocalLlama + /r/localLLM Recap #
1. Qwen-Image 2.1 and Tiny Open Image Models
- Qwen-Image-2.1 released! (Activity: 2485):Qwen-Image-2.1 was released with open weights as a unified 7B image generation/editing model, positioned as a faster, lower-cost member of the Qwen-Image series (blog, GitHub, Hugging Face). Key technical additions include native RGBA/transparent image generation and editing, support for up to 10 reference images, multi-image inference acceleration, and localized edit control for tasks like object removal, attribute changes, product/portrait-preserving edits, panoramas, infographics, typography, and virtual try-ons. Comments primarily highlight the native transparency pipeline and local-edit interface; one example uses colored circles to target three regions simultaneously for removal, hair recoloring, and clothing replacement, suggesting interest in more controllable multi-region editing workflows.
- Qwen-Image-2.1 is reported to addnative transparent image generation and transparent-image editing support, which is technically notable because alpha-channel workflows are often handled as post-processing or masking rather than directly by the image model. The linked example shows transparent-output capability:https://preview.redd.it/59fu834idoqh1.png?width=767&format=png&auto=webp&s=5fb81b135b35dac70f9d38a9995d7c1a7a2877dd
- The model appears to support multi-region local editing via visual annotations , where circled regions can be referenced in the prompt and edited simultaneously. One example asks it to*“remove the metal watch in the blue circle, change the hair in the red circle to black, and replace the area in the green circle with gray short-sleeved linen pajamas,”* demonstrating combined object removal, attribute modification, and region replacement in a single edit pass:https://preview.redd.it/cvh09tyvdoqh1.jpeg?width=1242&format=pjpg&auto=webp&s=32077f7420def5bec85160e2e982d6aef5efce54
- Several commenters highlight the model size: Qwen-Image-2.1 is described as
7Bparameters , which is significantly smaller than prior Qwen image models that commenters say wereover20B. This size reduction is viewed as important for local inference feasibility, with one user specifically noting interest from the perspective of a16GB VRAM GPU such as the RTX 5060 Ti 16GB.
- Clarification on the Qwen-image-2.1 license (Activity: 948):The image is a non-meme screenshot of a Qwen Developers X post clarifying that Qwen-Image-2.1 outputs are not considered licensed “Materials”, so users retain rights to generated images/content. This matters because the model license reportedly still contains a non-commercial restriction on use of the Materials, creating ambiguity over whether commercial image generation is allowed even if generated outputs are user-owned. Commenters welcomed the clarification, with one user saying Qwen-Image-2.1 “easily beats all current Flux models.” Another noted they can run it locally viaComfyUI int8 on a
16 GB RTX 5060 Tipeaking around15.2 GBVRAM, but warned the Hugging Face LICENSE file may not yet reflect the clarified intent.- A commenter reports running Qwen-Image-2.1 locally inComfyUI using
int8quantization on a16 GB RTX 5060 Ti , with VRAM peaking around15.2 GB. They describe the model as suitable for local testing but note that licensing uncertainty around generated outputs was the main blocker for broader/client use. - Several commenters highlight a legal/implementation mismatch: the Hugging Face README was apparently clarified, but the actualLICENSE file still contains Section
2(b)language prohibiting commercial “use” of the Materials. One user emailed[email protected] - The key technical/legal distinction being debated is whether “commercial use not allowed” applies only to serving, redistributing, or monetizing the model/materials , versus also restrictingoutputs generated by the model . Commenters argue that until the canonical license file is updated, downstream users comparing it with permissiveApache-2.0/MIT-style model licenses may reasonably avoid commercial workflows despite the clarification.
- A commenter reports running Qwen-Image-2.1 locally inComfyUI using


