GDM last shipped a larger-than-Flash model in February (3.1 Pro), and after successive incremental 3.x Flash versions and the big GDM management shakeup last month, the largest question for GDM was when they would catch up to peers who have in the meantime launched Fable and Astra class models.
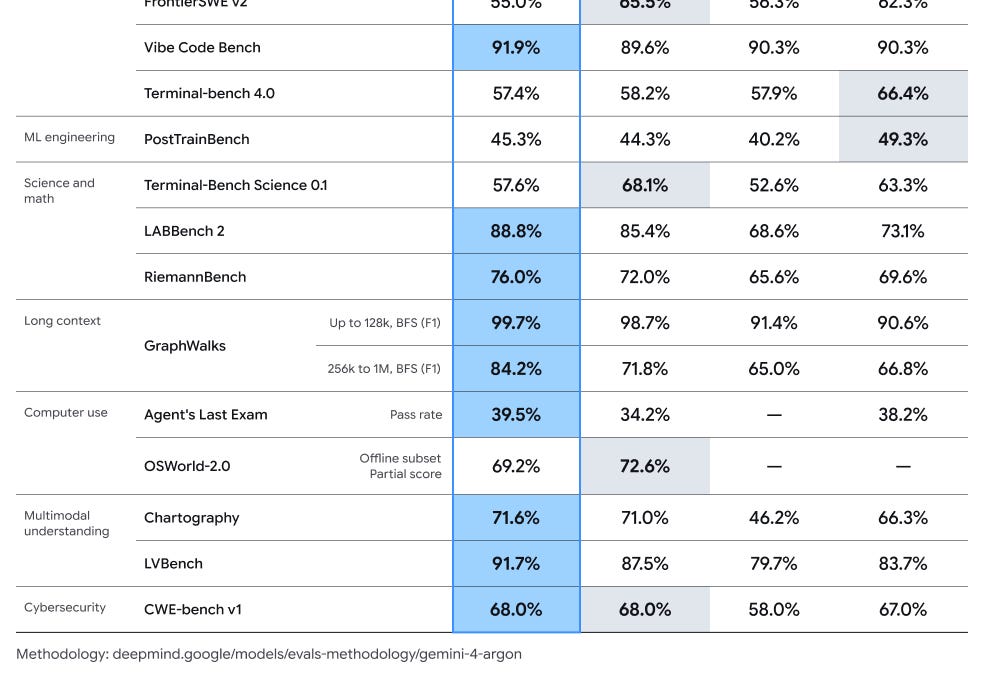
Well, Argon’s here, with VERY respectable benchmarks (SOTA in 13 of 19 credible benchmarks)… but only accessible in limited cybersecurity preview, though access is promised “as soon as possible”:
We like the experimental Long Decode Continuation, which increases output tokens up to 1M as an industry first.
AI News for 9/29/2026-9/30/2026. We checked 12 subreddits, 544 Twitters and no further Discords. AINews’ website lets you search all past issues. As a reminder, AINews is now a section of Latent Space. You can opt in/out of email frequencies!
Gemini 4 Argon: Google Returns to the Frontier
- Launch : Google DeepMind introduced Gemini 4 Argon for coding, enterprise knowledge work and cyber defense (@GoogleDeepMind ,@sundarpichai ).
- Availability : Access starts with government users and trusted cyber defenders in the Fairwind Program. Google says it will refine guardrails before opening access to developers, enterprises and consumers (@Google ,@demishassabis ).
- Output limit : Google cites an industry-leading 1M-token output limit, up from 64K (@GoogleAI ,@TheRundownAI ).
- Measurement note : Vals lists 262K max output. Artificial Analysis reached 1M output tokens through Long Decode Continuation, a new API feature that s long responses and resumes them across calls (@ValsAI ,@ArtificialAnlys ).
- Pricing : Standard pricing is $4/$20 per 1M input/output tokens. A 50% introductory discount brings it to $2/$10, with no end date announced. Cached input gets a 95% discount (@_philschmid ,@ArtificialAnlys ).
- Google’s claimed results : Argon takes first place on 13 of 19 published benchmarks against GPT-6 Astra and Claude Opus 5.5. On DeepSWE it scores 77.9%, versus 74.2% for Opus 5.5 and 74.1% for Astra (@TheRundownAI ).
- Internal deployments : Google reports that Argon agents freed more than 300 TiB of data-center memory and are migrating more than 800K lines of C/C++ kernel code to Rust (@kimmonismus ).
    - **Video decoder** : Agents replaced 32K lines of SIMD code with safe Rust, making the existing Rust port 2.7x faster with identical output.
  - **Research use** : The team says internal agent loops built on Argon helped complete the CK conjecture ([@mirrokni](https://x.com/mirrokni/status/2105500370675921213) ).
- Artificial Analysis evaluation : Argon scores 53 on the Intelligence Index, matching GPT-6 Astra (53) and edging GPT-6.1 Sol (52) (@ArtificialAnlys ).
- Cost per task : At discounted pricing it costs $1.99 per task versus $3.26 for Astra; standard pricing would raise this to $3.98.
- Token use : The savings come from price, not efficiency. Argon averages 62K output tokens per task against Astra’s 27K.
- Agentic work : It ranks #1 on AutomationBench-AA at 77.5% and scores 57% on Terminal Bench 4, behind Sonnet 5.5, Opus 5.5 and Astra.
- Hallucination : Its 15% rate on AA-Omniscience compares with 51% for Astra. The tradeoff is lower accuracy: 50% versus Astra’s 63% (@aipulseda1ly ).
- Cost per task : At discounted pricing it costs $1.99 per task versus $3.26 for Astra; standard pricing would raise this to $3.98.
- Vals evaluation : Argon is #1 on the Vals Index at 68.9%, at an average $15.68 per task (@ValsAI ,@ValsAI ).
  - **Efficiency** : It uses about a quarter of Sonnet 5.5’s output tokens on Vals Index tasks ([@ValsAI](https://x.com/ValsAI/status/2105388461402587198) ).
- **Arena and other evals** : Argon is #1 in Text Arena at 1525 and #8 in Code Arena WebDev at 1679 ([@arena](https://x.com/arena/status/2105394855644139908) ).
  - **Agent Arena** : It ranks #8 overall and #1 for steerability on a preliminary 3K sessions ([@arena](https://x.com/arena/status/2105411271525052418) ).
  - **PostTrainBench** : It scores 45.3%, up from 21.99% for Gemini 3.1 Pro ([@karinanguyen](https://x.com/karinanguyen/status/2105411208635711499) ).
- Skepticism : Some observers questioned the published numbers.
- Legal benchmark : Argon’s reported 19.6% on Harvey’s legal benchmark trails Muse Spark 1.2’s listed 25.42% (@BlackHC ).
- Other critiques : Commentators raised possible preference-data benchmaxxing and objected to some figures, including DeepSWE (@teortaxesTex ,@teortaxesTex ).
GPT-6.1 Sol and OpenAI’s DevDay Agent Stack
- **Independent evals** : GPT-6.1 Sol is the new #1 on MathArena ([@j_dekoninck](https://x.com/j_dekoninck/status/2105213644795523106) ).
  - **Code Arena** : It ranks #3 on WebDev at 1759, 70 points above GPT-6 Sol for the same $2/$10 pricing ([@arena](https://x.com/arena/status/2105367591174995999) ).
- Cost per task : Artificial Analysis measures $0.72 per task at max effort, versus $3.26 for Astra and $1.04 for GPT-6 Sol (@ArtificialAnlys ).
- Source of savings : Sol uses fewer turns and has a lower cache-read price (@ArtificialAnlys ).
- Luna bug fix : OpenAI fixed an image-encoding bug, adding 1 Intelligence Index point to GPT-6 Luna.
- Ultrafast inference : OpenAI quotes up to 300 tok/s. SemiAnalysis reports it runs on NVIDIA GPUs at low batch sizes, not on Cerebras (@kimmonismus ).
  - **Hands-on report** : Generation is about 8x faster, but end-to-end agent tasks speed up only 2–4x because tool latency dominates ([@sayashk](https://x.com/sayashk/status/2105472435390906634) ).
    - **Computer use** : Gains are largest here, since UI actions respond in milliseconds.
    - **Cost** : The tester exhausted a weekly limit in about 2 hours.
- Product layer : DevDay introduced dots (persistent agents with their own cloud computers), a Decisions API and computer use (@latentspacepod ).
- Sites : ChatGPT Sites can now host MCP servers and turn them into installable plugins (@mxstbr ).
- Usage limits : Users report one-off credits worth about $2,500. Others complain that usage limits were cut (@kimmonismus ,@kimmonismus ).
Other Releases: Embeddings, Image/Video and Open Models
- Perplexity contextual embeddings : pplx-embed-v2-context-9b-preview is open on Hugging Face (@perplexity_ai ).
- Method : The model encodes the whole document once and pools chunk vectors afterward. Training distills relevance from a context-compression model instead of using single gold-chunk labels (@denisyarats ).
- Results : It sets a new state of the art on ConTEB. On turbopuffer’s private context-bench it beats voyage-context-4 by 14.4 points in answer recall@10, using 1 KB int8 vectors against 8 KB (@turbopuffer ).
- Cohere Embed 5 : The family has Pro and Fast variants in a shared embedding space, so you can index with one and retrieve with the other (@cohere ).
- Fast tier : Cohere says it beats other fast-tier models by at least 6 points at a third less cost than Pro. Evaluation uses its new RCP-nDCG@10 metric (@cohere ).
- **Ideogram 4.5** : The editing model targets artifact-free multi-turn edits, with open weights promised ([@ideogram_ai](https://x.com/ideogram_ai/status/2105327223431737780) ).
- **Video benchmark** : Artificial Analysis launched AA-Video-T2V v2.0, judged at 1080p with more than 68K human votes ([@ArtificialAnlys](https://x.com/ArtificialAnlys/status/2105291240573190370) ).
- Leaders : Wan 3.0 is #1 at $12/min. Seedance 2.5 is #2 at $34.12/min, and MiniMax H3 is statistically tied at $4.80/min.
  - **Utopai X** : This post-train of MiniMax H3 debuts at #2 ([@ArtificialAnlys](https://x.com/ArtificialAnlys/status/2105343643251032304) ).
- **Open and small models** :
-
Ling-3.1-flash : A 500B model reported close to GPT-5.6 Sol and Opus 5 (@kimmonismus ). It ranks #2 among open-weight models in Mobile App Arena (@DesignArena ).
-
Praxis-1 : Runway released an open-weight world-action model and says robotics policy performance scales predictably with third-person video (@agermanidis ).
-
Solar Mini 4 : Upstage reports 35B total / 3B active parameters. It scores 24 on the Intelligence Index at $0.10/$0.40 (@ArtificialAnlys ).
- Caching penalty : It still costs about 5x Luna per task, because only 48% of its repeated context hits cache versus 99% for Luna (@ArtificialAnlys ). Agent Research, Inference and Systems
-
Context Language Models (Meta) : CLMs treat context as an editable file rather than an append-only log, with context-management policies learned in the weights and no external harness (@RulinShao ).
- Result : They score 65% higher with the same compute on a 24-hour multi-repository agent-swarm task (@arankomatsuzaki ,@natolambert ).
- **Adaptive reasoning compute** :
  - **TaH2** : Lookahead depth supervision teaches the model which hard tokens deserve another loop ([@ZhihuFrontier](https://x.com/ZhihuFrontier/status/2105165367891157032) ).
    - **Gains** : It reports +3.4pp accuracy at matched test-time compute and a 53% steeper scaling slope.
    - **Serving** : A MiniSGL integration batches requests at different loop depths together.
- AutoBenchmark (Meta) : The project automates benchmark creation. Human feedback at the ideation stage beats agents working alone, and difficulty transfers to held-out solvers (@jaseweston ).
- Stratego : A Nature paper presents the first superhuman Stratego AI, built on RL and test-time compute under imperfect information (@ssokota ).
- Prefill/decode disaggregation : A steady-state analysis argues that disaggregation raises mean interactivity by about 1/(decode-time fraction) at equal batch size and throughput (@ekzhang1 ,@cHHillee ).
  - **Implication** : It helps prefill-heavy workloads, not decode-bound low-latency serving.
- **Compilers and hardware** :
  - **DeepSeek on Huawei** : DeepSeek released an open-source Ascend toolkit with TileLang optimized for Ascend 950 ([@kimmonismus](https://x.com/kimmonismus/status/2105197839844303175) ).
-
AI as compiler : A model translates Triton directly to PTX, with a verifier checking correctness, races and deadlocks. Speedups on B200 reach 1.37x on FlashAttention (@Azaliamirh ).
-
Vera Rubin : Cognition is the first customer on Vera Rubin via CoreWeave, reporting about 4.8x the token throughput of GB200 at the same decode speed (@cognition ).
-
DFlash drafts : New draft models for Ornith-1.5 give up to 2.54x lossless speedups (@ornith_ ).
-
Agent sandboxes : Cloudflare rebuilt Containers for agents, with p50 time-to-interactive of 648 ms (6x faster) and snapshots in beta (@mgamache ).
- AutoRouter : Cloudflare’s model router showed about 30% lower spend in internal tests (@ashleypeacock ). Safety, Security and Eval Integrity
-
Reasoning extraction : OpenAI attributes a core part of a hidden-reasoning extraction campaign to individuals linked to Moonshot AI (@kimmonismus ).
- Scale : OpenAI recorded 16,000 attempts from more than 4,000 users in two days, with related activity across more than 15,000 users.
- External researchers : Their attacks kept working on Astra until this week. Patches were hard to propagate across product versions and third-party hosts (@JSchaeff3r ,@jonasgeiping ).
- Criticism : Nathan Lambert argues the vulnerability is the API provider’s responsibility (@natolambert ).
-
Distillation defenses : Defenses evaluated without later RL give a false sense of security. RL makes simple attacks effective (@shidan_javaheri ).
-
Embedded evaluations : Apollo Research published principles for outside evaluators who receive employee-like access to frontier labs (@ApolloResearch ).
- **Cyber evals** : On CyberGym-E2E-AA, some frontier models are safety-blocked on more than 85% of tasks ([@ArtificialAnlys](https://x.com/ArtificialAnlys/status/2105465206189195378) ).
  - **Cost** : GPT-6 Luna or MiMo-V2.6-Pro can run about 100 bug hunts in a 1M-line codebase for roughly $20.
- **Provenance and transparency** :
  - **SynthID Bio** : Watermarking for AI-generated proteins is published in Nature, with open-sourced tools ([@demishassabis](https://x.com/demishassabis/status/2105348732464070823) ).
  - **AI-detector evasion** : Opus 5.5 and Astra can rewrite more than 50% of a document without Pangram flagging it ([@ValsAI](https://x.com/ValsAI/status/2105456030746546448) ).
  - **Agent reports** : A new preprint asks how transparent LLM-written reports on agent work actually are ([@jennyihuang](https://x.com/jennyihuang/status/2105320921674203386) ).
Industry and Policy
- Factory vs Cognition : Factory removed advisor Chris Degnan, alleging he was confiding in Cognition while attending its board meetings (@matanSF ).
- Hire : Cognition announced Degnan as its CRO the same day (@cognition ).
- Denial : Cognition’s CEO says no Factory information was shared and that Degnan had resigned as an advisor on Monday (@ScottWu46 ).
- Political spending : Greg Brockman dropped a promised second $25M donation to the Leading the Future super PAC (@teddyschleifer ).
- Follow-up question : Alex Bores asked whether this also covers anti-regulation groups that don’t disclose donors (@AlexBores ).
- OpenAI finances : NYT reports OpenAI is near $70B in annualized revenue and in talks to raise $30B at a $1.4T valuation, with its IPO pushed to next year (@srimuppidi ).
- Funding : Flow, which builds AI tooling for hardware engineering, raised a $50M Series B at a $750M valuation (@parisingh ).
**Top tweets (by engagement)**

- [Gemini 4 Argon introduced; trusted-tester rollout via Fairwind](https://x.com/GoogleDeepMind/status/2105388084154056939) — 44.6K
- [Google: Argon with 1M output limit](https://x.com/Google/status/2105388143902175529) — 36.5K
- [Factory terminates advisor over Cognition conduct](https://x.com/matanSF/status/2105335179502064038) — 6.4K
- [Artificial Analysis: Argon matches Astra at 53](https://x.com/ArtificialAnlys/status/2105392625788637299) — 4.5K
- [Cognition CEO disputes Factory’s allegations](https://x.com/ScottWu46/status/2105360290993115469) — 3.8K
- [Ideogram 4.5 for precise multi-turn editing](https://x.com/ideogram_ai/status/2105327223431737780) — 3.2K
- [Arena: Argon #1 in Text Arena](https://x.com/arena/status/2105394855644139908) — 3.0K
/r/LocalLlama + /r/localLLM Recap #
1. GLM-5.3 Cyber Risk and Local Inference Support
- GLM-5.3 and the Spread of Advanced Cyber Capabilities \ Anthropic (Activity: 785):Anthropic reports that Zhipu/Z.ai’s open-weight GLM-5.3 crosses a notable threshold for autonomous cyber capability:
50/410end-to-end V8 exploits on ExploitBench, close to Claude Mythos Preview’s56/410, plus full control-flow hijacks on4%of Anthropic’s internal binary exploitation tasks where prior models were near zero. Anthropic frames the risk as capability + accessibility**: GLM-5.3 is widely downloadable, relatively cheap, and weakly refusal-tuned, with simple jailbreaks reportedly succeeding**64–100%of the time and “abliteration” dropping refusals to low single digits with little measured capability degradation. Top comments were largely hostile to Anthropic’s framing, arguing the post reads as an attempt to suppress a cheaper/open Chinese model near Anthropic’s frontier. One commenter emphasized legitimate defensive use, saying GLM-5.3 is their only practical tool for security testing and improving their own software.- Commenters highlight GLM-5.3 as a low-cost, less-restricted model perceived to be close to frontier capability, with one user framing it as useful for*“security testing and improvements on my own software”* rather than inherently malicious. The technical concern raised is that restrictions by providers likeAnthropic could limit defensive cybersecurity workflows that require models willing to analyze potentially sensitive exploit or vulnerability patterns.
- One commenter references prior GLM-5.2 models as having helped mitigate aHugging Face attack , contrasting that withClaude allegedly refusing assistance. The substantive point is that refusal policies may reduce utility in incident response or vulnerability remediation scenarios, while more permissive models can be operationally useful for defensive security tasks.
- add GLM-5.3-Flash (GLM5-Next) support by timkhronos · Pull Request #27773 · ggml-org/llama.cpp (Activity: 348):Merged
ggml-org/llama.cpp#27773adds GLM-5.3-Flash / GLM5-Next support tollama.cpp, enabling local inference for the 320B hybrid text+vision model. The implementation adds GLM-specific DSA indexing/pooling, hybrid indexed memory, and a newglm5vvision preprocessing/tower path, while reusing Kimi-K3 KDA layers, DeepSeek-style MoE/mHC helpers, MLA-only attention, and DSV4-style SwigLU clamping; validation reports random-model logits matching Transformers across prefill/ubatching/decode and vision embedding agreement around1e-5, with some precision-sensitive tensors left unquantized. Commenters were concerned thatllama.cppmodel support is lagging behind the pace of new experimental architectures, with one noting the effective bottleneck appears to be maintainer availability. A technical compatibility issue was also raised: existing Unsloth quantizations reportedly useglm5nextwhile mainline expectsglm5-next, so current mainline may fail to load those quants.- Commenters noted a compatibility issue between the Unsloth quantization PR and the mainline
llama.cppPR: one identifies the architecture/model type asglm5nextwhile the other usesglm5-next, meaning mainlinellama.cppmay fail to load existing Unsloth GLM-5.3-Flash quants without conversion or metadata fixes. - There was concern that
llama.cppsupport is lagging behind the pace of new model releases, especially as newer models increasingly use experimental architectures that require bespoke /runtime changes before inference and optimization work can land. One commenter framed GLM-5.3-Flash support as taking roughly*“another month”* after model release, with progress depending heavily on a small number of maintainers.
- Commenters noted a compatibility issue between the Unsloth quantization PR and the mainline