In today’s issue:
- Anthropic ships Claude Opus 5.5
- OpenAI launches GPT-6 Sol and Luna
- Xiaomi open-sources MiMo-V2.6
- StepFun previews Step 5
- Claude agents find a new enzyme
- Google open-sources AX
- Prime Intellect launches Sandboxes
- Agensh scales to 1,024 agents
- xAI releases Grok 4.7
- Research agent rewrites its own code
And all the top AI dev news, papers, and tools.
Top Stories #
Claude Opus 5.5
Anthropic released Claude Opus 5.5, the first model in its Claude 5.5 family. It performs at the level of Claude Fable 5.1 on most tasks and costs about 40% less to run than Opus 5 on typical workloads.
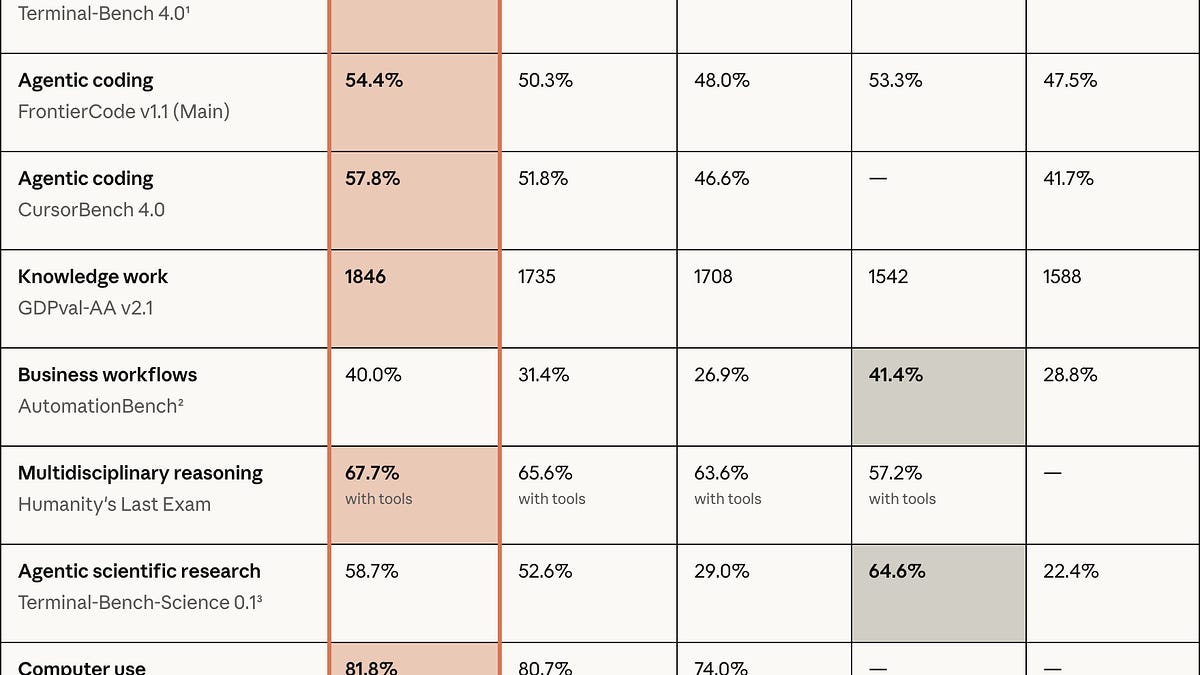
- Agentic coding: 66.4% on Terminal-Bench 4.0 against 55.8% for Fable 5.1 and 57.9% for GPT-6 Astra, plus 54.4% on FrontierCode v1.1 and 57.8% on CursorBench 4.0.
- Computer use and knowledge work: 81.8% on OSWorld 2.0 and a GDPval-AA v2.1 Elo of 1846, the top score in Anthropic’s comparison. GPT-6 Astra still leads on AutomationBench (41.4% against 40.0%) and Terminal-Bench-Science.
- Pricing and speed: $4 input and $20 output per million tokens, down from $5 and $25, with cache reads cut from $0.50 to $0.20. Output is more than 30% faster than Opus 5, and a fast mode offers up to 2.5x speed at $8 and $40.
- Alignment: Anthropic reports its strongest result yet on its automated behavioral audit, and Opus 5.5 attempted to circumvent boundaries about 85% less often than Opus 5.
- Availability: Live as
claude-opus-5-5on the Claude Platform, AWS, Google Cloud, and Azure, with higher five-hour usage limits on Pro, Max, Team, and seat-based Enterprise plans.
GPT-6 Sol and Luna
OpenAI added GPT-6 Sol and GPT-6 Luna to the GPT-6 family, training them with methods similar to GPT-6 Astra and cutting API prices by 50% against GPT-5.6 promotional pricing.
- Pricing: Sol drops to $2 input and $10 output per million tokens, and Luna to $0.10 and $0.50.
- Business workflows: On AutomationBench, which tests end-to-end workflows across 47 tools, Sol at xhigh effort scores 33.2% at $0.27 per task, ahead of Claude Opus 5 at max effort (26.9%) at 9% of its cost per task.
- Coding: Sol at max effort scores 68.8% on DeepSWE v1.1, within 1.1 points of Claude Fable 5’s 69.9%, at about 80% lower cost per task. Luna reaches 66.6% at 93% less per task than Opus 5.
- Caching for agents: Prompt caching now gets higher hit rates by default with a 90% discount on cached reads, and changing reasoning effort or toggling tools mid-conversation no longer breaks the cache. GitHub reports over 50% fewer prompt tokens needing fresh processing.
- Availability: In ChatGPT Work and Codex for Plus, Pro, Business, Enterprise, and Edu users, and in the API as
gpt-6-solandgpt-6-luna.
source & further reading
nlp.elvissaravia.com — original article
🤖 AI Agents Weekly: Jev, Salesforce Koa, Claude Code Projects, Anthropic R&D Metrics, Periodic Neon, Gemini 3.8 Live, and More
🤖 AI Agents Weekly: OpenAI Agents API, Cognition SWE-2, DeepSeek-V4.1-Flash, Cursor Projects, Sakana Fugu Max, Meta Muse, and More
AI Agents Weekly: GPT-6 Astra, Claude Fable 5.1, Gemini 3.8 Flash, NVIDIA Buys Hugging Face, Grok Bot Design, FrontierHarness Eval, and More