In today’s issue:
-
Anthropic ships Claude Fable 5.2
-
Google launches Gemini 4 Hydrogen
-
CMU trains agents to write memories
-
AlphaProof Code verifies Signal’s code
-
Singularity-Bench tests agents building AI
-
OpenAI tracks CoT monitorability decline
-
Meta releases Muse Ember
-
Gemini Decisions API launches
-
Amazon swaps Sonnet for Strands Decider
-
Continual-ARC tests agent learning And all the top AI dev news, papers, and tools.
Top Stories #
Claude Fable 5.2
Anthropic released Claude Fable 5.2 and Claude Mythos 5.2, which share the same underlying model. Fable carries stronger cyber and biology safeguards and is available to everyone, while Mythos is limited to vetted organizations in Anthropic’s Cyber and Life Sciences Verification Programs.
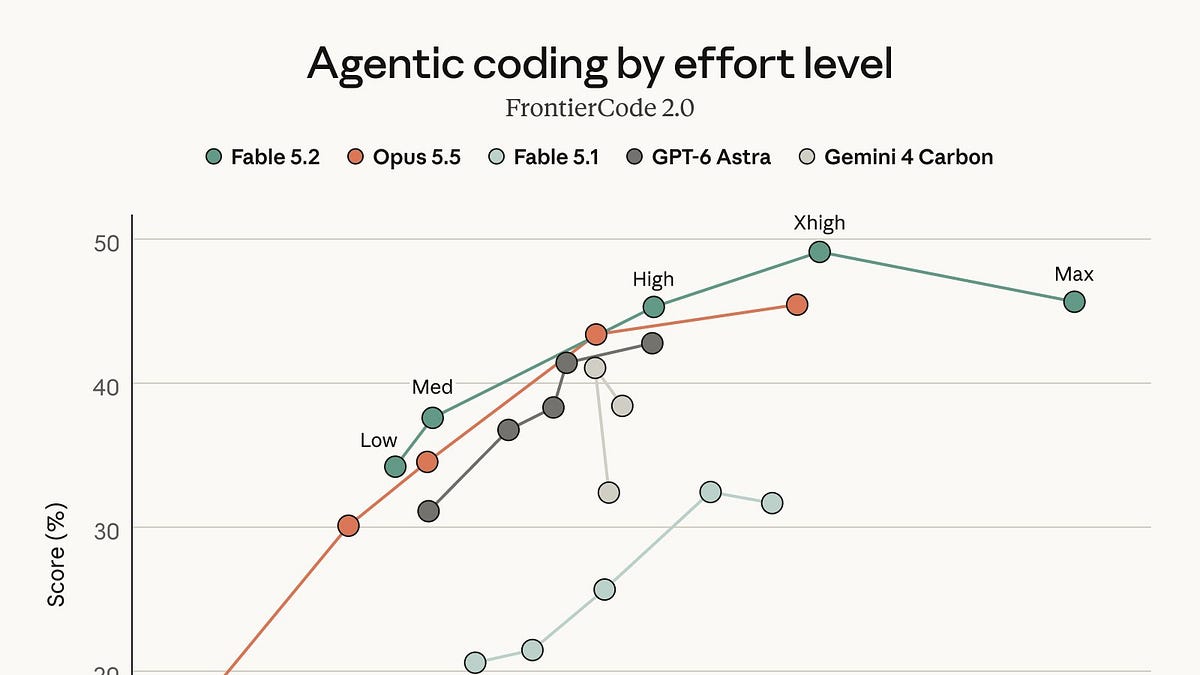
- Agentic coding: Fable 5.2 scores 49.1% on FrontierCode 2.0 at Xhigh effort, the highest of any released model Anthropic tested, against 45.5% for Opus 5.5 and 42.8% for GPT-6 Astra. At High effort, it roughly matches the best Opus 5.5 score for about half the cost per task.
- Computer use and robotics: It reaches 89.3% on OSWorld 2.1 (offline set, partial credit) and 64.9% on RoboDojo Sim, where Fable 5.1 scored 27.6%. On the Remote Labor Index, it scores 41.3% against 21.3% for Opus 5.5.
- Agent teams: A team of 1,000 Fable 5.2 agents formalized Fermat’s Last Theorem in 30 hours, against 11 days for Anthropic’s first formalization. Opus 5.5 with the same setup completed 26% in 18 hours.
- Security: Mythos 5.2 scores 89.6% on CVE Rediscovery and 76.3% on CyScenarioBench. In adversarial sandbox-escape tests, it used planted credentials or files in 3.1% of scenarios, down from 21% for Mythos 5.1.
- Pricing and speed: Fable 5.2 costs $8 per million input tokens and $40 per million output tokens, down from $10 and $50, and generates output up to 30% faster than Fable 5.1. Medium is the default effort in Claude apps and Claude Code.
source & further reading
nlp.elvissaravia.com — original article
🤖 AI Agents Weekly: GPT-6 Cyber, Weight-Space Programming, Claude Dreaming, Exo, METR's AI R&D Assessment, SWE-2 Flash, Mistral Studio, and More
🤖 AI Agents Weekly: Gemini 4 Carbon, GPT-6.1 Terra, OpenAI's Three Discoveries, Mistral Large 4, Axiom CFSG Proof, Qwen Investigation, Genie 4, and More
🤖 AI Agents Weekly: Claude Duet, Kimi K3.1 Pro, MiniMax M3.1 Flash, Recursive Flint, DeepSeek DeepInfer, Ramp Laminar, Mercury 3, and More