I would not have expected a merge queue to become something I needed for a personal project. How much coordination could merging a few pull requests require? After all, there is only one of me. Well, not anymore. The repository might be personal, but I am no longer its only contributor.
I have been building Spool, a tool to create, manage, and communicate with persistent Claude Code loops. I also use those loops to develop Spool itself. Several agents work on different tasks while I review the direction and decide what should merge. This gives me more work happening in parallel. It also gives me several pull requests waiting to enter the same branch. And that is where a fairly ordinary Git setting became surprisingly inconvenient.
As you can imagine, agents can create pull requests quite fast. For example, you are so likely to have two approved pull requests, A and B. Both have passed CI against the same version of main. You merge A, and B is now behind. The agent authored B needs to rebase it, push it, and wait for CI again before it can merge.
Now imagine a few more PRs arriving while this happens.
The repeated coordination around the PRs get tiring. A reviewer would ask an author to rebase, the author would update the branch, and eventually the PR would come back to me for merging. On some days, most of merge asks from my agents were waiting on one of these round trips.
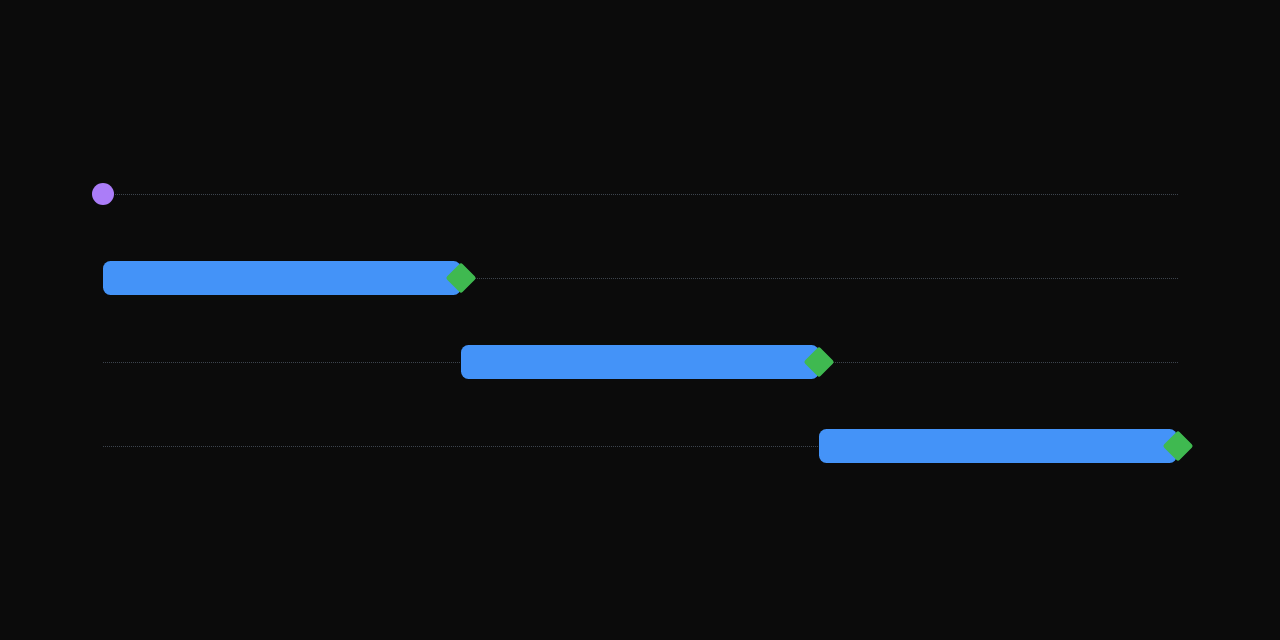
I wanted to make the merge decision once, then let the machinery handle the waiting. Is not that just a merge queue I need? It validates changes against the target branch and the changes ahead of them in the queue, then merges when the required checks pass. Authors do not have to keep updating their branches just to get their turn.
There was one detail, though. At the time of writing, GitHub’s native merge queue is available for organization-owned public repositories, or private organization repositories on GitHub Enterprise Cloud. Spool lives under my personal account.
Moving the repository to an organization was an option. But it would also mean thinking through the other things like Go module path, container image namespace, and release attestation identity. Those are manageable changes, but you can’t possibly create organizations for each of your personal projects again and again.
So I decided to build a small one with GitHub Actions thanks to my little minions who make such things very easy to build.
A PR enters the queue when it has both a queue label and auto-merge enabled. In my workflow, the reviewer, often another agent, adds the label with their approval, and I enable auto-merge. This keeps my decision in the process, while allowing me to make it before the final test finishes.
The queue then does the following:
- Picks an eligible PR and records its head commit and the current
maincommit. - Rebases that exact PR onto that exact base inside the CI runner.
- Runs the existing CI workflow against the resulting tree.
- Checks whether the PR, base, label, and auto-merge setting are still unchanged.
- Publishes a
queuestatus: green if the tests passed and those conditions still hold, red if the tests failed.
The rebase stays inside the runner. Nothing is pushed back to the author’s branch. GitHub’s ordinary auto-merge performs the actual merge once the required checks allow it.
That last distinction matters. The script selects and validates candidates; it does not run a merge command itself.
Every other open PR gets a status too, so a glance at a PR’s checks says where it stands:
queue — pending: testing on main@4f1c2a9
queue — pending: queued at 2, behind #841
queue — pending: not queued: waiting for auto-merge
The queue has no gates of its own. It calls the same CI workflow every PR already runs, so there is no second set of gates to keep in sync, and it gets the same shortcuts for free: path filters, and skipping the seven-minute integration suite when the code it covers hasn’t changed since the queue last tested it.
The harder part is that things change while a runner is busy. An agent might push to its PR after approval. Even a small change, even a rebase to fix a conflict, means the PR is no longer the version that was reviewed. GitHub keeps auto-merge on when someone with write access pushes, and my agents have that access. So an unqueue workflow removes the label and turns auto-merge off on every push, and the PR has to be approved and queued again. main can move too, which is why the run checks the state again before it reports: a result from an old main or an old head never turns a PR green.
Permissions needed care as well. The job that runs the PR’s code has a read-only token, and the jobs that publish statuses run scripts from main. A PR’s own label events only mark the queue and hand the run over to main, so a PR is always tested under main’s gates, never ones it edited on its way in. But of course, none of this stops someone with write access from writing a status. That was always possible. What it stops instead is the queue’s own test job, which runs the PR’s code, from writing its result. A PR that edits a workflow could still post a green status for itself, so the real guard there is the reviewer, who reads workflow changes before adding the label.
One GitHub Actions rule shaped more of the design than I expected: what a workflow does with its own token doesn’t start other workflows. When unqueue takes a PR out, its label removal triggers nothing, so it has to start the next queue run itself.
The order is simple: lowest PR number first, except that a PR already under test, or already green on the current main, keeps its place, so a test in progress is never thrown away. Only one PR is tested at a time. GitHub’s native queue can test A and A+B together; mine waits for A to land before testing B. That costs throughput, but the handoffs were the problem I needed to solve.
Here is a small model of the queue you can play with. It follows the same rules as the script, down to the status texts.
I also wanted to see what was happening without opening several workflow runs. A pinned GitHub issue became the noticeboard: which PR is under test, which ones are waiting, and which failed. The workflow updates its body from the same statuses shown on the PRs. It was enough for the visibility I needed.
There are still of course rough edges, and I would not describe this as equivalent to GitHub’s native queue. For example, a failed candidate gets a red status, and the next queue run skips it. But publishing that failure does not itself start another run; that is the same token rule again. If no other event arrives, the remaining PRs can wait until a manual dispatch or another queue-triggering event. That is a gap in how the queue keeps moving.
There is also a boundary between checking that main has not changed and GitHub actually merging the PR. Those are separate operations. With “up to date” switched off, a green status earned on an older main can still merge if main moves by some other route before the next queue run marks the PR pending again. Changes to main outside the normal queue path need particular attention.
These details are easy to miss when the initial idea is simply “test them one by one.” The queue is small, but it still has to deal with changing state, permissions, failures, and recovery.
What I find interesting about this experience is how little the personal ownership of a repository says about its development process nowadays, with AI agents working on it too. Spool made it easier to keep several pieces of work going, and with several agents contributing, merging them became the coordination problem I used to associate with a larger team.
If you are curious about the implementation, the design decision explains the choices, and the queue script contains the selection and reporting logic. GitHub’s native merge queue documentation is also worth reading, especially if your repository can already use it.
Thank you for sparing the time to read. If you are developing with several agents, I would be really interested to hear how you handle the point where their work needs to come together.