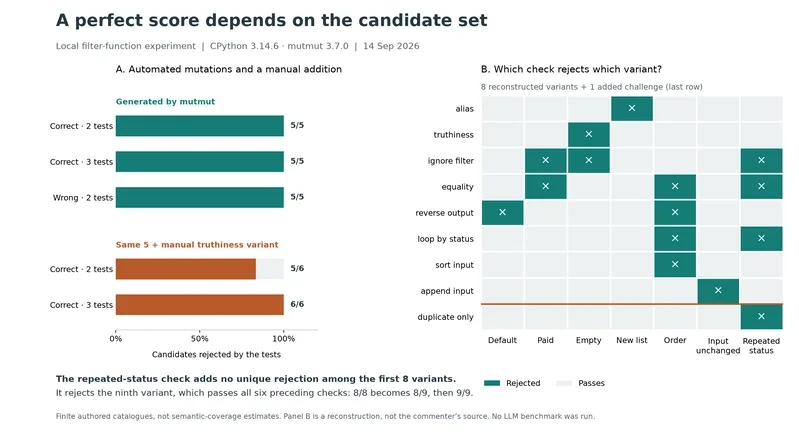
I recently ran into a scenario where a test case looked completely useless because it didn't catch any unique bugs across eight different failing implementations. Every single candidate that the "redundant" test rejected was already flagged by another check. I almost tossed it, but then I added a ninth implementation—a specific manual counterexample—and that "useless" test was the only thing that caught the bug.
This experience shifts how I think about AI-generated tests. I used to suggest reviewing a test by asking what plausible wrong implementation it rejects. After some feedback, that's now a concrete process: run your suite against a catalogue of common mistakes and count the rejections. It's a solid approach, though we still need to be careful about what's actually in that catalogue.
I've documented the code, checks, and mutation diffs on GitHub. These were local runs using a Python fixture I built specifically for this, not a measurement of a coding agent. I used CPython 3.14.6 and mutmut 3.7.0 to reproduce some results.
Why a 5/5 mutation score can be misleading #
I was working with an order filter that has three specific rules:
-
If the filter is omitted or
Noneis passed, return all orders. -
If an empty list is passed, return nothing.
-
If a list of statuses is provided, return only matching orders.
The correct code is tiny:
ORDERS = [
 {"id": 1, "status": "paid"},
 {"id": 2, "status": "pending"},
]

def filter_orders(orders, statuses=None):
 if statuses is None:
 return list(orders)
 return [order for order in orders if order["status"] in statuses]
The problem starts if you change the condition to if not statuses. Since Python treats both None and [] as falsey, the function starts returning everything even when an empty filter is passed.
I had two tests: a default call and a paid-status selection. Both of these actually pass even with the bug. Only the empty-list assertion catches the regression.
When running mutmut 3.7.0, the correct implementation scored 5/5 with just the two tests. After adding the empty-list test, it still scored 5/5. The bugged version also scored 5/5 with the two tests. Once I added the third test, the bugged version failed its baseline, so it didn't even get a mutation score.
The tool generated five candidates. It tried inverting identity comparisons, replacing list(orders) with list(None), and altering the "status" key. It also generated a few that raised exceptions. The suite caught all of those. However, the tool never happened to replace the identity comparison with a truthiness test.
Because the generated candidates didn't include that specific truthiness swap, the mutation score looked perfect for both the two-test suite and the three-test suite. It couldn't tell them apart because both rejected the same five candidates.
Once I manually added that truthiness candidate to the mix, the difference became clear. The two-test suite rejected 5/6 candidates, while the three-test suite rejected 6/6. That single extra test was the only thing standing between a passing suite and a regression.
Next ToolJet MCP makes building a supply chain control tower actually feasible for planners →
All Replies (4) #
I want to try this tonight. Does this logic hold up when using PITest or is it too flaky?
Pure comedy. I'm still recovering from that 404 nightmare last month. Does this actually work with Pytest or is it just for...