For the micro1 eval hackathon, I spent 26 days trying to beat frontier AI with my own taste. I make YouTube videos with a crew of coding agents. They send proposals to a page on my phone, and I tap a button: use it, edit it, or kill it. I wanted to show that a model that knows my taste beats a frontier model in raw mode, the plain model with nothing about me. I did not beat it. Here is every eval, short, with what I said at each turn. Times are Paris time, and my words are quoted as I typed them.
phase one, 14 to 18 Oct: puzzles #
Seven puzzle tests on Claude Opus, Fable and Haiku: pick a winning bid, find the current decision, find tests that cannot fail, read a video edit timeline, track a long timeline, an escape room, a bill split. The models passed. Fable got every case it was given right, up to a 250 step timeline. At 500 steps it ran out of room and never answered.
On 17 Oct: “5 havent killed any idea so far, its not just havent found the one”. On 18 Oct at 22:25: “Micro1 noo we havent figure it out”.
A frontier model solves a well specified puzzle. So I stopped making puzzles.
phase two, 19 to 22 Oct: my own decisions #
On 19 Oct at 22:38: “Micro1 MY complains, MY DATA we can beat the frontier models for sure”.
The first test looked like a win. Opus predicted my ruling on 3 of 8 proposals in raw mode, and 5 of 8 with 80 of my earlier rulings. Then we froze 24 decisions and ran it again. Opus scored 13 of 24 with and without my history. History changed none of its answers. On a fresh set of 12, neither Opus nor GPT found a single edit or kill.
On 21 Oct I widened it: “ok maybe the EVAL can have all 3 of them? as a PM expertise? that would be the most fun no”. We called it Shipometer: would a product manager use it, edit it or kill it? 11 models, 62 items. The best was Gemini at 45% balanced accuracy, against 33% for always saying “use it”. Most models said “edit” on about nine items in ten. A phone game on 3 pairs of screens told the same story: the 11 models gave the screen I kept and the screen I sent back the same verdict 31 times out of 33.
On 22 Oct at 08:43 I saw the catch: “if no contexts its just a personal oscar morkeeth EVAL not PM or Taste.”
phase three, 30 Oct to 7 Nov: the hackathon #
Kickoff was 30 Oct. “spend 10 bucks if you need yes”.
Made-up taste profiles: every model 12 of 12. My verdicts as text: the answer choices gave the answer away. Small proofs of concept: 15 of 15, or a broken answer key. Fifteen feedback tasks: 135 of 135. On 1 Nov at 18:13: “micro1 eval im not sure we’re tackling from the right way”.
The closest I got was thirty real cards from my panel. My setup lifted Opus from 39 to 53 of 90, and lifted GPT and JEV too. But Gemini in raw mode, knowing nothing about me, also got 53.
Then the search. A study on new cards never got enough cards. A location test was dropped, because its data was licensed for another hackathon. Landing page taste was never run: “the scary part is: is this just the unslop skill? might not be the winne then”. Seven real taste cases ended in a tie with a bot that always says “edit it”, 4 of 7. At 23:44 on 7 Nov: “i think beating the frontier can be a valuable reserach paper and article”.
phase four, 8 Nov: the button I pressed #
Every earlier test broke the same three ways: too easy, a wrong key, or too few new cases. The button I actually press has none of those problems.
Study A, 31 decisions, raw mode: Opus 14, GPT 12, and a bot that always says “use it” 17. Study B, 34 new decisions: the bot 16, Opus 16, GPT 17 in raw mode. With my history: Opus 10, GPT 14. I ran both studies twice more with the same requests. History lowered the score in every run, for both models.
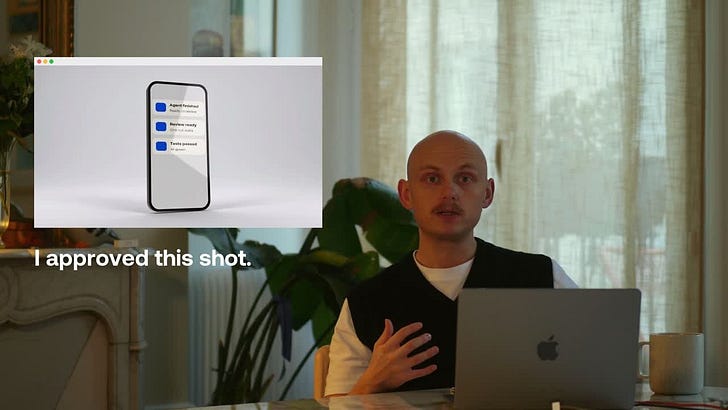
Why? With my history, the models said kill far more often: Opus 10 or 11 times a run, GPT 8. I pressed kill 3 times. One card was a short shot of phone notifications that I approved. Opus killed it in history mode, pointing to my note on a different clip:
slightly boring with the white panels
My note was about one clip. The model read it as a law.
so how do you beat a frontier model? #
Not by pasting your history in. In 27 tries, my context looked like it helped three times, and none of them held. A frontier model in raw mode is a strong default. What no model could do, in any of the 27 tries, was tell when I would kill something, or what I would change. The next thing I build has to learn when a complaint applies, not just that I made one.
Every number from the final studies replays with no API key: github.com/Morkeeth/micro1-owner-taste-eval The full story, every try with its model, sample, score and source file, is on Oscar Labs.